- The paper presents a novel two-stage synthesis framework that scales simple MCQs with visual data and hardens them into multi-hop reasoning challenges.
- It leverages multimodal models like VLMs and reasoning LLMs to simulate cognitive behaviors such as verification, backtracking, and correction.
- Experimental results demonstrate enhanced cross-modality transfer and superior benchmark performance compared to current state-of-the-art models.
Long Grounded Thoughts: Distilling Compositional Visual Reasoning Chains at Scale
Introduction
The paper "Long Grounded Thoughts" introduces a novel framework for synthesizing large-scale vision-centric reasoning datasets with compositional complexity, utilizing multimodal models like VLMs and reasoning LLMs. The proposed approach seeks to generate diverse and complex multiple-choice questions (MCQs) through a robust two-stage synthesis process, focusing on scale and compositional hardening, which aims to push the limits of existing open-source models. The framework's ultimate goal is to enhance the reasoning capabilities of vision-LLMs by distilling cognitive behaviors such as verification, backtracking, and correction.
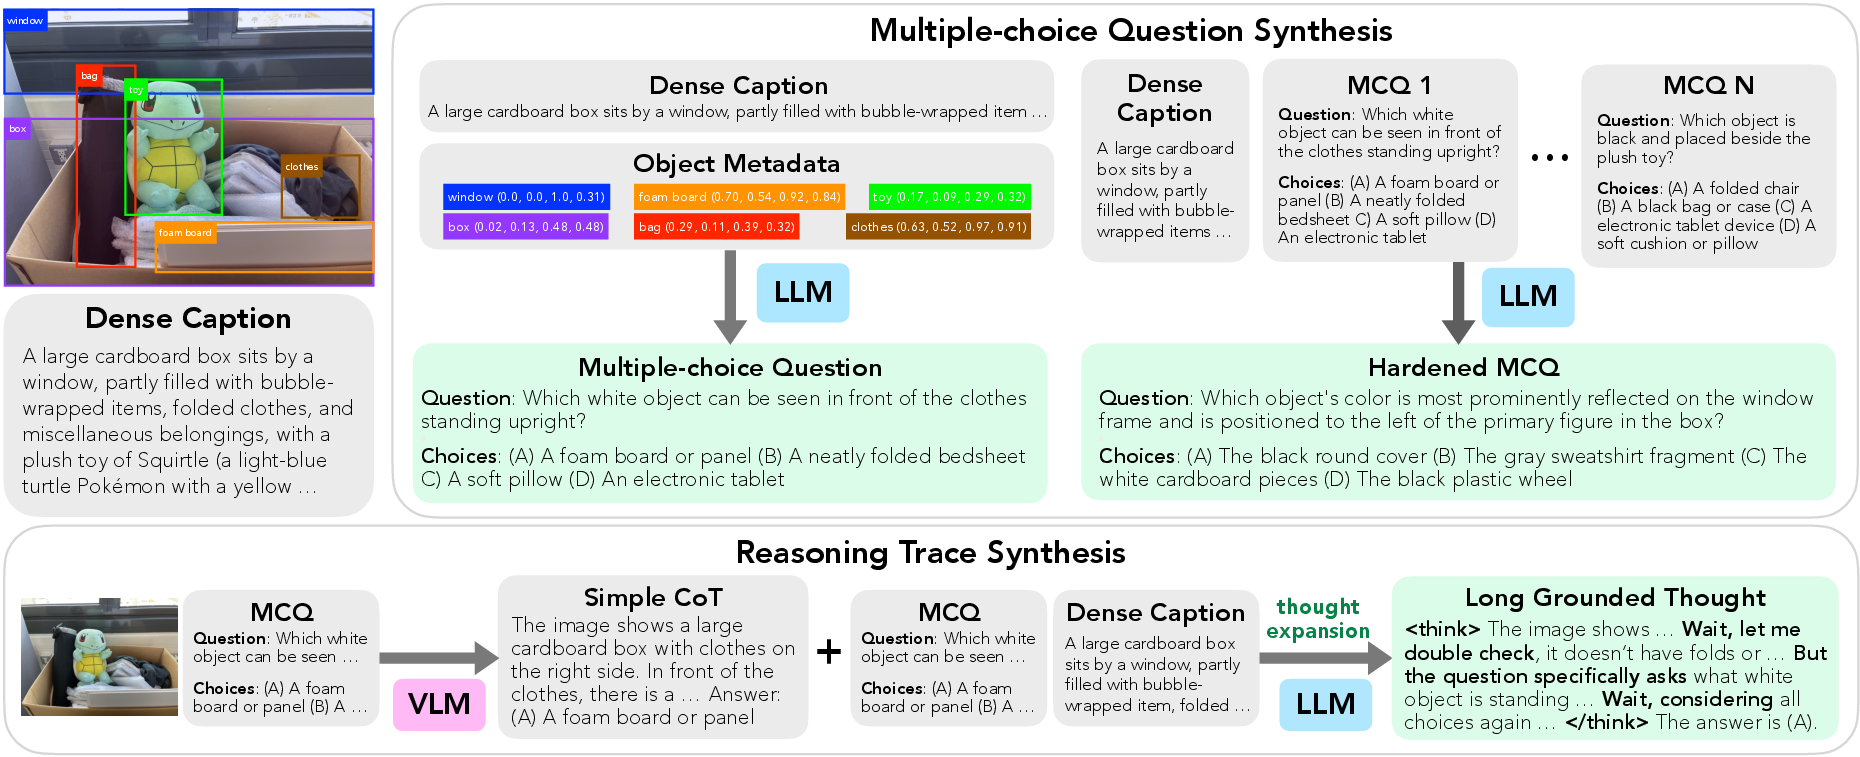
Figure 1: Overview of the two-stage synthesis framework, progressing from scale to complexity in visual reasoning data generation.
Two-Stage Synthesis Framework
Stage 1: Scaling and Diversity
The initial stage of the synthesis framework focuses on generating extensive sets of MCQs from dense image captions and grounded object metadata. By incorporating bounding boxes and descriptive text, the framework emphasizes diversity and depth in cognitive tasks, such as verification and correction. This stage constructs simpler questions that rely heavily on visual data synthesized from models such as Grounded-Segment-Anything [ren2024grounded].
Testing scalability, the researchers observed that naive scaling saturates quickly in terms of diversity, which was mitigated by incorporating object-level metadata to condition MCQ generation Figure 2.
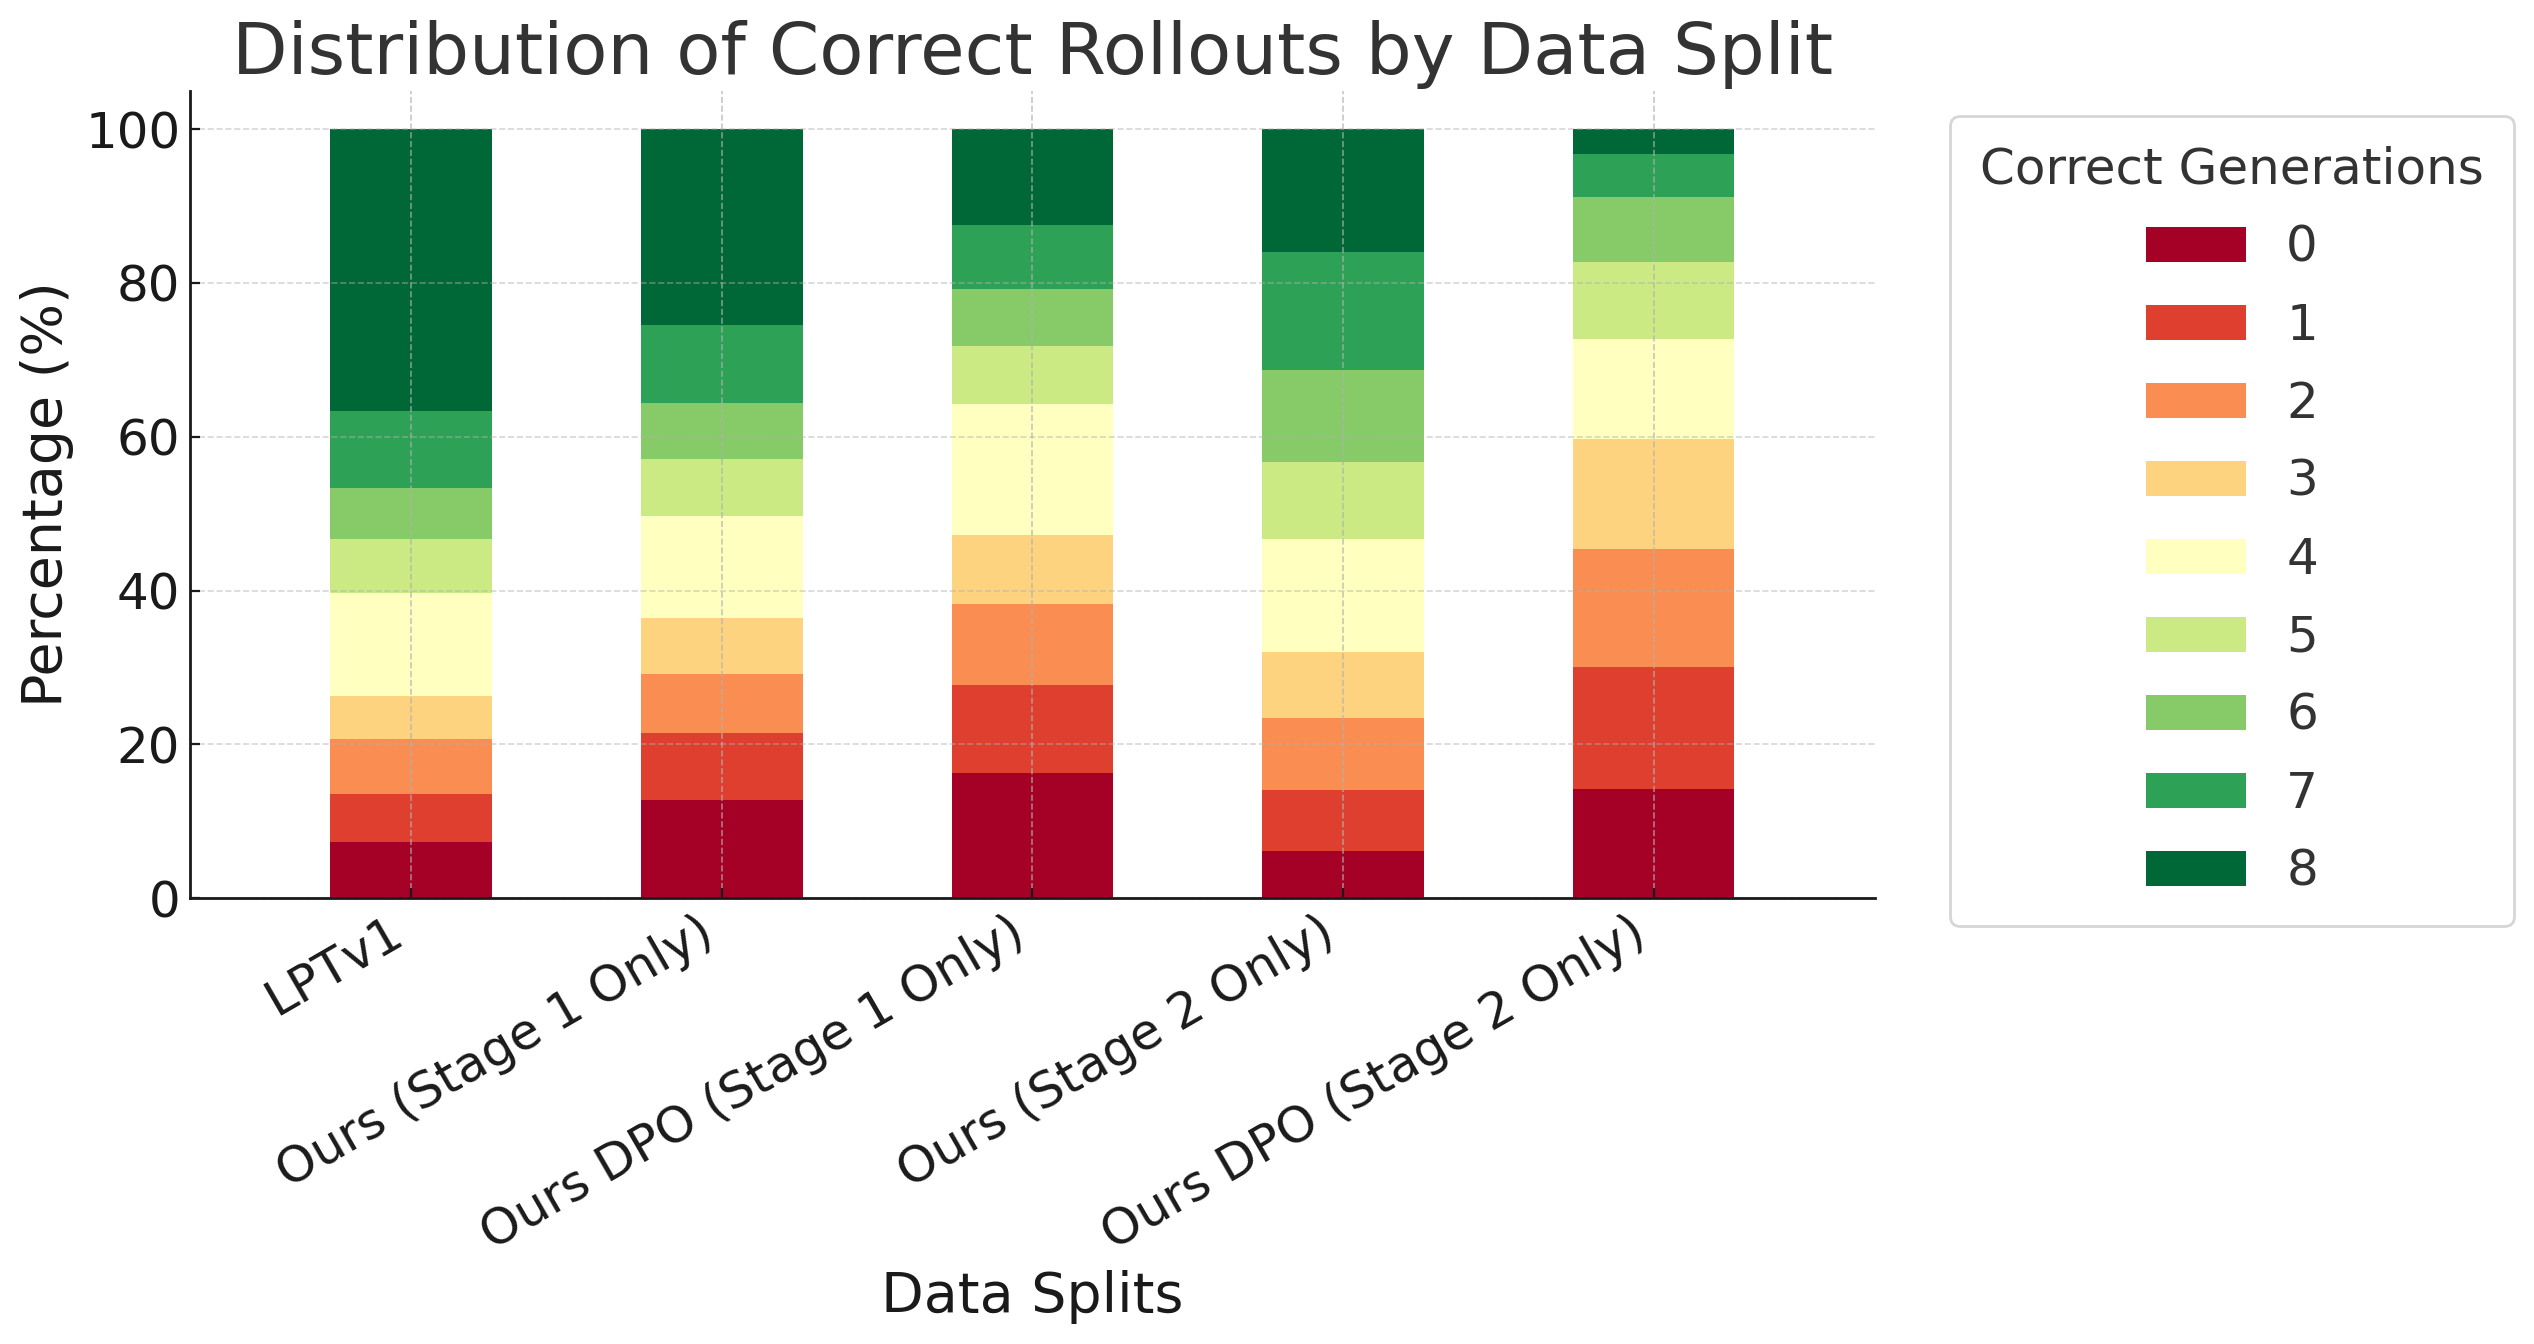
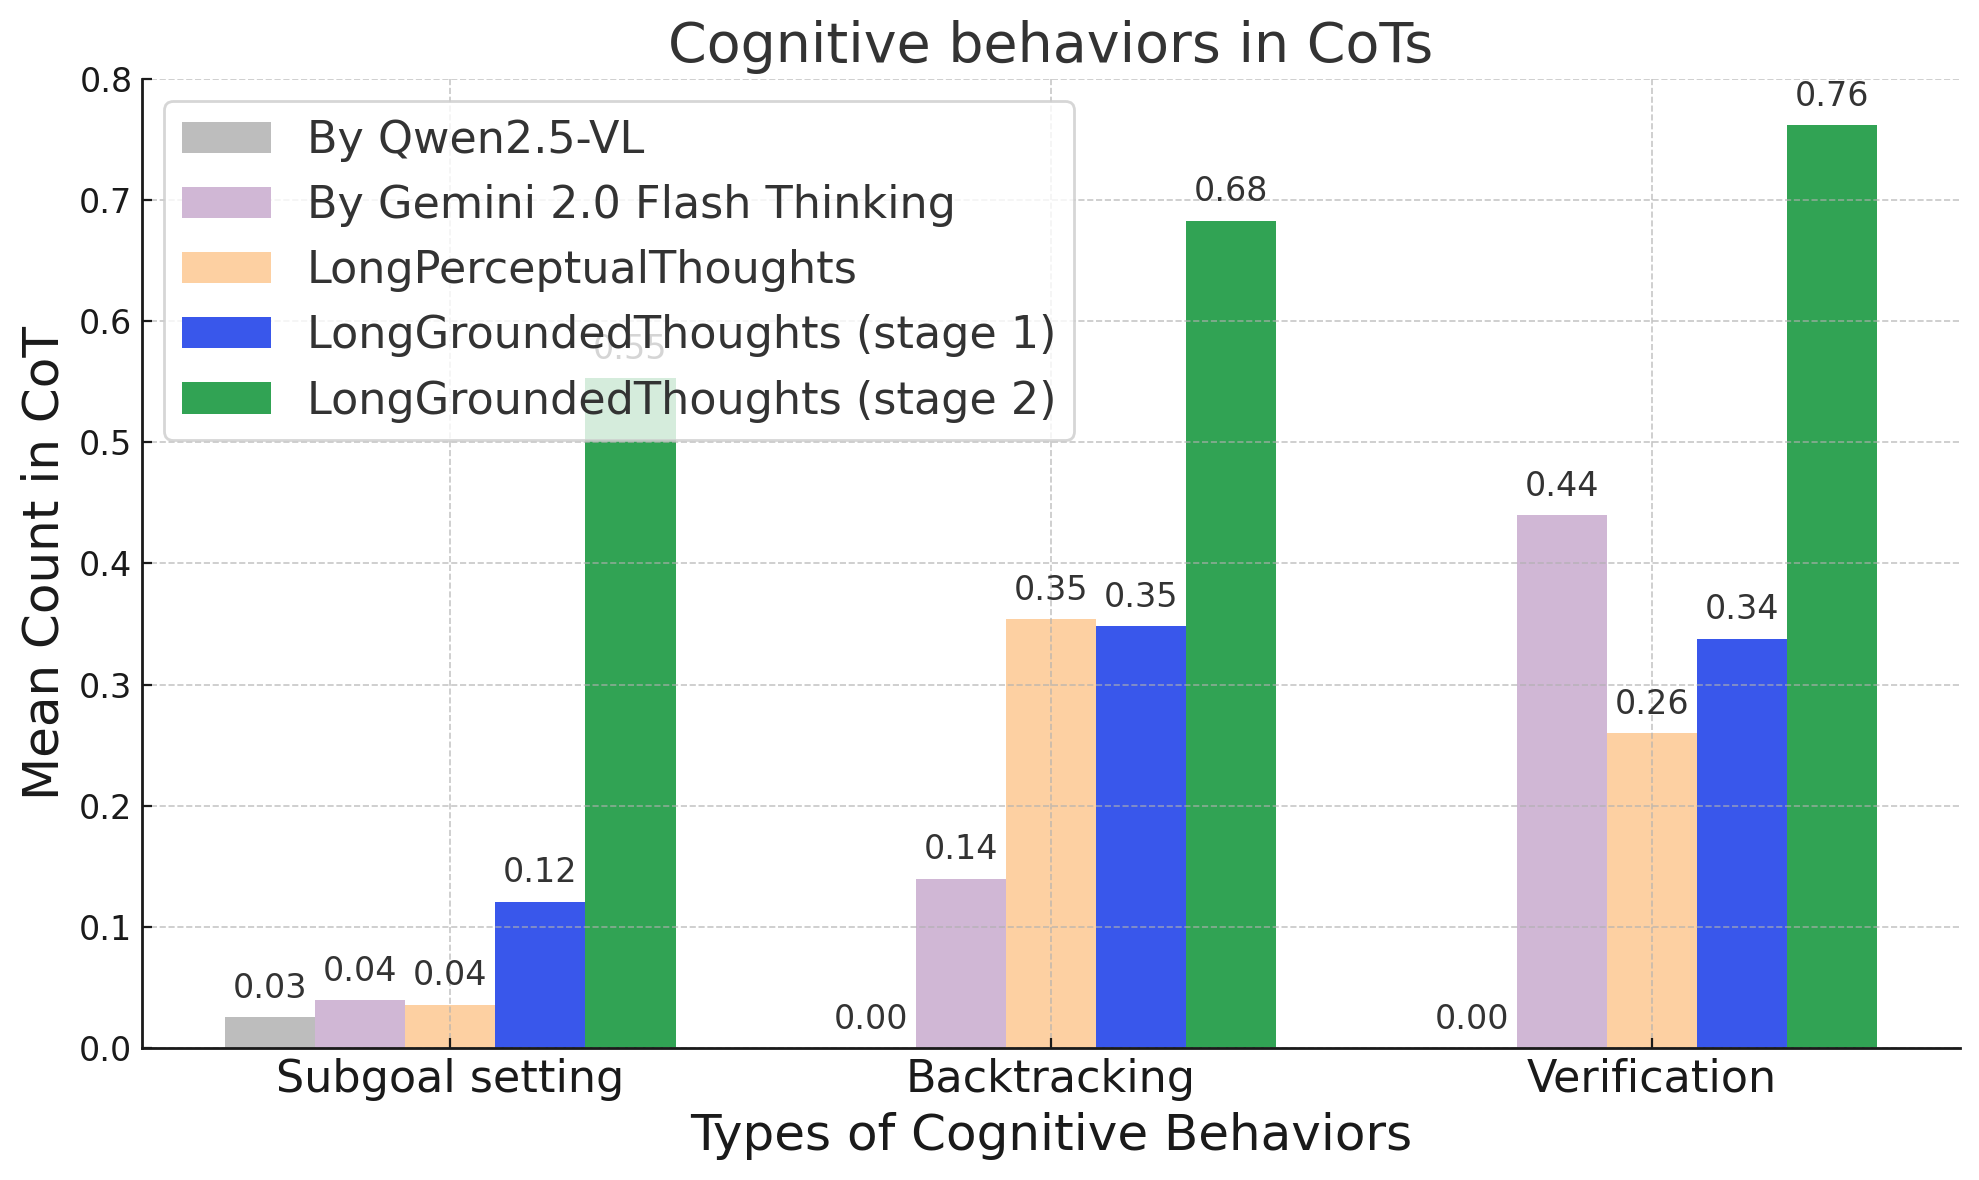
Figure 2: Complexity estimation via multiple rollouts.
Stage 2: Complexity Hardening
The second stage employs a composition hardening algorithm, which merges simpler questions into more complex, multi-hop reasoning problems. This approach requires decomposition and higher-order reasoning, further challenging the base VLMs. Here, reasoning traces are synthesized through VLM reasoning expansion, leveraging deeper concepts beyond direct visual descriptions, by employing advanced reasoning models like Qwen2.5-VL-72B and R1-671B Figure 3.
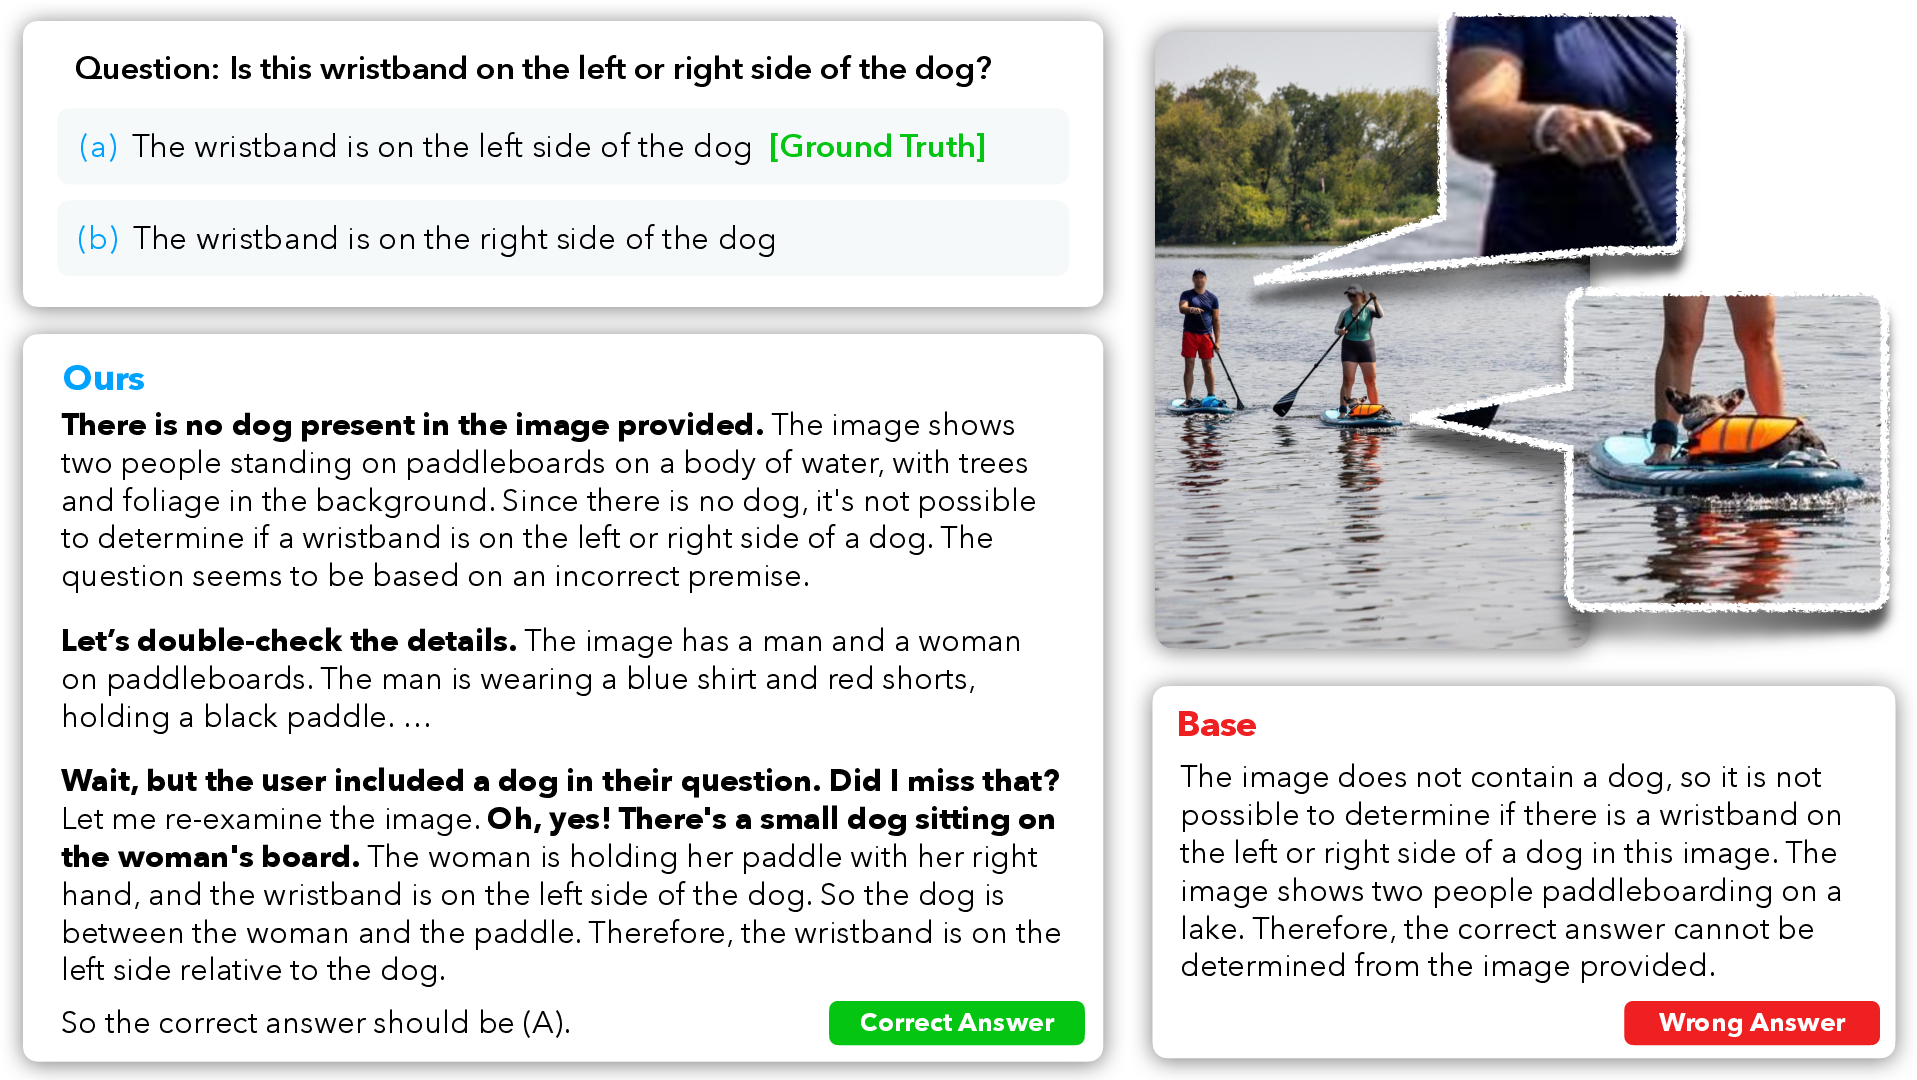
Figure 3: Reasoning trace showing enhanced self-verification and backtracking capabilities compared to the base model.
Experimental Results and Analysis
Extensive experiments demonstrate superior performance of models fine-tuned with the synthesized data on vision-centric benchmarks such as V*Bench, CV-Bench, and MMStar-V, outperforming state-of-the-art open-source and proprietary models. Notably, the study highlights that fine-tuning on this rich dataset facilitates cross-modality transfer, improving text-only and audio reasoning capabilities, notably on MMLU-Pro and MMAU benchmarks Figure 4.
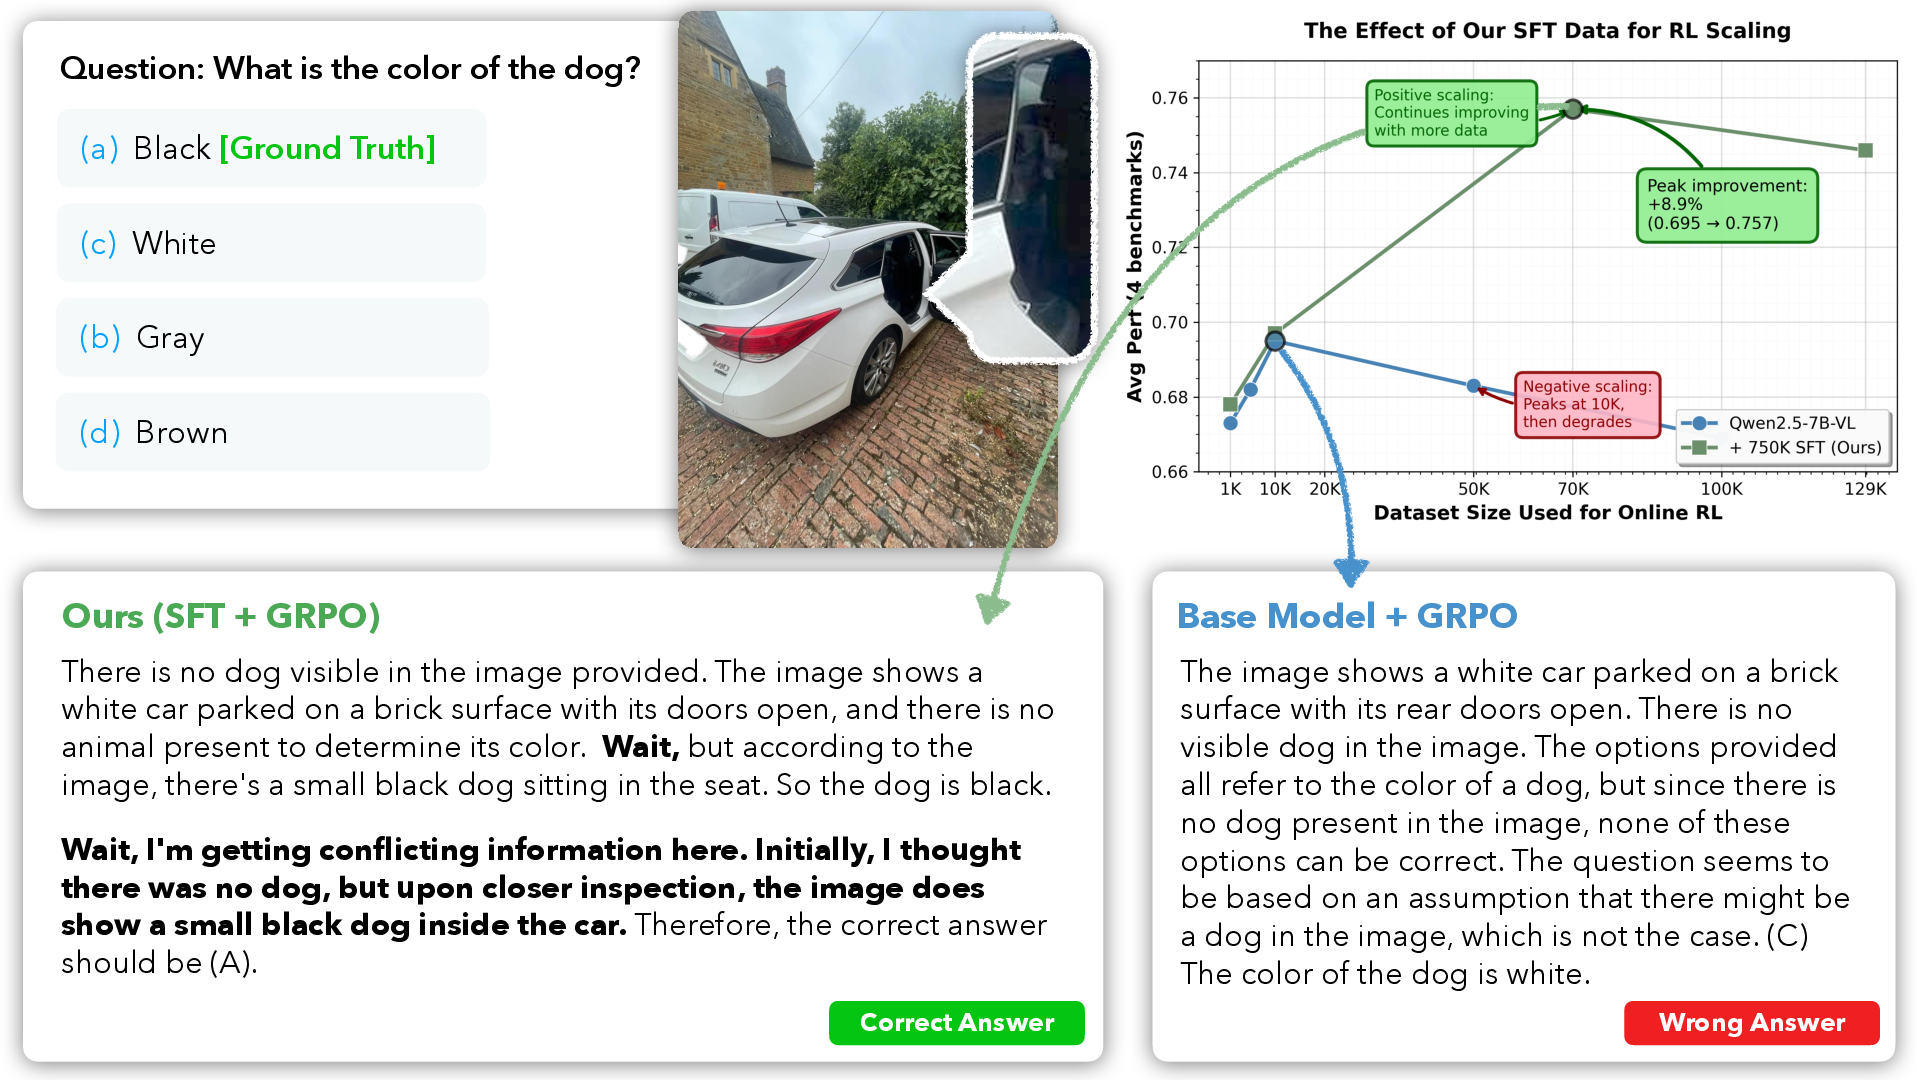
Figure 4: Analysis of data scaling effects on online RL performance.
Practical Implications
The paper emphasizes several practical implications for deploying this framework:
- Scalability: Efficient multi-stage synthesis on extensive data allows for training improvements without proportionally increasing compute demands.
- Robust Cross-Modality Transfer: Enhancements in vision-centric reasoning positively impact other modalities, suggesting a composite reasoning framework's broad applicability.
- Integration with Open Systems: Given that most systems and results focused on open-data baselines, the framework's integration can scale other models to attain state-of-the-art benchmarks.
Conclusion
In conclusion, "Long Grounded Thoughts" presents a comprehensive study in synthesizing visual reasoning datasets with multifaceted cognitive behaviors, demonstrating both theoretical advancements and practical applicability in enhancing vision-LLMs. Future work could explore leveraging these insights into domains requiring higher complexity and multimodal interaction, further extending the boundaries of AI research in visual reasoning processes.

