Towards interpreting any residual stream direction by scaling activation inversion
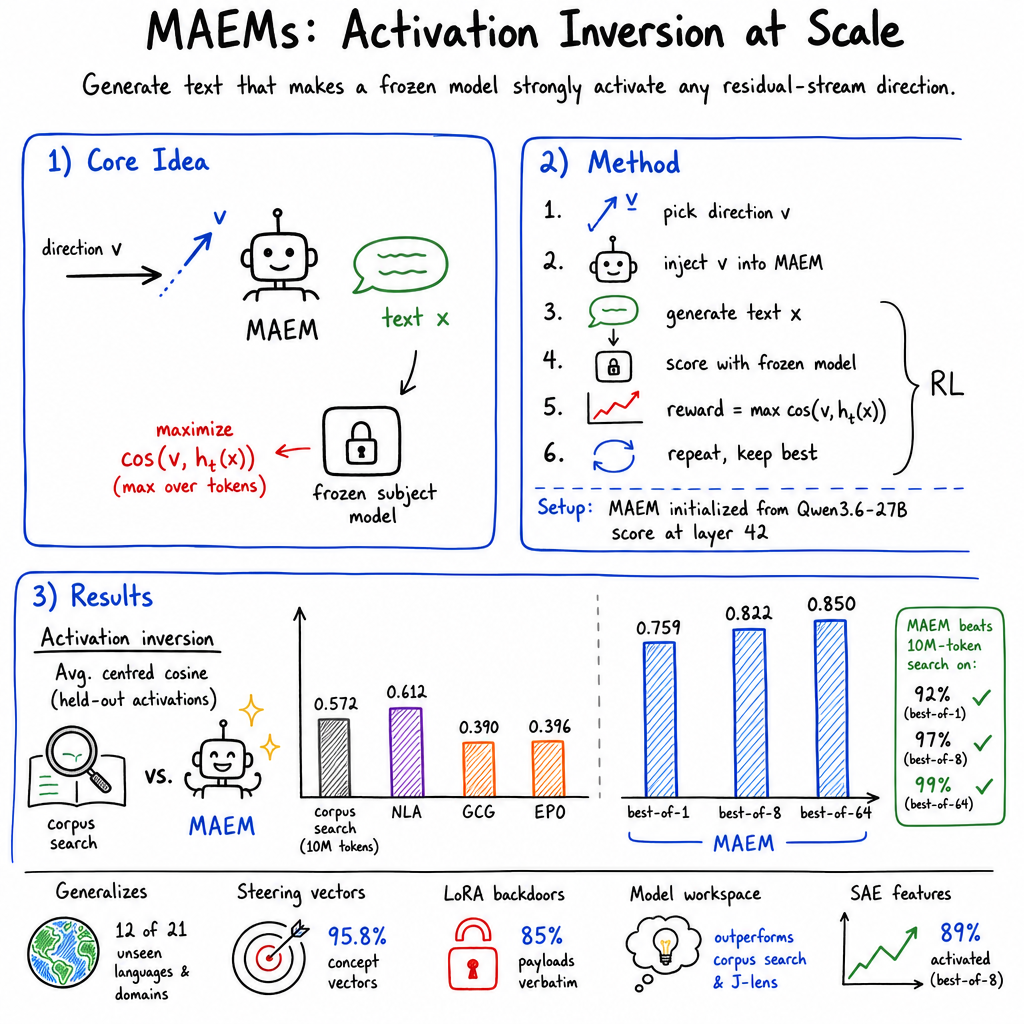
Abstract: To interpret a direction in a LLM's residual stream, we can look for text that strongly activates it. But when such text is found by scanning a corpus, it is limited to what that corpus contains. We develop Maximally-Activating Example Metamodels (MAEMs), LLMs which map residual stream directions from a subject model to text exemplars that strongly activate those directions. Our objective is to maximise the cosine similarity of a supplied residual stream direction with the activations of the text generated by the MAEM. This label-free RL objective helps to scale MAEMs on diverse sources of residual stream directions. Empirically, we find the resultant metamodel produces informative exemplars: a Qwen3.6-27B MAEM inverts held-out activations better than corpus search or a natural-language autoencoder (NLA), beats corpus search (at 10M tokens) on a majority of held-out languages/domains, and activates 89% of held-out SAE features. It also identifies concepts behind steering vectors about as well as NLAs, recovers the payloads of LoRA backdoors more often than corpus search, and can even verbalise some model workspace inner monologue. Unlike explanations produced by other metamodels (e.g. NLAs), MAEM exemplars can be verified with a forward pass on the subject model, making the MAEM objective a grounded alternative for scaling the training of metamodels.
Paper Prompts
Sign up for free to create and run prompts on this paper.
Explain it Like I'm 14
1. What is this paper about?
This paper introduces a system called a MAEM, short for Maximally-Activating Example Metamodel.
The goal is to help researchers understand what is happening inside a LLM, such as ChatGPT. LLMs contain many hidden numbers that represent ideas, patterns, memories, and instructions. These hidden numbers are difficult to interpret directly.
A MAEM takes one of these hidden directions and writes examples of text that strongly activate it. In simple terms, it tries to answer:
“What kind of sentence would make the LLM think in this particular way?”
For example, if a hidden direction is related to wanting power, a MAEM might generate:
“I need to acquire more resources so that I can control the future.”
The researchers call these generated sentences exemplars, meaning examples that show what the hidden direction represents.
2. What questions did the researchers ask?
The paper focuses on several main questions:
- Can a model generate text that activates a chosen hidden direction?
- Can it do this better than simply searching through a large collection of existing text?
- Can one MAEM work with many different types of hidden directions?
- Are its generated examples meaningful, fluent, and useful for understanding LLMs?
- Can the examples reveal hidden concepts, secret instructions, or information stored inside a model?
The researchers also wanted to know whether the system could work on information it had not seen during training, such as other languages, computer code, mathematics, and special hidden directions created by other researchers.
3. How did the researchers do it?
Understanding the basic idea
Imagine that a LLM has a giant map of ideas. Each hidden direction points toward a certain region of this map. One direction might point toward animals, another toward fear, and another toward computer programming.
The MAEM receives one of these directions. It then writes text. The original LLM checks the text and measures how closely its hidden activity matches the chosen direction.
The MAEM receives a higher score when its text points more strongly in the desired direction.
The subject model and the MAEM
The paper uses two models:
- The subject model is the LLM being studied.
- The MAEM is the model that tries to produce text activating a chosen direction in the subject model.
The subject model is kept frozen, meaning its abilities and internal settings are not changed during this experiment. This is important because the researchers want to test whether the MAEM can discover what is already inside the subject model.
Training in two stages
The MAEM was trained in two main steps.
1. Supervised fine-tuning
First, the researchers showed the MAEM examples of hidden activations paired with text that caused those activations.
This is similar to giving a student practice questions with answers. The MAEM learned a rough connection between hidden directions and the kinds of sentences related to them.
2. Reinforcement learning
Next, the MAEM generated its own text. The frozen subject model examined that text and gave it a score.
This is like training a dog with rewards:
- If the generated text strongly activated the target direction, the MAEM received a good score.
- If it did not, the score was lower.
The main score was based on cosine similarity. Despite its technical name, this is simply a way of measuring whether two arrows point in similar directions. A higher cosine similarity means that the text’s hidden activity points more closely toward the target direction.
The researchers did not need people to label every direction. The subject model itself provided the training signal by measuring its own activations.
Comparisons with other methods
The researchers compared MAEM with several other approaches:
- Corpus search: searching a large collection of existing text for passages that activate the direction most strongly.
- Natural-language autoencoders (NLAs): models that try to describe hidden activations using ordinary language.
- Other optimization methods: methods that directly search for text that produces a desired activation.
The researchers tested a MAEM based on the Qwen3.6-27B model at one of its internal layers.
4. What did the researchers find?
MAEM generated stronger examples than ordinary text search
The MAEM usually produced text that matched the target direction more closely than text found by searching a 10-million-token collection.
This makes sense because corpus search can only find things that happen to be present in the collection. A MAEM can create new sentences designed specifically to activate the chosen direction.
The MAEM also worked surprisingly well on material that was not part of its training data. Although it was trained on English web text, it often performed better than searching the target collection in:
- Other languages
- Programming languages
- Mathematical writing
It outperformed its comparison method in 12 of 21 tested non-English and specialized areas.
The generated text was generally understandable
A possible problem is that a model might produce strange or meaningless sentences just to get a high activation score.
However, the researchers found that MAEM examples were usually coherent and readable. In one test, an independent LLM judged MAEM examples to be at least as coherent as the original source text in 67% of comparisons.
Generating more examples also improved their match with the target direction without greatly reducing their fluency.
MAEMs could explain steering vectors
A steering vector is a hidden direction added to a model to push its behavior toward a certain idea or personality trait.
For example, a steering vector might encourage a model to talk more about:
- Gaining power
- Being helpful
- Showing a particular personality
- Discussing a certain topic
When given these directions, MAEM-generated examples helped an evaluator identify the correct concept very accurately:
- About 96% accuracy for one group of concept directions
- About 84% accuracy for another group
This was similar to the strongest competing method and much better than ordinary corpus search.
MAEMs could reveal hidden backdoor instructions
The researchers created artificial backdoors in models. A backdoor is a hidden rule that makes a model behave differently when it sees a particular trigger.
For example:
- Seeing a certain word might cause the model to output a hidden message.
- A special number might activate a secret response.
The MAEM often recovered the meaning of these hidden instructions, especially for thematic triggers. For example, it could identify that a hidden direction was connected to ideas such as anger, hatred, or destruction.
For thematic backdoors, it recovered the hidden payload semantically in about 90% of cases for some directions. It was less successful with numerical triggers, showing that some kinds of hidden information are harder to recover.
MAEMs could read information stored temporarily inside the model
The researchers also studied the model’s so-called workspace. This is like a temporary mental notepad where the model may hold information while solving a problem.
For example, a prompt might describe something without naming it directly. The model could still internally represent the answer.
MAEM examples sometimes revealed this hidden information. In one type of test, it named the hidden answer in about half of the cases. It performed better than several comparison methods, although another method called an NLA performed better on some tasks.
MAEMs activated most tested SAE features
A sparse autoencoder, or SAE, is a tool researchers use to separate a model’s complicated internal activity into simpler features.
A feature might represent something such as:
- Birds caring for their young
- Lists and tables
- A particular topic
- A style of language
The MAEM successfully activated about 89% of the tested SAE features when allowed to generate eight examples. In about 31% of cases, one of its examples activated the feature more strongly than the best example found in the corpus search.
However, the examples were not always diverse enough to explain a feature fully. Descriptions based on ordinary corpus examples sometimes covered more different cases.
5. What are the limitations?
The researchers point out several important weaknesses.
Some features could not be activated
About 11% of the tested SAE features were not reliably activated by the MAEM. About 6.5% were not activated at all across 64 attempts.
This happened especially for:
- Rare features
- Features connected to positions or formats, such as lists and tables
This suggests that some hidden directions may be difficult to understand from the direction alone.
The examples were less diverse
The MAEM often produced several examples that were similar to one another. For example, eight outputs might all express almost the same sentence pattern.
This is useful for strongly activating a direction, but less useful for learning all the different situations in which that feature appears.
The researchers suggest that future versions could include a special reward for producing more varied examples.
Strong activation does not automatically mean correct understanding
A text can activate a direction strongly without perfectly explaining what the direction means. The MAEM may find a shortcut or an unusual type of sentence that works well numerically but does not provide a complete explanation.
The researchers also tested only one main subject model, so it is not yet clear whether the method will work equally well with other model designs.
6. Why is this research important?
The main advantage of MAEMs is that their results can be checked directly.
If a MAEM says that a direction is related to a certain sentence, researchers can run that sentence through the original subject model and see whether the desired hidden activity actually appears. This is more reliable than asking another model to give an explanation that might sound convincing but be incorrect.
The method could help researchers:
- Understand what hidden features in LLMs represent
- Investigate why a model produces certain behaviors
- Find secret instructions or backdoors
- Study how models store information while answering questions
- Improve safety testing and model monitoring
- Build better tools for explaining model decisions
Conclusion
This paper presents MAEMs as a way for LLMs to explain another model’s hidden activity by creating examples that activate it.
The approach is similar to asking a model:
“Show me a sentence that makes you use this hidden idea.”
The researchers found that MAEMs often produced strong, readable examples and worked across many different types of hidden directions. They were useful for identifying concepts, finding hidden backdoor messages, reading some temporary internal information, and activating model features.
The method is not perfect: it sometimes misses rare features and can produce examples that are too similar. Still, it offers an important new tool because its explanations can be tested directly inside the original model. In the future, this could make powerful LLMs easier to inspect, understand, and keep safe.
Practical Applications
Immediate Applications
- Automated interpretability of language-model components — AI research and software tooling. MAEMs can be integrated into interpretability pipelines to generate text exemplars for residual-stream directions, including SAE features, steering vectors, natural activations, and certain LoRA-derived directions. A practical tool could accept a model, layer, and direction vector, then return several high-activation text samples together with their measured cosine similarity and forward-pass activations. Feasibility assumptions: The subject model must be accessible for inference, and the direction must be defined in the model’s residual-stream coordinate system. Results should be verified numerically because strong activation does not necessarily imply a complete or correct semantic explanation.
- SAE feature inspection and debugging — AI safety and mechanistic interpretability. Researchers can use MAEM-generated examples to quickly test whether a sparse autoencoder feature corresponds to a suspected concept. In the paper, eight generated examples activated 89% of tested features, and some exceeded the strongest activation found in a 10-million-token corpus. This supports workflows for browsing features, prioritising unusual features, and identifying candidate feature labels before conducting more extensive corpus analysis. Dependencies: Coverage is incomplete: approximately 11% of tested features were not reliably elicited, and failures were concentrated among rare and positional features. Corpus examples remain useful for diversity and recall.
- Steering-vector validation — model customization and evaluation. Developers can generate exemplars from a steering vector to check whether the vector encodes the intended concept or behaviour before deploying it. For example, a vector intended to promote caution, politeness, or technical detail could be tested by generating multiple MAEM examples and comparing them with the intended design specification. The method achieved high concept-identification accuracy and outperformed corpus search in the paper’s evaluation. Dependencies: A direction may encode several correlated concepts, and MAEM output can reflect only the portion of the direction that is easily expressible through text. Human review and behavioural testing remain necessary.
- Auditing fine-tuning updates and LoRA adapters — cybersecurity and model governance. MAEMs can be used to inspect rank-1 or similar low-rank adapter directions for hidden triggers and payloads. An audit workflow could compare MAEM exemplars for the adapter’s read and write directions against the adapter’s declared purpose, flagging outputs that reveal unexpected topics, trigger words, or malicious instructions. The paper reports substantially better recovery of thematic backdoor payloads than corpus search, including from directions not represented during MAEM training. Dependencies: Recovery is weaker for numeric or highly specific code triggers, and successful inversion does not prove that an adapter is malicious. Audits should combine MAEM results with trigger testing, weight-diff analysis, and behavioural evaluation.
- Model checkpoint and deployment monitoring — industry and policy compliance. Organizations can periodically sample internal activation directions, steering vectors, or adapter directions and generate exemplars to detect changes after fine-tuning, quantization, safety training, or model updates. A dashboard could record activation scores, exemplar diversity, and semantic shifts between checkpoints. This creates a practical evidence trail for model-risk review. Dependencies: The MAEM must be compatible with the model architecture and layer representation. The current evidence is based primarily on one model family and one checkpoint, so cross-architecture reliability is unestablished.
- Workspace and hidden-state inspection during debugging — AI systems engineering. When a model’s residual stream contains information not stated explicitly in the input, MAEM exemplars can provide readable hypotheses about that latent content. This may help engineers inspect intermediate reasoning context, unstated bridge entities in multi-hop tasks, or topic information carried between layers. The method performed better than several token-readout and corpus-search baselines on some workspace tasks. Dependencies: Workspace recovery is partial and below the strongest natural-language-autoencoder baseline on several tasks. It should be treated as a diagnostic aid rather than a faithful transcript of the model’s internal reasoning.
- Candidate-example generation for automated feature explainers — academic and industrial research. MAEM outputs can serve as inputs to automated SAE-feature description systems. This is immediately useful when corpus search is expensive, unavailable, proprietary, or poorly matched to the target domain. A workflow could generate activation-maximising examples, mark their activating tokens, and pass them to an explainer model for preliminary descriptions. Dependencies: MAEM examples have lower diversity than corpus windows and produced narrower feature descriptions, with lower recall of held-out positives. Systems should combine generated exemplars with corpus samples or deliberately diversify generation.
- Cross-domain interpretability experiments — multilingual, code, and mathematics. Because the trained MAEM generalised beyond English web text, researchers can use it as a first-pass interpretability instrument for directions associated with programming languages, mathematical text, and non-English languages. This can reduce the need to build a separate large activation-search corpus for every domain. Dependencies: Generalisation was uneven: the method outperformed in 12 of 21 evaluated held-out domains, not all domains. Domain-specific validation and local corpus comparisons remain necessary.
- Interactive education and research interfaces — academia and training. A visual interface could allow students or researchers to select a layer, SAE feature, or steering direction and inspect several generated examples alongside activation scores. This would make otherwise abstract residual-stream concepts more concrete and support exploratory learning in courses on neural networks, interpretability, and AI safety. Dependencies: The interface must clearly distinguish “text that activates a direction” from a definitive explanation of that direction. Poorly understood or degenerate examples could otherwise mislead users.
Long-Term Applications
- Scalable automated interpretability infrastructure — AI safety and model evaluation. MAEMs could become a reusable pretraining or support component for large-scale interpretability systems. A single metamodel might generate exemplars for millions of directions from SAEs, probes, steering vectors, activation states, and fine-tuning weight differences, providing machine-checkable evidence for downstream natural-language explainers. This could support automated inventories of model concepts and behavioural mechanisms. Dependencies: The approach must scale across architectures, model sizes, layers, and training distributions. It also requires methods for handling directions that are not sufficiently identifiable from a single vector.
- Continuous backdoor and supply-chain scanning for model adapters — cybersecurity and governance. Future model registries could automatically inspect submitted LoRA adapters and fine-tuning deltas. The system would generate exemplars for read/write directions, search for unexpected triggers or payloads, and compare the results with the adapter’s metadata and intended use. This could become part of model-release certification or enterprise software supply-chain security. Dependencies: Attackers may use distributed, encrypted, numeric, multilingual, or context-dependent triggers that are difficult to verbalise. Robust deployment would require adversarial testing, multi-layer analysis, and calibrated false-negative and false-positive rates.
- Interpretability-assisted model editing and alignment — safety engineering. If MAEM-generated exemplars reliably identify undesirable or desirable directions, they could guide targeted model editing. Engineers might locate a harmful concept, identify associated SAE features or weight directions, edit or suppress them, and then use MAEMs to verify whether the intended direction has changed. The same loop could support personalization, refusal tuning, or domain adaptation. Dependencies: Activational alignment is not equivalent to behavioural alignment. Editing a direction could affect unrelated concepts, and MAEM-generated examples might fail to reveal rare contexts where the behaviour appears.
- Activation-space search engines and monitoring systems — enterprise AI operations. A future product could index residual-stream directions and allow users to search a model’s internal activity using natural-language exemplars. For example, an operator could investigate “planning around shutdown,” “financial advice,” or “customer privacy” and retrieve directions and generated activating texts associated with those themes. This could support incident investigation and model-behaviour triage. Dependencies: Reliable semantic indexing requires calibrated mappings between generated text, directions, and actual model behaviour. Privacy, logging, and access-control protections would also be required when inspecting proprietary or user-derived activations.
- Improved mechanistic explanations through diverse activation maximisation — research tooling. Future MAEM objectives could optimise not only maximum cosine similarity but also diversity, coverage, controllability, and causal validity. A system might return a set of examples representing different contexts in which a direction activates, rather than many near-duplicates. This could address the paper’s main limitation and improve automated SAE descriptions. Dependencies: Diversity objectives may reduce peak activation, and selecting semantically distinct examples without a learned judge is challenging. Better evaluation protocols are needed to distinguish genuine coverage from superficial textual variation.
- Reading latent workspace states in agentic systems — robotics and autonomous AI. If cross-layer and cross-task reliability improves, MAEMs could help inspect intermediate states in planning agents, tool-using systems, and robotic controllers. Developers might generate textual probes for latent goals, task constraints, selected subgoals, or suspected deceptive strategies during execution. This could enable runtime safety monitors that compare internal states with declared plans. Dependencies: The paper demonstrates only limited workspace recovery, mainly in language-model tasks. Agentic and multimodal systems may encode information in forms that a text-only MAEM cannot express, and monitoring must operate with sufficiently low latency.
- Policy and regulatory evidence for model-risk assessments — public governance. Regulators or auditors could require developers to provide activation-based evidence about safety-relevant model features, hidden adapters, and post-training changes. MAEM outputs are attractive as audit artifacts because each exemplar can be checked by rerunning the subject model rather than relying solely on an opaque explanatory judge. Dependencies: Verification of activation alignment does not establish causal interpretation, absence of risk, or general safety. Standards would need to specify sampling procedures, reproducibility, coverage requirements, and acceptable uncertainty.
- General-purpose metamodel pretraining — foundational AI research. Activation inversion could serve as a self-supervised objective for training metamodels that later perform richer tasks such as concept classification, feature description, model comparison, or explanation generation. Because the reward comes directly from the frozen subject model and does not require human or LLM-written labels, it may provide a scalable foundation for model-understanding systems. Dependencies: The objective may be exploitable through degenerate or repetitive text, and the current experiments do not establish that MAEMs transfer across architectures. Further work is needed on reward design, causal tests, sample diversity, and cross-model transfer.
Glossary
- Activation inversion: Generating an input whose model activation aligns with a specified target direction. “We extend previous work ([PERSON_NAME], 2024; [PERSON_NAME], 2025; [PERSON_NAME], 2025) by using reinforcement learning (RL) to directly maximise cosine similarity between the target direction and the activations of the produced text”
- Activation maximisation: Optimising an input to produce a large activation for a neuron or feature. “In computer vision, [PERSON_NAME]. (2016a) was early work that amortised activation maximisation with a neural network prior.”
- Activation oracle: A model trained to interpret or explain the activations of another model. “LatentQA-style readers and activation oracles are trained on question–answer data written by humans or LMs”
- Activation direction: A vector representing a pattern or state in a model’s activation space. “Moreover, in MAEMs the conditioning can be any direction, not only an observed activation.”
- Activation-guided preference optimization: Optimising generated outputs according to their effect on a target activation. “SAEExplainer: Interpreting SAE features with activation-guided preference optimization.”
- Activation inversion objective: A training objective that encourages generated text to reproduce or align with a target activation. “Training on this activation inversion objective reduces a source of subjectivity”
- Autointerp explainer: An automated system that generates natural-language explanations of model features. “providing inputs to an autointerp explainer of SAE features”
- BatchTopK sparse autoencoder: A sparse autoencoder that selects the highest-activating features across a batch rather than independently for each input. “We evaluate 512 features of a 131k-feature BatchTopK SAE”
- Best-of-k: Selecting the highest-scoring result from independently generated candidates. “For each target, we generate 64 MAEM exemplars of at most 64 tokens each and report best-of-k for k = 1, 8, and 64.”
- Bi-directional Preference Optimisation (BiPO): A preference-learning method that trains vectors using paired preferred and dispreferred examples. “vectors trained with Bi-directional Preference Optimisation (BiPO)”
- Centred cosine: Cosine similarity computed after subtracting a common mean activation from the compared vectors. “We report the centred score sμ(v, x): the score of Equation 1 with a fixed corpus mean activation μsubtracted from v and from every ht(x)”
- Corpus search: Searching a text collection for passages that produce high activation values. “Corpus search selects the 64-token window (stride 32) containing the token with the highest cosine to v”
- Discrete optimisation: Optimising inputs by making changes among discrete alternatives, such as tokens. “For LMs, common methods include corpus search … and discrete optimisation”
- Distribution shift: A difference between the data distribution used for training and that encountered during evaluation. “these inputs are out-of-distribution.”
- Elicitation: Producing an input that causes a model to express or activate a particular latent property. “We count a feature as successfully elicited if a draw’s peak activation exceeds the SAE threshold”
- Fluency: The degree to which generated text is linguistically natural and probable. “We quantify the fluency and coherence of MAEM exemplars.”
- Forward pass: Computing a model’s activations by processing an input through its layers. “each x is a sufficient condition for driving v.”
- Global workspace: A hypothesised shared representational area in a model’s residual stream that stores information available to multiple computations. “Gurnee et al. (2026) theorise that LMs store information in a ‘workspace’ in their residual stream as a working context during a forward pass”
- Gradient-free discrete optimisation (GCG): A token-search method for finding text that produces a desired model behaviour or activation. “The other baselines are NLA … GCG ([PERSON_NAME], 2023) and EPO”
- Held-out activation: An activation reserved for evaluation rather than used during training. “We evaluate accuracy of inversion of held-out activations.”
- In-distribution: Belonging to the same data or task distribution used during training. “these inputs are out-of-distribution.”
- Latent representation: An internal vector encoding information that is not directly observable in the model’s text output. “Scalably extracting latent representations of users.”
- Layer-grid pooling: Combining information from corresponding features or tokens across multiple model layers. “J-lens in an additional setting with an eight layer grid pooling the top 10 tokens at each of layers 36, 38, . . . , 50.”
- LoRA: A parameter-efficient fine-tuning technique that represents a weight update as a low-rank product of matrices. “LoRAs containing trojan payloads.”
- Maximally-Activating Example Metamodel (MAEM): A model that generates text designed to strongly activate a supplied direction in another model. “We introduce the MAEM (Maximally-Activating Example Metamodel)”
- Metamodel: A model trained to interpret or operate on the internal representations of another model. “We see MAEMs as a verifiable addition to the emerging metamodels research programme”
- Natural language autoencoder (NLA): A model that explains or reconstructs an activation using natural-language text. “NLAs train such a describer end-to-end to reconstruct the target activation”
- Out-of-distribution generalisation: The ability to perform well on data or tasks unlike those used during training. “We also demonstrate clear out-of-distribution generalisation”
- Payload: The information or behaviour encoded into a model by a backdoor or adapter. “The MAEM recovers read directions of the theme triggers, but not the numerical code triggers”
- Preimage: The set of inputs that map to a specified output or activation under a function. “MAEM samples are therefore optimised to lie in the direction’s preimage”
- Residual stream: The sequence of vectors passed through a transformer’s layers by repeatedly accumulating updates. “Many questions in interpretability reduce to understanding some direction in the residual stream”
- Rank-1 adapter: A parameter update constrained to the outer product of two vectors, giving it rank one. “We train rank-1 LoRA trojans that deliver a payload after a trigger”
- Reinforcement learning (RL): Training in which a policy is updated to maximise a reward computed from its outputs. “We then use RL to improve on this initialisation by directly optimising our reward function.”
- Residual norm: The Euclidean magnitude of a vector in the residual stream. “rescaling it to match the residual norm”
- SAE feature: A learned sparse component intended to represent a recurring concept or pattern in model activations. “A MAEM can generate exemplars that activate a given SAE feature”
- Sparse autoencoder (SAE): An autoencoder that represents inputs using relatively few active latent features. “The MAEM receives the encoder direction wencf as v.”
- Steering vector: A vector added to a model’s activations to shift its output toward a desired concept or behaviour. “A steering vector is added to a model’s residual stream to shift model output towards the vector’s underlying concept”
- Supervised fine-tuning (SFT): Training a pretrained model on labelled input-output examples for a particular task. “We train MAEMs from a copy of the subject model’s weights and with supervised fine-tuning (SFT) followed by RL.”
- Trojan backdoor: A hidden model behaviour activated by a specific trigger input. “We train rank-1 LoRA trojans that deliver a payload after a trigger”
- Vendi score: A diversity metric that estimates the effective number of distinct items in a collection. “We measure the diversity of samples generated by a MAEM with the Vendi score”
- Verbalisation: Converting an internal representation or latent concept into natural-language text. “VERBALISING THE MODEL WORKSPACE”
- Workspace inner monologue: Latent, intermediate model content expressed as language-like information during processing. “can even verbalise some model workspace inner monologue”

