PolicyIK: Precision Robotics Through Reinforcement Learning
This presentation explains how PolicyIK achieves millimeter-level accuracy in robot arm control by reformulating inverse kinematics as a closed-loop regulation problem. We explore why traditional kinematic solutions fail at high precision, how reinforcement learning addresses steady-state pose errors through command-state feedback and multiscale sensing, and what the 93% success rate at submillimeter tolerances means for the future of robotic manipulation.Script
Most robot arms can reach a pose. Far fewer can hold it at submillimeter precision while gravity pulls, servos lag, and joint limits constrain motion. The authors of PolicyIK show that the gap between reaching and regulating is not a hardware problem but a control formulation problem, and reinforcement learning can close it.
Traditional inverse kinematics treats this as a one-shot mapping from end effector pose to joint configuration. But the joint angles that satisfy ideal geometry are not the servo references that compensate for gravity, finite gains, and actuator dynamics. PolicyIK instead outputs increments to an accumulated joint reference, preserving the steady-state offset required to hold the pose without drift.
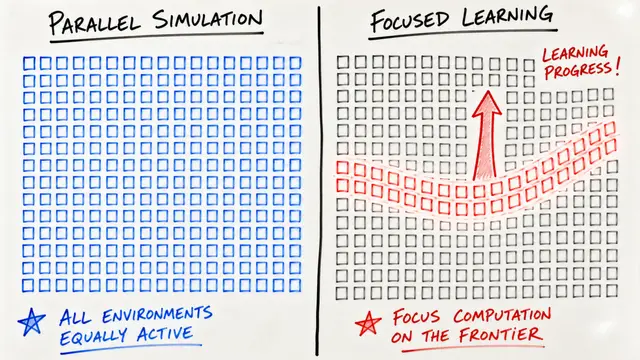
Three design choices make precision possible. The policy observes command state, the gap between its accumulated reference and the measured joints, which determines how future actions will move the arm. It receives pose errors at two scales: coarse channels spanning centimeters and degrees for workspace motion, fine channels resolving half-millimeter and quarter-degree residuals for terminal correction. And its action magnitude adapts to error scale, taking large steps during transport and shrinking near the goal.
The reward structure separates two learning problems. Progress rewards pay only when the policy establishes a new best error, preventing credit for oscillation. Dwell rewards pay at every step inside tolerance, explicitly training the system to stay rather than merely touch the target. Ablations show that removing dwell increases the fraction of tasks that enter the strict region and then leave it from 2.4 percent to 7.8 percent.
On 4,120 held-out simulation tasks, PolicyIK achieves 93 percent strict success with median errors of 0.25 millimeters and 0.04 degrees. Classical controllers tuned on separate tasks reach only 56 percent strict success. Many failures occur at joint limits, where damped-least-squares and quadratic programming methods stall with persistent pose plateaus, unable to reshape their approach while PolicyIK learns reference trajectories that respect coupled dynamics and command constraints.
Hardware experiments confirm the formulation without simulation pretraining. On 60 physical OpenArm tasks with a 25-second budget, PolicyIK holds 43 poses within tolerance for the final 5 seconds. Classical controllers reach nearly as many targets but hold only 11 to 17, because reaching does not guarantee the steady-state reference needed to stay. This work is available at EmergentMind.com, where you can explore the research and create your own videos.