- The paper presents a novel training‐free DOA policy that uses decoder self‐attention to guide incremental speech-to-text translation.
- It introduces proxy alignment extraction from self-attention weights and effective context pruning strategies to balance latency and quality.
- Experimental results demonstrate near-offline quality on EN→DE and EN→IT benchmarks, outperforming traditional encoder-decoder models.
Introduction
The paper "DOA: Training-Free Decoder-Only Attention Policy for Long-Form Simultaneous Translation with SpeechLLMs" (2605.31432) addresses a persistent challenge in SimulST: streaming speech-to-text translation using decoder-only SpeechLLMs without explicit cross-attention mechanisms or task-specific retraining. The authors introduce the Decoder-Only Attention (DOA) policy, a training-free method for extracting proxy alignment signals from decoder self-attention, thus enabling streaming translation decisions in long-form settings.
A key insight driving the work is that decoder self-attention -- despite lacking explicit source-target alignment -- can yield sufficiently stable proxies for guiding streaming output. The policy adapts attention-based strategies originally designed for encoder-decoder models, circumventing the need for retraining and unlocking incremental generation capacity in off-the-shelf architectures.
Methodology: Decoder-Only Attention Policy
The DOA streaming policy operates by extracting a proxy alignment matrix from decoder self-attention weights. During autoregressive decoding, the model processes a sequence comprising speech (audio tokens) followed by generated text (output tokens). Self-attention weights A(l,h)∈RT×(S+T) are obtained, where S is the number of acoustic tokens and T is the number of text tokens. Attention directed exclusively toward the acoustic context, A~(l,h)=A(l,h)[:,:S], is isolated. Averaging across layers and heads, Aˉ serves as a proxy for cross-attention.
Streaming decisions are then driven by aligning each generated token t to the most attended acoustic token at via argmaxsAˉt,s. A cutoff parameter f controls commitment: only tokens grounded in audio segments older than the last f frames are emitted, balancing translation stability and latency.
Long-Form Context Management
Given the incremental and potentially unbounded nature of streaming audio, the DOA policy incorporates aggressive context pruning. Two textual history selection strategies (fixed-word count vs. punctuation-based segmentation) determine retained text prefixes. Audio frames aligned exclusively to discarded textual history are pruned, ensuring both speech and text contexts remain bounded. As a fallback, when the attention-based pruning fails, oldest audio frames are truncated to maintain memory feasibility.
Notably, this framework is model-agnostic, requiring only access to decoder self-attention weights and imposing no architectural modification or retraining.
Experimental Results
Impact of Textual History Selection
Empirical comparison between punctuation-based and fixed-word history selection shows that punctuation yields more stable and higher quality streaming translation across all latency regimes. Contrary to previous findings in encoder-decoder setups where fixed-word strategies dominated, punctuation segmentation favors continuity and sentence-level context in decoder-only SpeechLLMs. This corroborates established linkage between punctuation presence and transformer-based contextual modeling efficacy.
Layer and Head Selection Effects
Analysis of layer- and head-wise aggregation versus specific selection exposes pronounced instability in layer selection, with several layers substantially degrading latency and quality. Head selection yields minimal gains, with select heads (2, 10) performing slightly better. Therefore, averaging across layers and heads is the robust and optimal choice for proxy alignment extraction.

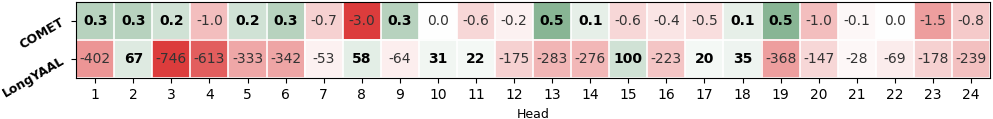
Figure 1: Layer- and head-wise performance difference compared to average, with green indicating improvements and red degradation; magnitudes given in COMET S0100 and LongYAAL (ms).
DOA was applied to Phi4-Multimodal (dense) and Qwen3-Omni (MoE), both open-weight SpeechLLMs, on EnglishS1German and EnglishS2Italian benchmarks. Quality, measured via COMET, approaches offline translation: the best SpeechLLM achieves 0.78 (en-de) and 0.81 (en-it). Qwen3-Omni achieves broad latency coverage (400ms--3.8s), outperforming in both latency and translation quality. Phi4-Multimodal exhibits easier latency management, with mono-incremental impact per cutoff adjustment.
Both DOA-equipped SpeechLLMs consistently surpass the SimulStream StreamAtt AED baseline in latency-quality tradeoff, demonstrating the viability of decoder self-attention for streaming policy construction without task-specific adaptation.
Implications and Theoretical Considerations
The DOA policy demonstrates that decoder self-attention in SpeechLLMs, when properly processed, captures sufficiently robust alignment information to enable streaming translation decisions, challenging assumptions that only cross-attention in encoder-decoder models suffices. The results imply broader generalizability of attention-based streaming policies to a wider class of LLM-based architectures, including those designed for generalized multimodal input.
Practically, DOA allows any sufficiently capable SpeechLLM to be utilized for SimulST in long-form, real-world audio scenarios without retraining, lowering deployment barrier and potentially catalyzing scale-out in high-volume voice translation applications.
The findings also highlight the relevance of sentence-level segmentation via punctuation in streaming translation, particularly for maintaining contextual integrity in long-form inference.
Limitations and Future Directions
The evaluation scope is limited primarily to English source speech and Latin script target languages, leaving open questions regarding generalization to languages with divergent scripts (logographic, morphologically rich) or tokenization. Computational-aware latency was not uniformly reported due to hardware heterogeneity; future work should systematize model benchmarking and optimize inference pipelines.
Theoretical exploration into the nature of alignment signals extracted from decoder self-attention may yield deeper understanding of implicit cross-modal relationships in large multimodal LLMs. Mechanistic studies could probe the stability and transferability of proxy alignment under varying linguistic domains and speech characteristics.
Future development may move toward cross-modal and multilingual expansion, integrating further advances in efficient context pruning, memory management, and real-time translation quality prediction.
Conclusion
The DOA policy presented in the paper represents a robust, training-free method for enabling long-form simultaneous speech-to-text translation with decoder-only SpeechLLMs, leveraging self-attention-derived proxy alignments for streaming decisions. Empirical results validate low-latency translation with quality near offline systems, outperforming encoder-decoder baselines. The approach generalizes across dense and MoE SpeechLLM variants and transfers to streaming settings without architectural adaptation. DOA thus provides a scalable foundation for practical deployment and future research in streaming translation with large multimodal LLMs.

