Papers
Topics
Authors
Recent
Search
2000 character limit reached

Learning Local Causal World Models with State Space Models and Attention

Published 4 May 2025 in cs.LG and stat.ML | (2505.02074v1)

Abstract: World modelling, i.e. building a representation of the rules that govern the world so as to predict its evolution, is an essential ability for any agent interacting with the physical world. Despite their impressive performance, many solutions fail to learn a causal representation of the environment they are trying to model, which would be necessary to gain a deep enough understanding of the world to perform complex tasks. With this work, we aim to broaden the research in the intersection of causality theory and neural world modelling by assessing the potential for causal discovery of the State Space Model (SSM) architecture, which has been shown to have several advantages over the widespread Transformer. We show empirically that, compared to an equivalent Transformer, a SSM can model the dynamics of a simple environment and learn a causal model at the same time with equivalent or better performance, thus paving the way for further experiments that lean into the strength of SSMs and further enhance them with causal awareness.
Summary

  • The paper introduces S2-SSM, which combines SlotSSM sequence modeling with sparsity-regularized attention to predict object dynamics while recovering local causal graphs.
  • S2-SSM achieves an average reconstruction MSE of 2.90 × 10⁻⁴ and SHD of 1.41 on Interventional Pong, outperforming the sparse Transformer baseline’s SHD of 11.15.
  • The ablation shows that sparsity regularization is essential for meaningful causal discovery, while open challenges include learning object representations and testing SSM memory in realistic environments.

The paper "Learning Local Causal World Models with State Space Models and Attention" (2505.02074) investigates whether State Space Model (SSM) architectures can learn causal world models on par with Transformer-based counterparts. The authors introduce S2-SSM (Sparse Slot State Space Model), which combines a SlotSSM backbone with a sparsity regularization scheme adapted from SPARTAN (2505.02074), and demonstrate empirically that an SSM-based world model can simultaneously predict environment dynamics and recover a local causal graph over object-level variables.

Motivation and positioning

World models that merely predict future observations often fail to capture the causal structure of the environment, yet robustness to distributional change has been argued to require exactly such causal representations (2505.02074). Prior work has used attention weights in Transformers as indicators of causal relations between variables, most notably in SPARTAN, where sparsity regularization on attention yields interpretable causal graphs for video prediction. The authors extend this line to SSMs, motivated by their linear-time inference, long-horizon memory, and avoidance of the quadratic cost of self-attention. The specific open question is whether the interaction layers of a SlotSSM — cross-attention between object slots interleaved with Mamba layers — can serve the same causal-discovery role as Transformer attention layers.

The S2-SSM architecture

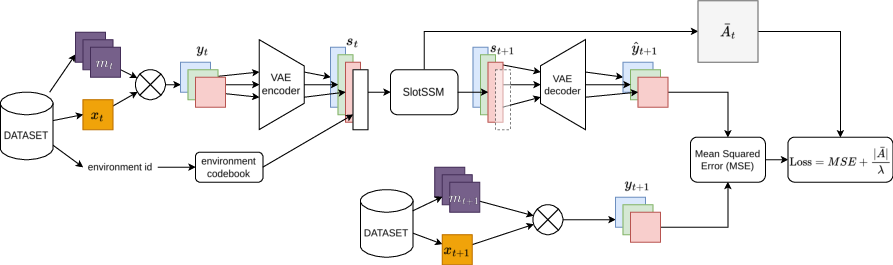
S2-SSM operates on object-centric slot representations rather than raw pixels. Given ground-truth object masks provided with the dataset (a deliberate simplification, since representation learning is not the focus), each object is encoded into a DD-dimensional slot by a VAE trained end-to-end with the world model. A learnable codebook supplies environment slots during training; at test time the model must infer the current environment from data alone, and can fine-tune a new intervention slot for unseen environments using only a small held-out fraction of data while keeping the VAE and world model frozen.

Figure 1

Figure 1: Scheme of the S2-SSM architecture.

The dynamics module stacks SlotSSM blocks: each block applies a Mamba layer to model the free evolution of each object independently, followed by a cross-attention layer that models interactions among slots. Causal discovery is performed by treating the cosine-similarity adjacency matrix between queries and keys, Aij=σ(qiTkj)A_{ij} = \sigma(q_i^T k_j), as the causal graph, which also masks the attention operation so that slots are updated only through strongly interacting pairs. For multiple layers, indirect connections are accounted for by composing adjacency matrices across layers, Aˉ=(AL+I)(A1+I)\bar{A} = (A^L + \mathbb{I})\cdots(A^1 + \mathbb{I}), yielding a structural causal model whose variables are the object and environment slots.

Training objective

The loss combines next-frame reconstruction MSE (computed per-object on masked images) with a penalty proportional to the total number of paths in the learned graph:

L=MSE(y^t+1,yt+1)+Aˉλ\mathcal{L} = MSE(\hat y_{t+1}, y_{t+1}) + \frac{|\bar A|}{\lambda}

A critical design element is the dynamic schedule on λ\lambda: it is initialized high and multiplied by e(MSEτ)e^{(MSE - \tau)} at each step, where τ\tau is the reconstruction error of a non-causal baseline model. Training therefore prioritizes world modelling early, then shifts weight toward graph sparsity once reconstruction reaches baseline quality. The authors note that this balance is delicate — too little regularization yields no causal model, too much suppresses all connections and destroys predictive function.

Experiments

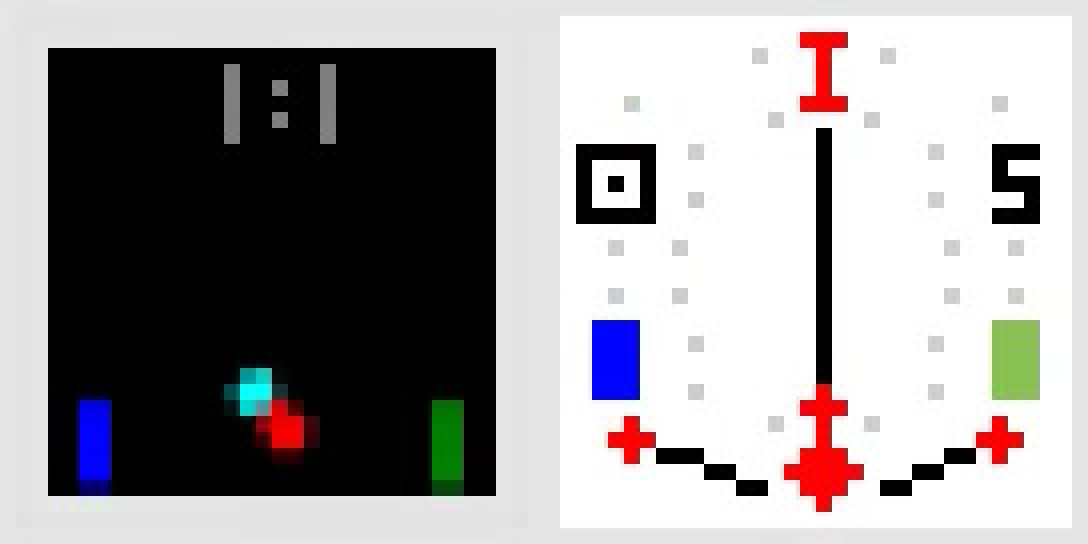
Evaluation uses the Interventional Pong dataset (2505.02074) at 32×32 resolution, with seven simple environments (including the neutral one) used for training and four composite environments reserved for testing adaptation to unseen physics. Metrics are reconstruction MSE and Structural Hamming Distance (SHD) against the ground-truth causal graph; notably, SHD is not part of the training objective — the graph emerges purely from sparsity-constrained reconstruction.

Figure 2

Figure 2

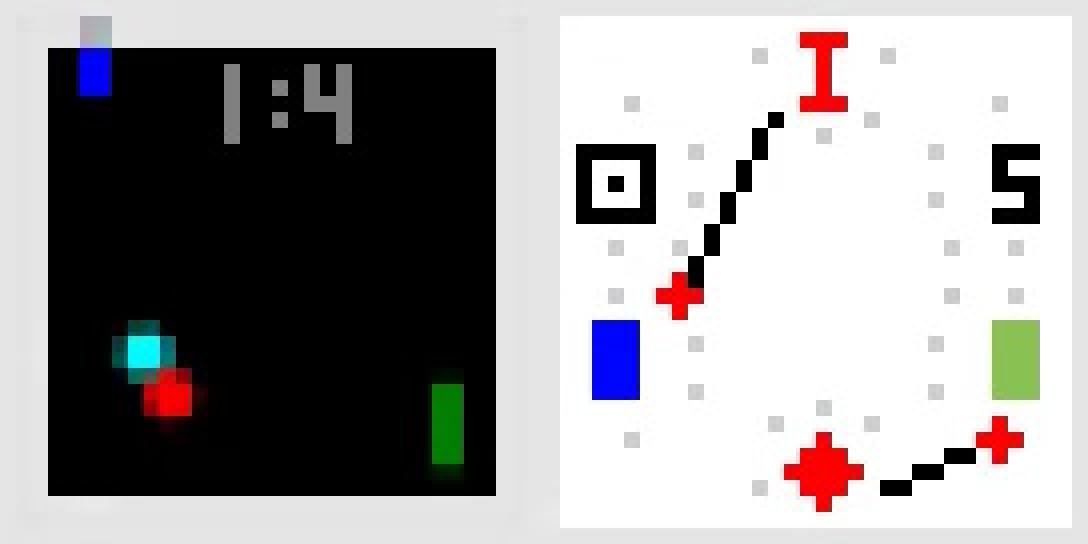
Figure 2: Qualitative example showing the reconstructed image and learned causal graph in the Midslow environment, where the ball slows in the middle section.

Average results across all interventions are summarized below.

Model MSE SHD
S2-SSM 2.901042.90 \cdot 10^{-4} 1.41
S2-TE (Transformer) 5.271045.27 \cdot 10^{-4} 11.15
dense-SSM 3.461043.46 \cdot 10^{-4} 16.40
dense-TE Aij=σ(qiTkj)A_{ij} = \sigma(q_i^T k_j)0 16.81

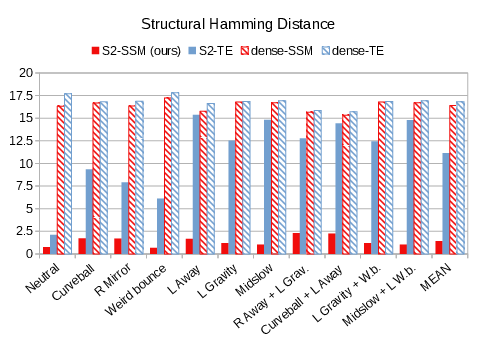
Two findings stand out. First, S2-SSM outperforms the Transformer baseline on both metrics on average, achieving an SHD of 1.41 versus 11.15 — a substantial gap in causal-graph fidelity alongside lower reconstruction error. Second, the ablation shows that removing sparsity regularization degrades SHD catastrophically (to roughly 16–17, i.e., near-complete graphs) regardless of backbone, while only mildly affecting MSE. This indicates that meaningful causal structure does not emerge from prediction accuracy alone; explicit sparsity pressure is essential.

Figure 3

Figure 3

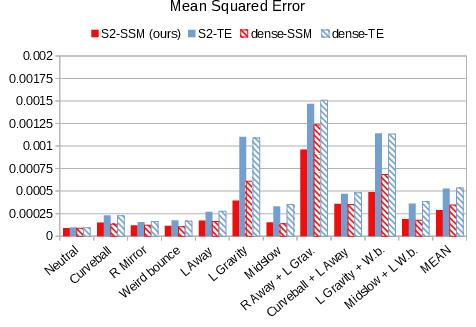
Figure 3: Mean Squared Error (MSE) separated by environment, including composite interventions unseen during training.

An important caveat accompanies the headline comparison: the original SPARTAN source code was not released, so the authors' reimplementation of S2-TE produces different numbers than those reported by Lei et al., likely due to implementation differences. However, the S2-SSM average SHD of 1.41 closely matches the 1.51 reported in the original work, lending credibility to the comparison despite the discrepancy.

Limitations and open questions

Several limitations are acknowledged or evident. Object masks are supplied by the dataset rather than discovered, sidestepping the hardest part of object-centric representation learning. The evaluation is confined to a single synthetic environment with simple, well-defined interventions; scalability to realistic scenes is untested. The causal interpretation rests on the assumption that attention weights reflect causal influence, an assumption inherited from prior work rather than established here. Finally, the claimed advantages of SSMs — long-range memory and efficiency — are not directly exercised by these experiments, since interventions are given via slots rather than inferred from history.

Conclusion

This paper provides preliminary but consistent evidence that SlotSSM-based world models can learn local causal graphs as effectively as, and in these experiments better than, equivalent sparse Transformers, while also adapting to unseen composite environments through few-shot intervention-slot learning. The ablation confirms that sparsity regularization, not the choice of sequence-model backbone, is what makes causal discovery possible. The open questions left by the work concern whether SSMs' distinctive memory capacity can be exploited for causal modelling when interventions must be inferred from past observations, and whether such models can track objects under occlusion.

Whiteboard

No one has generated a whiteboard explanation for this paper yet.

Knowledge Gaps

Knowledge gaps, limitations, and open questions

Below is a single consolidated list of what remains missing, uncertain, or unexplored in the paper, framed to guide future research:

  • Reliance on provided object masks sidesteps the harder problem of learning object-centric slots from raw pixels; robustness of the causal graph when segmentation is learned (unsupervised or weakly supervised) is untested.
  • Evaluation is confined to a single small synthetic dataset (Interventional Pong) with few objects and simple physics; scalability to more complex, higher-resolution, or real-world environments is unknown.
  • The causal interpretation of attention weights is assumed but not theoretically justified; the conditions under which attention-derived edges reflect true causal relations (vs. correlations) are not established.
  • Acyclicity, causal directionality, and identifiability are not enforced or analyzed; the learned graphs may contain cycles or ambiguous directions, conflicting with DAG-based SCM assumptions.
  • The procedure for binarizing weighted attentions into edges for SHD (e.g., thresholds, per-layer aggregation, calibration) is not specified, leaving the causal evaluation pipeline underdetermined.
  • Multi-head attention handling in causal graph extraction is unspecified (e.g., per-head graphs, aggregation rules), limiting interpretability and reproducibility.
  • The “paths across layers” construction Aˉ=(A+I)\bar A = \prod_\ell (A^\ell + \mathbb{I}) lacks a clear causal semantics, normalization, or sensitivity analysis; whether it faithfully captures indirect influences is unclear.
  • Only contemporaneous (within-step) edges are modeled; explicit time-lagged causal relationships (dynamic causal graphs over multiple time steps) are not considered.
  • In testing, only the environment slot is updated with a small few-shot set while the world model remains frozen; how to adapt dynamics when interventions require updating transition functions is left open.
  • The capacity, selection, and training dynamics of the environment codebook are under-specified (e.g., number of codes, assignment mechanism, failure modes with many or overlapping environments).
  • Claims that new environments can be added during training are not experimentally demonstrated; zero-shot or continual adaptation protocols are not assessed.
  • The loss omits mention of standard VAE regularization (e.g., KL divergence); it is unclear whether a KL term is used, how it is weighted, and how posterior collapse is avoided.
  • Sensitivity of performance and discovered graphs to the sparsity weight schedule (dynamic λ\lambda) and the baseline target τ\tau is not explored; no ablation on schedule design is provided.
  • No analysis of variance across random seeds, confidence intervals, or statistical significance; robustness of reported improvements is uncertain.
  • Parameter parity and training budget parity between S2-SSM and Transformer baselines are not documented; fair comparison is uncertain.
  • The method allows edges from objects to the environment slot; whether the environment is treated as an exogenous cause (and whether enforcing that improves results) is unexplored.
  • Higher-order (non-pairwise) interactions are not modeled explicitly; whether cross-attention suffices for triadic or collective effects remains an open question.
  • Long-horizon rollouts and compounding error are not evaluated; benefits of SSM memory for multi-step prediction or planning are not demonstrated.
  • No assessment of inference speed, memory footprint, or hardware efficiency, despite SSMs’ touted advantages; practical trade-offs remain unquantified.
  • Robustness to occlusions, partial observability, missing objects, variable object counts, and dynamic appearance/disappearance is not tested.
  • Noise robustness (sensor noise, distractors, background clutter) and domain shift beyond the provided composite environments are not examined.
  • No counterfactual or interventional validation (e.g., do-predictions) is performed to test whether the learned graph supports causal reasoning beyond SHD.
  • Generalization to tasks beyond next-frame prediction (e.g., control, planning, counterfactual reasoning) is not investigated.
  • Comparison set is narrow (Transformer baseline and ablations); benchmarking against graph/relational baselines (e.g., NRI, GNN-based causal learners) is missing.
  • The approach assumes a fixed number of slots/objects; how to handle varying or unknown numbers of entities is not addressed.
  • Potential confounding by unobserved factors is only heuristically addressed via an environment slot; formal treatment of latent confounders and its limits is absent.
  • The mapping from attention to causal strength (sigmoid of qikjq_i^\top k_j) and its reuse as an attention mask may introduce circularity; alternative metrics and their impact are not explored.
  • Ground-truth graph definitions for each environment and their directionality (especially with interventions) are not detailed, making SHD interpretability opaque.
  • Reproducibility is limited by missing implementation details (e.g., training hyperparameters, thresholds, code availability).

Open Problems

We haven't generated a list of open problems mentioned in this paper yet.