A Clean Slate for Offline Reinforcement Learning
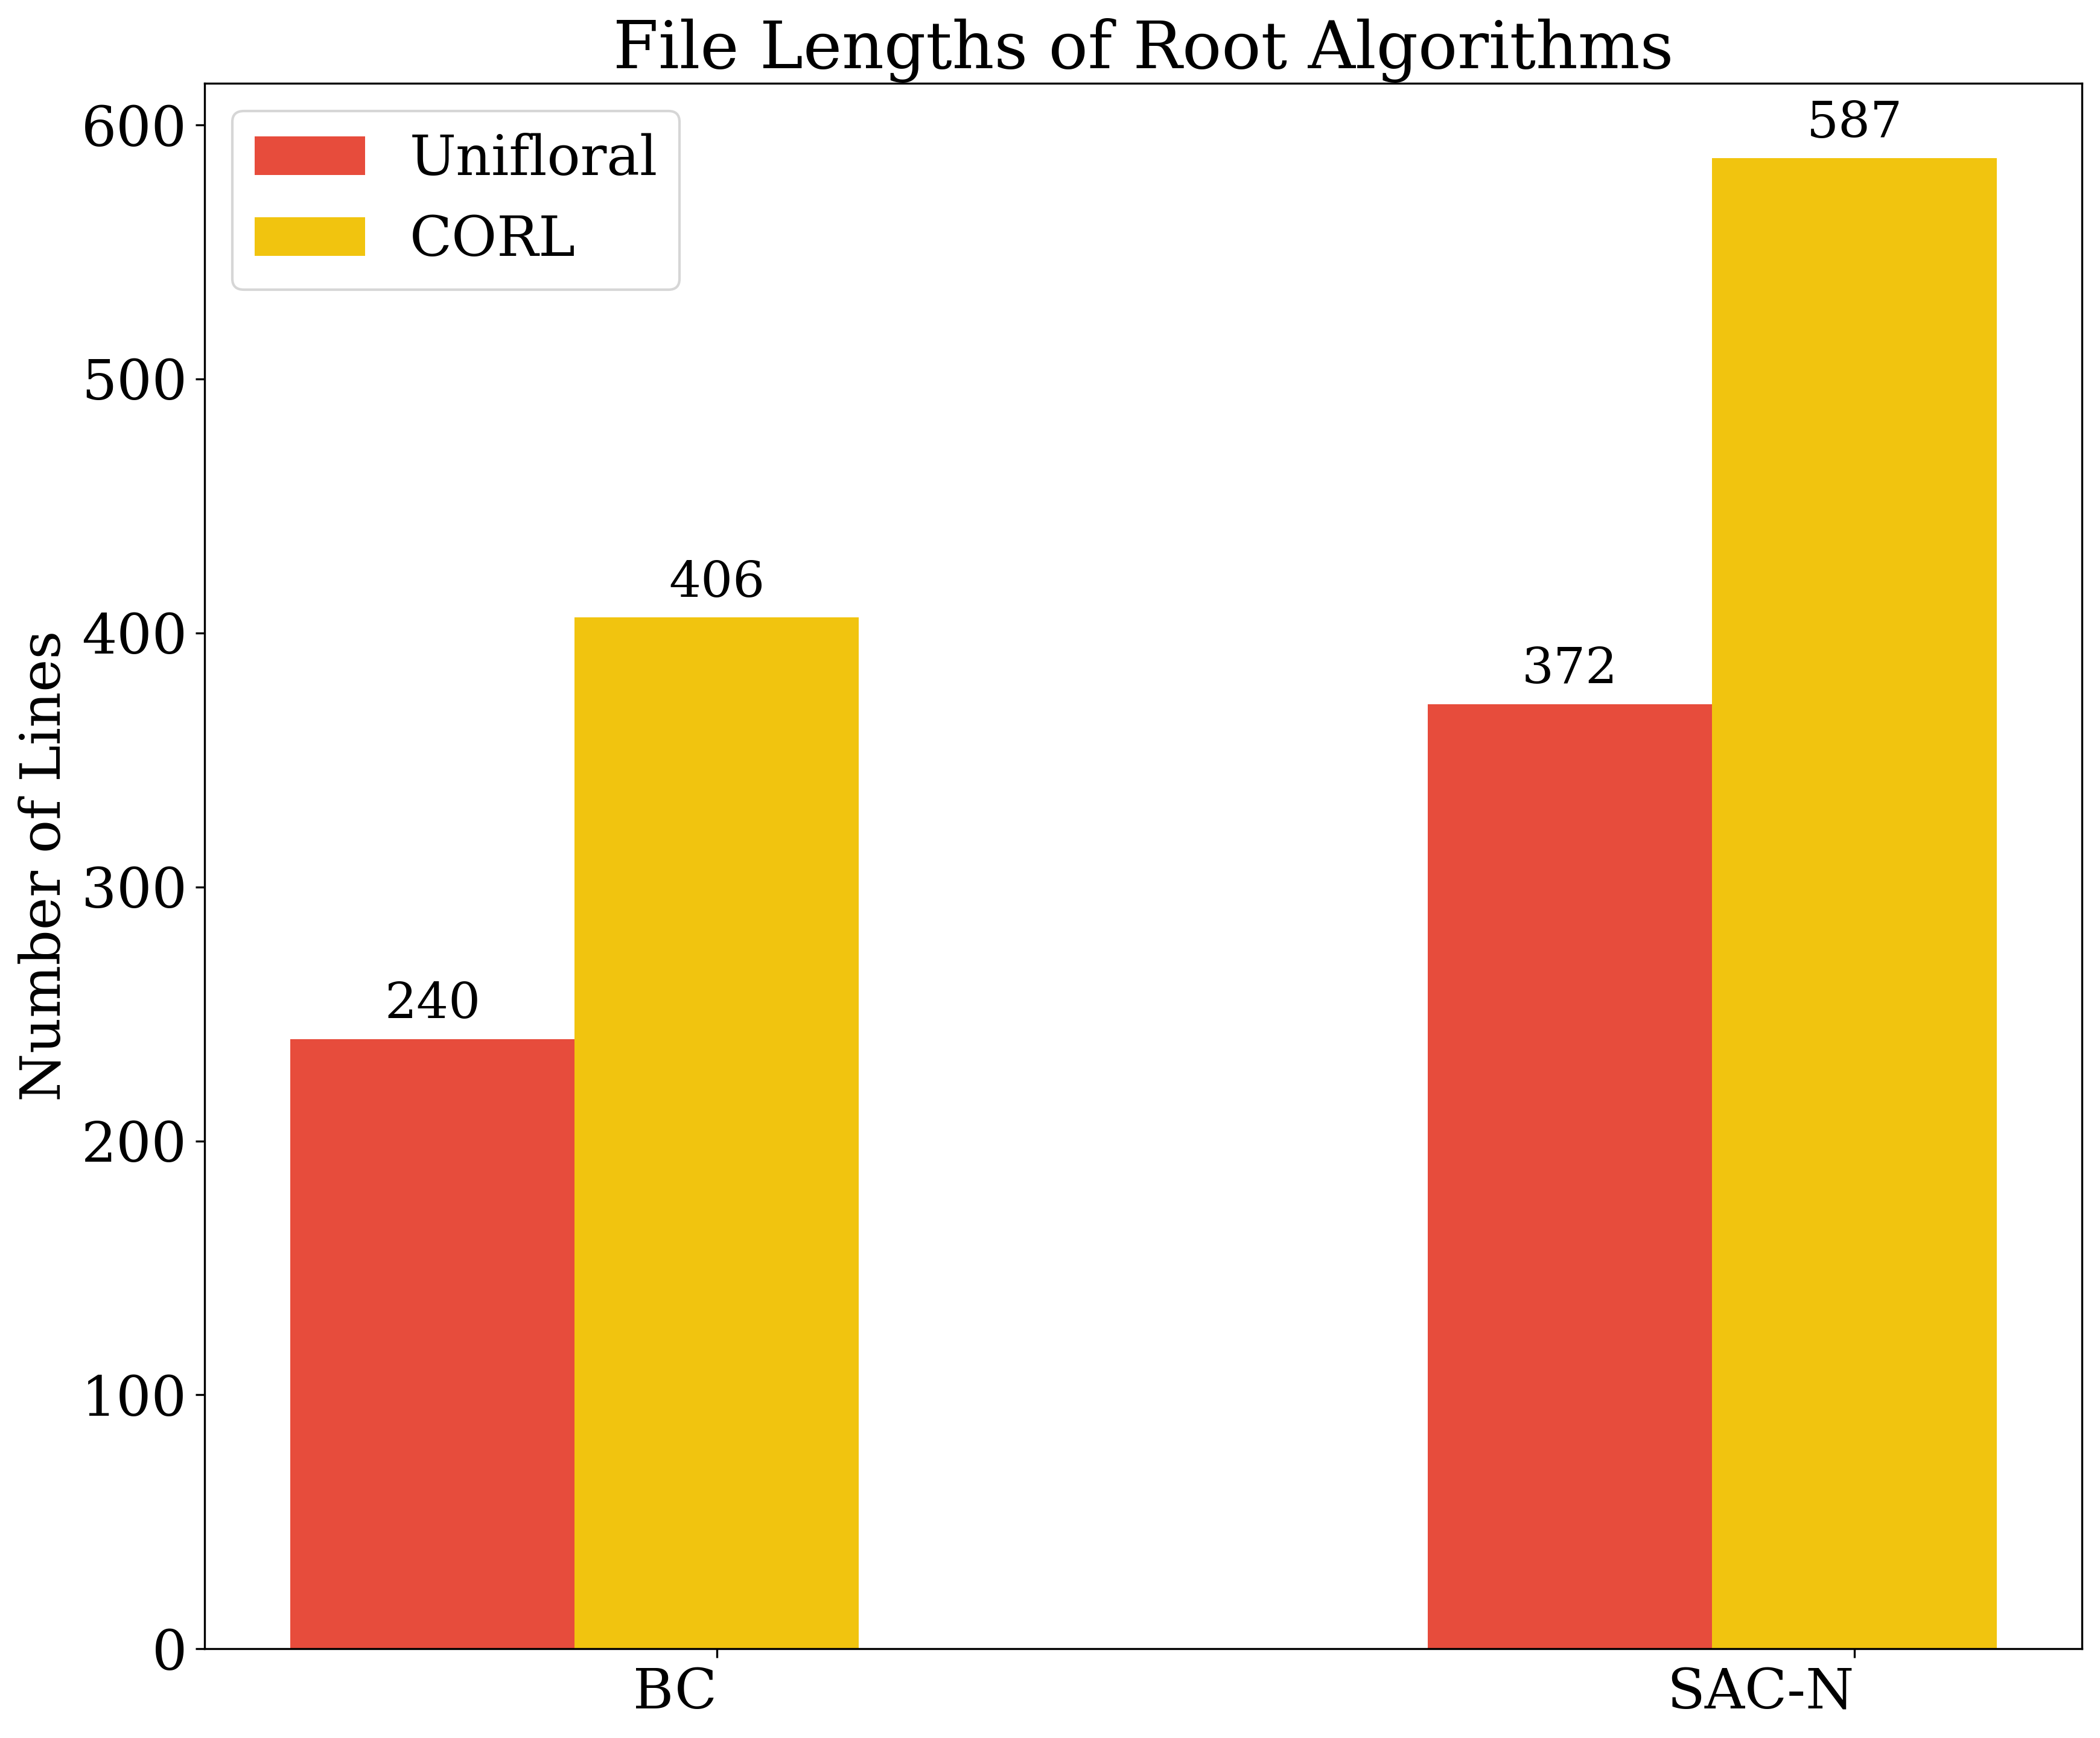
Abstract: Progress in offline reinforcement learning (RL) has been impeded by ambiguous problem definitions and entangled algorithmic designs, resulting in inconsistent implementations, insufficient ablations, and unfair evaluations. Although offline RL explicitly avoids environment interaction, prior methods frequently employ extensive, undocumented online evaluation for hyperparameter tuning, complicating method comparisons. Moreover, existing reference implementations differ significantly in boilerplate code, obscuring their core algorithmic contributions. We address these challenges by first introducing a rigorous taxonomy and a transparent evaluation protocol that explicitly quantifies online tuning budgets. To resolve opaque algorithmic design, we provide clean, minimalistic, single-file implementations of various model-free and model-based offline RL methods, significantly enhancing clarity and achieving substantial speed-ups. Leveraging these streamlined implementations, we propose Unifloral, a unified algorithm that encapsulates diverse prior approaches within a single, comprehensive hyperparameter space, enabling algorithm development in a shared hyperparameter space. Using Unifloral with our rigorous evaluation protocol, we develop two novel algorithms - TD3-AWR (model-free) and MoBRAC (model-based) - which substantially outperform established baselines. Our implementation is publicly available at https://github.com/EmptyJackson/unifloral.
Paper Prompts
Sign up for free to create and run prompts on this paper.
Top Community Prompts
Explain it Like I'm 14
1. What is this paper about?
This paper is about offline reinforcement learning, or offline RL.
In reinforcement learning, an AI agent learns by trying actions and receiving rewards. For example, a robot might learn to walk by testing different movements. However, experimenting in the real world can be expensive, dangerous, or slow.
In offline RL, the agent does not practice directly in the real world. Instead, it learns from a previously collected dataset containing examples of:
- what situation the agent was in,
- what action it took,
- what reward it received, and
- what happened next.
The paper argues that offline RL research has two major problems:
- Researchers do not always agree on what “offline RL” should allow.
- Existing algorithms are often complicated combinations of many ideas, making them difficult to compare fairly.
The authors propose clearer rules for testing offline RL and create a unified system called Unifloral to make algorithms easier to understand and compare.
2. What questions are the researchers asking?
The paper focuses on several main questions:
- How should offline RL be defined and tested? For example, should researchers be allowed to try a policy in the real environment while choosing the best settings?
- How much online testing is secretly being used? An algorithm may be called “offline,” but researchers might still test many versions of it in the environment to find the best one.
- Which parts of existing algorithms actually matter? Many algorithms contain several techniques mixed together, so it is hard to know which idea caused an improvement.
- Can different algorithms be placed into one common framework?
- Can combining the strongest ideas from different algorithms create better methods?
To answer these questions, the researchers develop two new algorithms:
- TD3-AWR, which does not use a learned model of the environment.
- MoBRAC, which does use a learned model of the environment.
3. How did the researchers carry out the study?
Offline reinforcement learning in simple terms
Imagine that an AI is learning to play a game, but it is only given a recording of someone else playing. The AI can study the recording, but it cannot freely play the game while learning.
The recording is the offline dataset. It may contain good, bad, or incomplete examples. This creates a problem: the AI might try an action that was never shown in the dataset and incorrectly believe that the action will work well.
Offline RL algorithms therefore need to be careful. They must learn from the data without becoming too confident about actions they have never seen.
Creating categories for offline RL
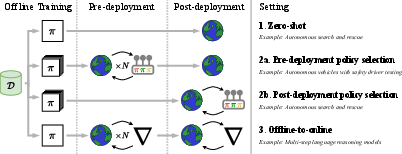
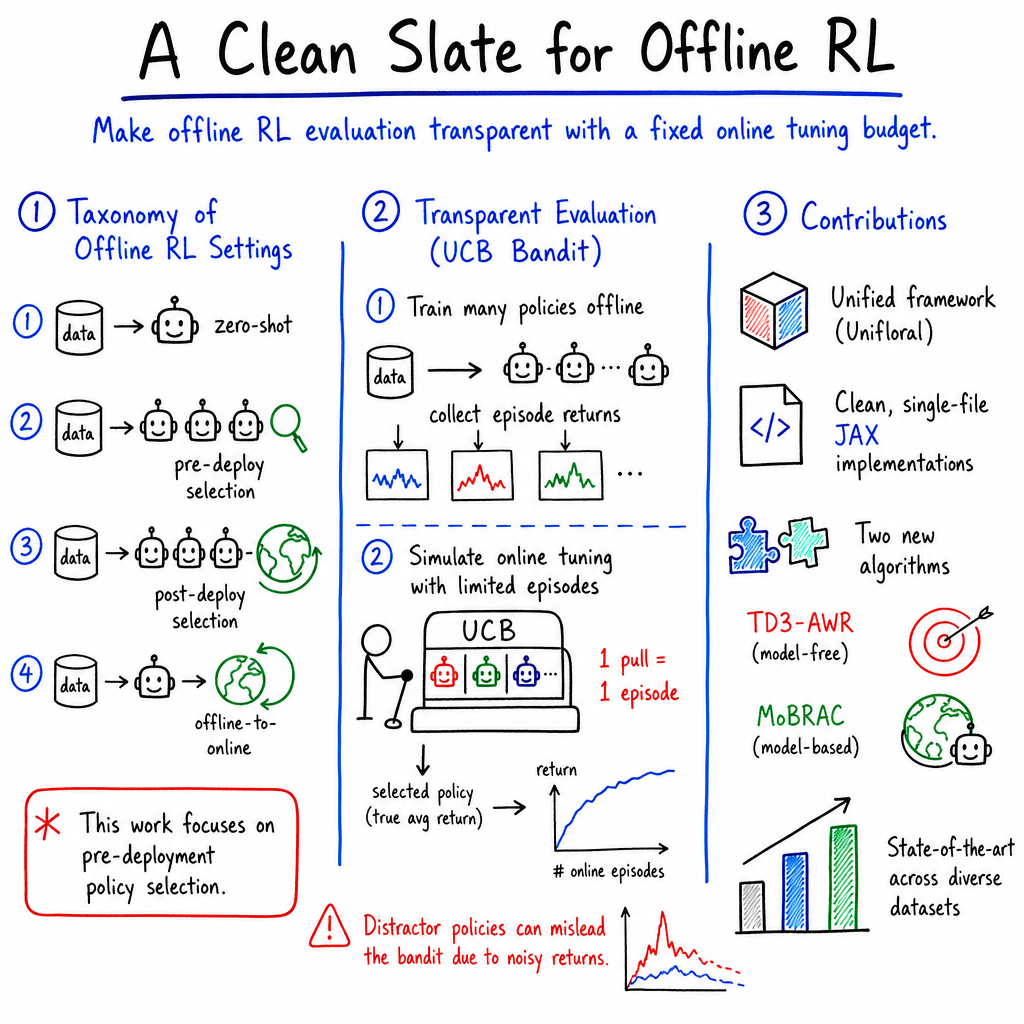
The authors divide offline RL into four possible settings:
- Zero-shot offline RL: Train one policy using only old data, then use it without further changes.
- Pre-deployment policy selection: Train several policies and briefly test them in the real environment before choosing one.
- Post-deployment policy selection: Start using several policies and choose among them based on their performance.
- Offline-to-online RL: Train offline first, then continue improving the policy with new online experience.
The authors mainly study the second setting: training several policies and using a limited number of real-world tests to choose the best one.
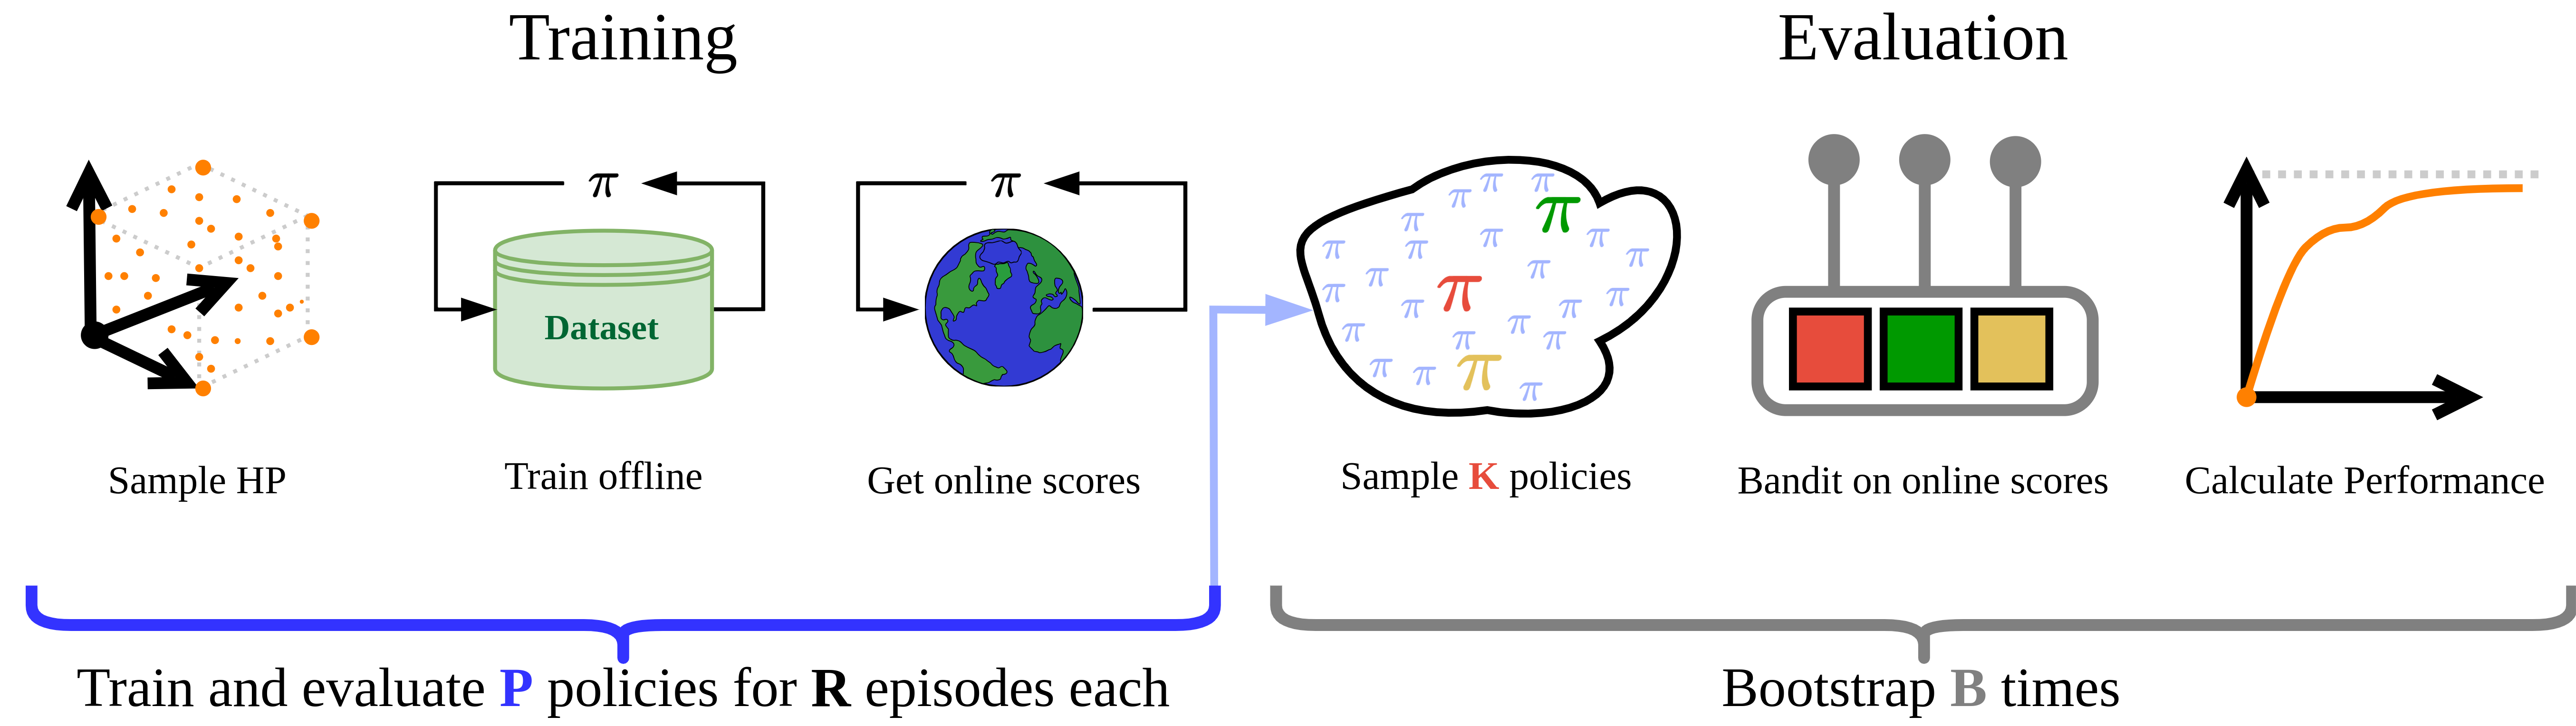
Testing policies with a “bandit”
The researchers use a method called a multi-armed bandit. The name comes from gambling machines: imagine several slot machines, each with an unknown chance of giving a reward. You want to discover which machine is best while using as few attempts as possible.
Here, each “arm” is a different trained policy. The researchers:
- Train many policies using different settings.
- Give each policy a limited number of test episodes.
- Use the results to decide which policy appears best.
- Measure how well the chosen policy really performs.
This is more realistic than simply testing every policy many times, because real-world tests can be expensive or risky.
Rebuilding existing algorithms
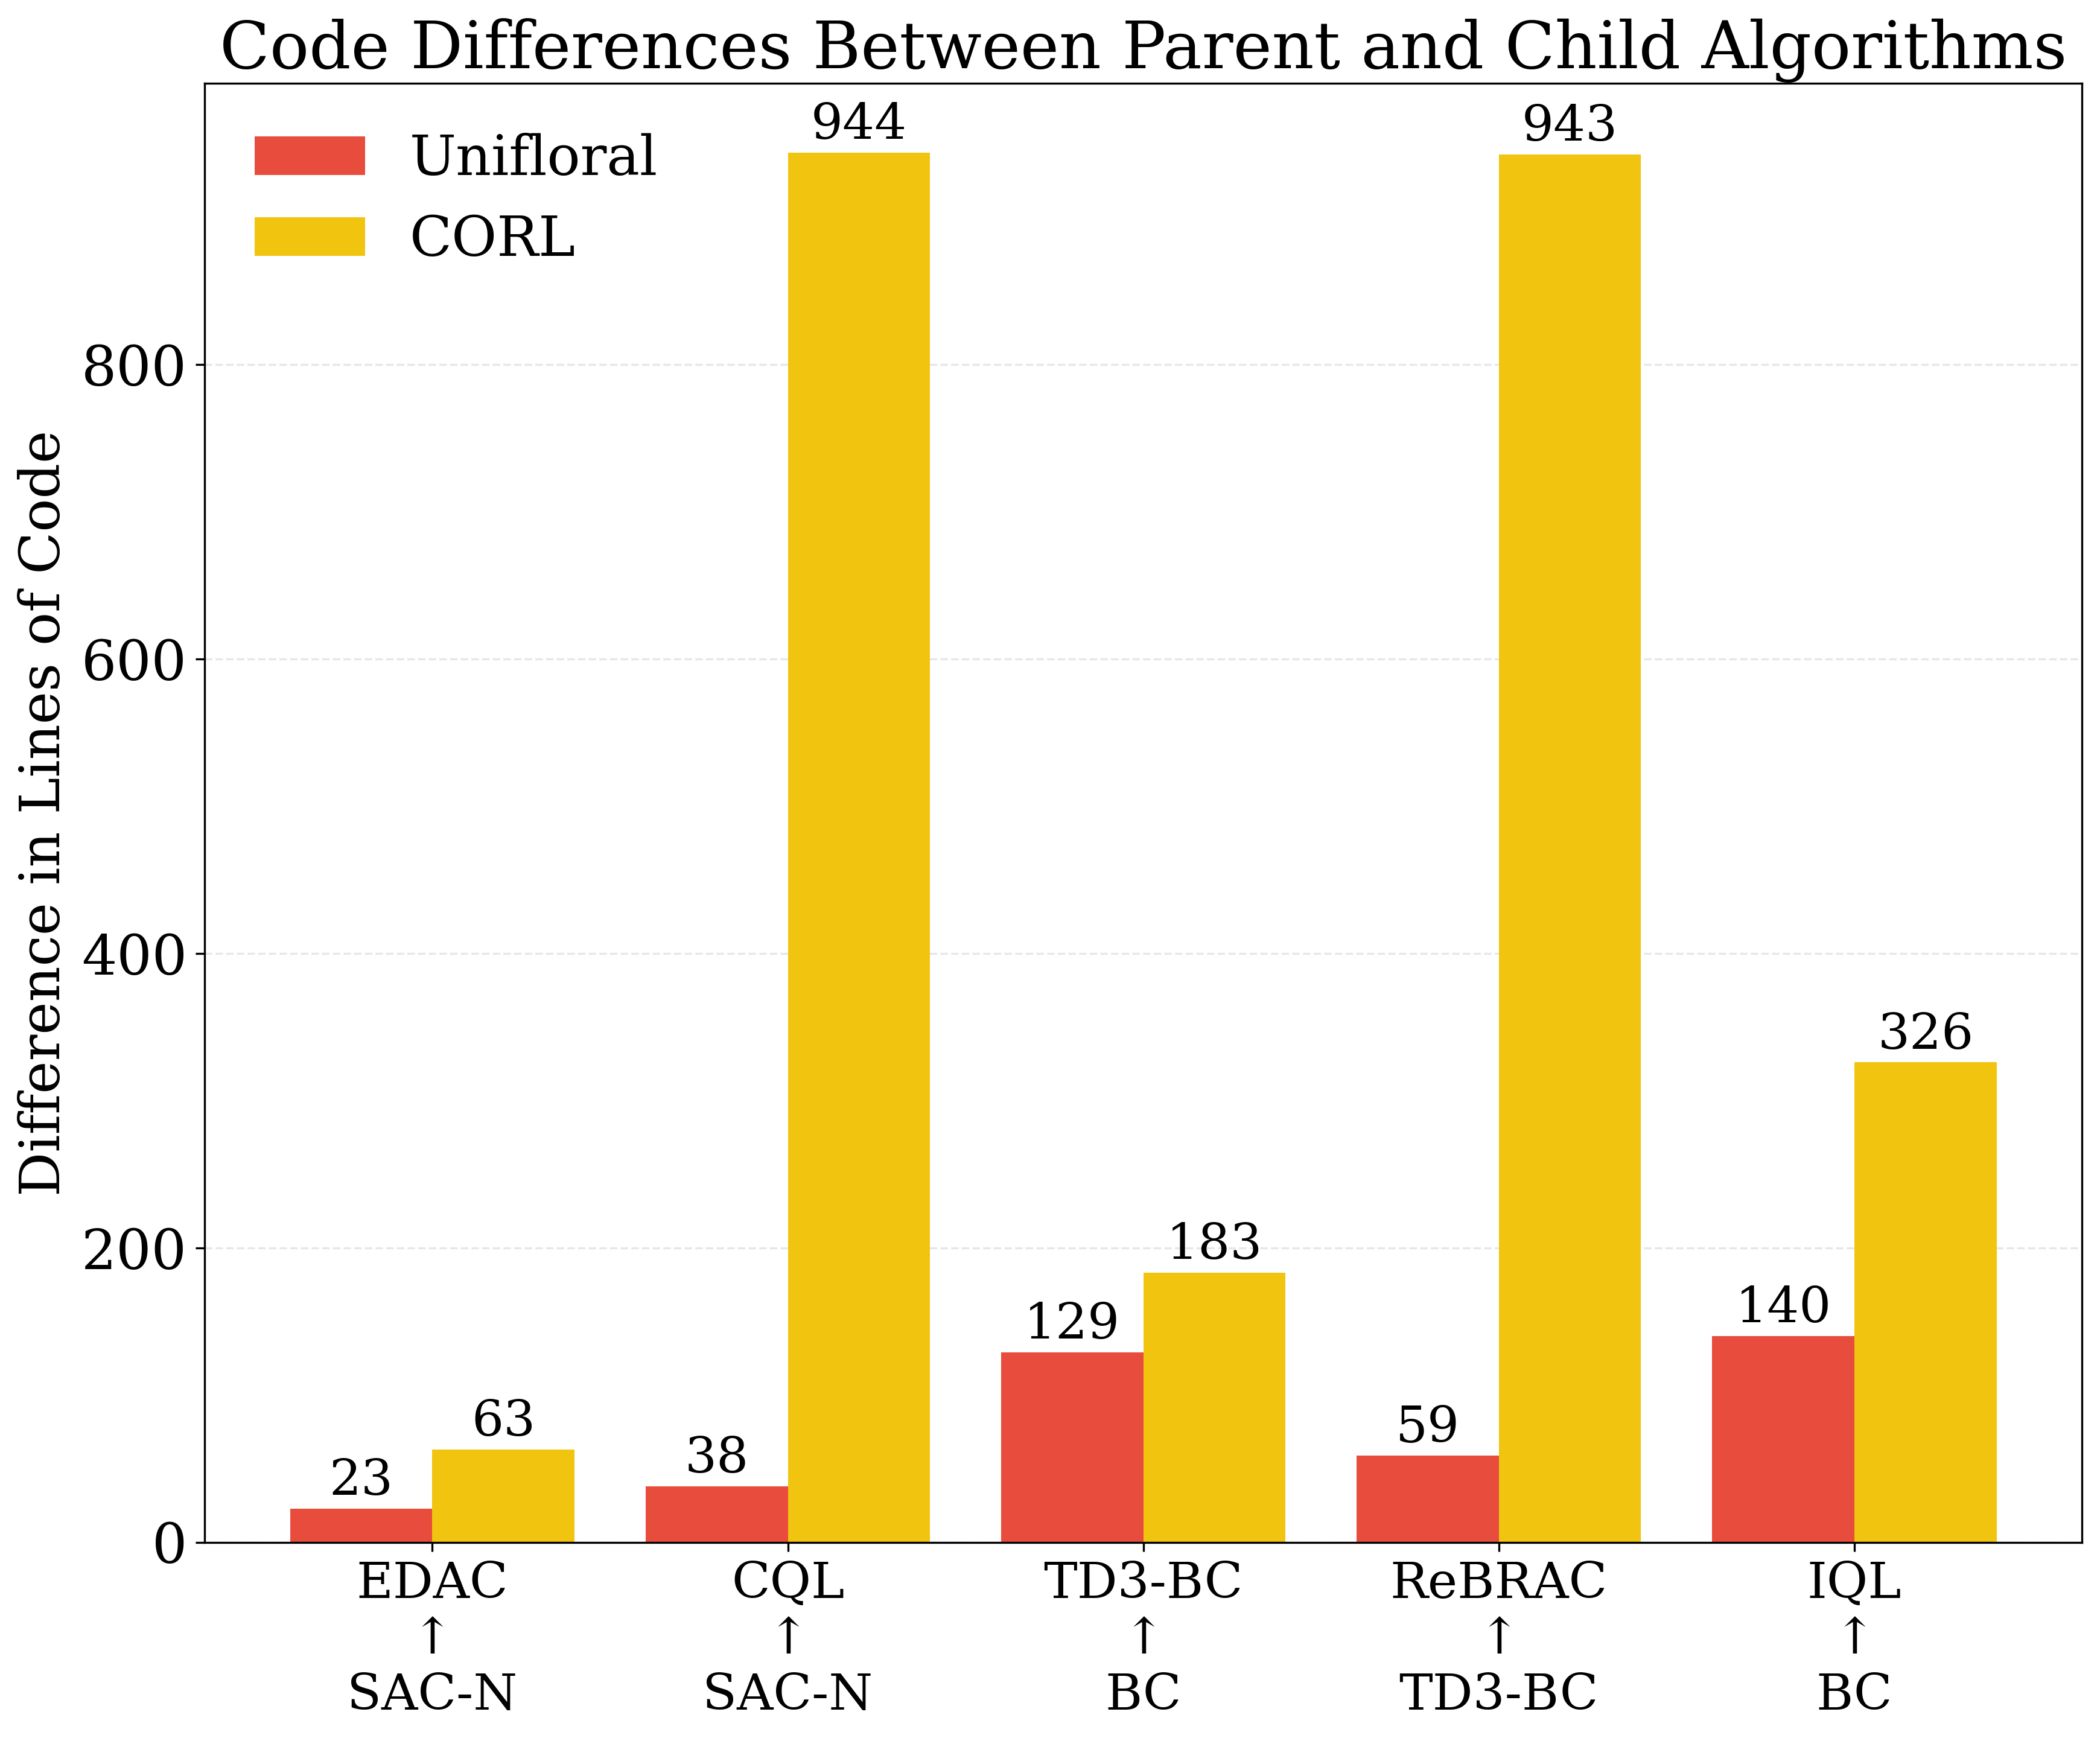
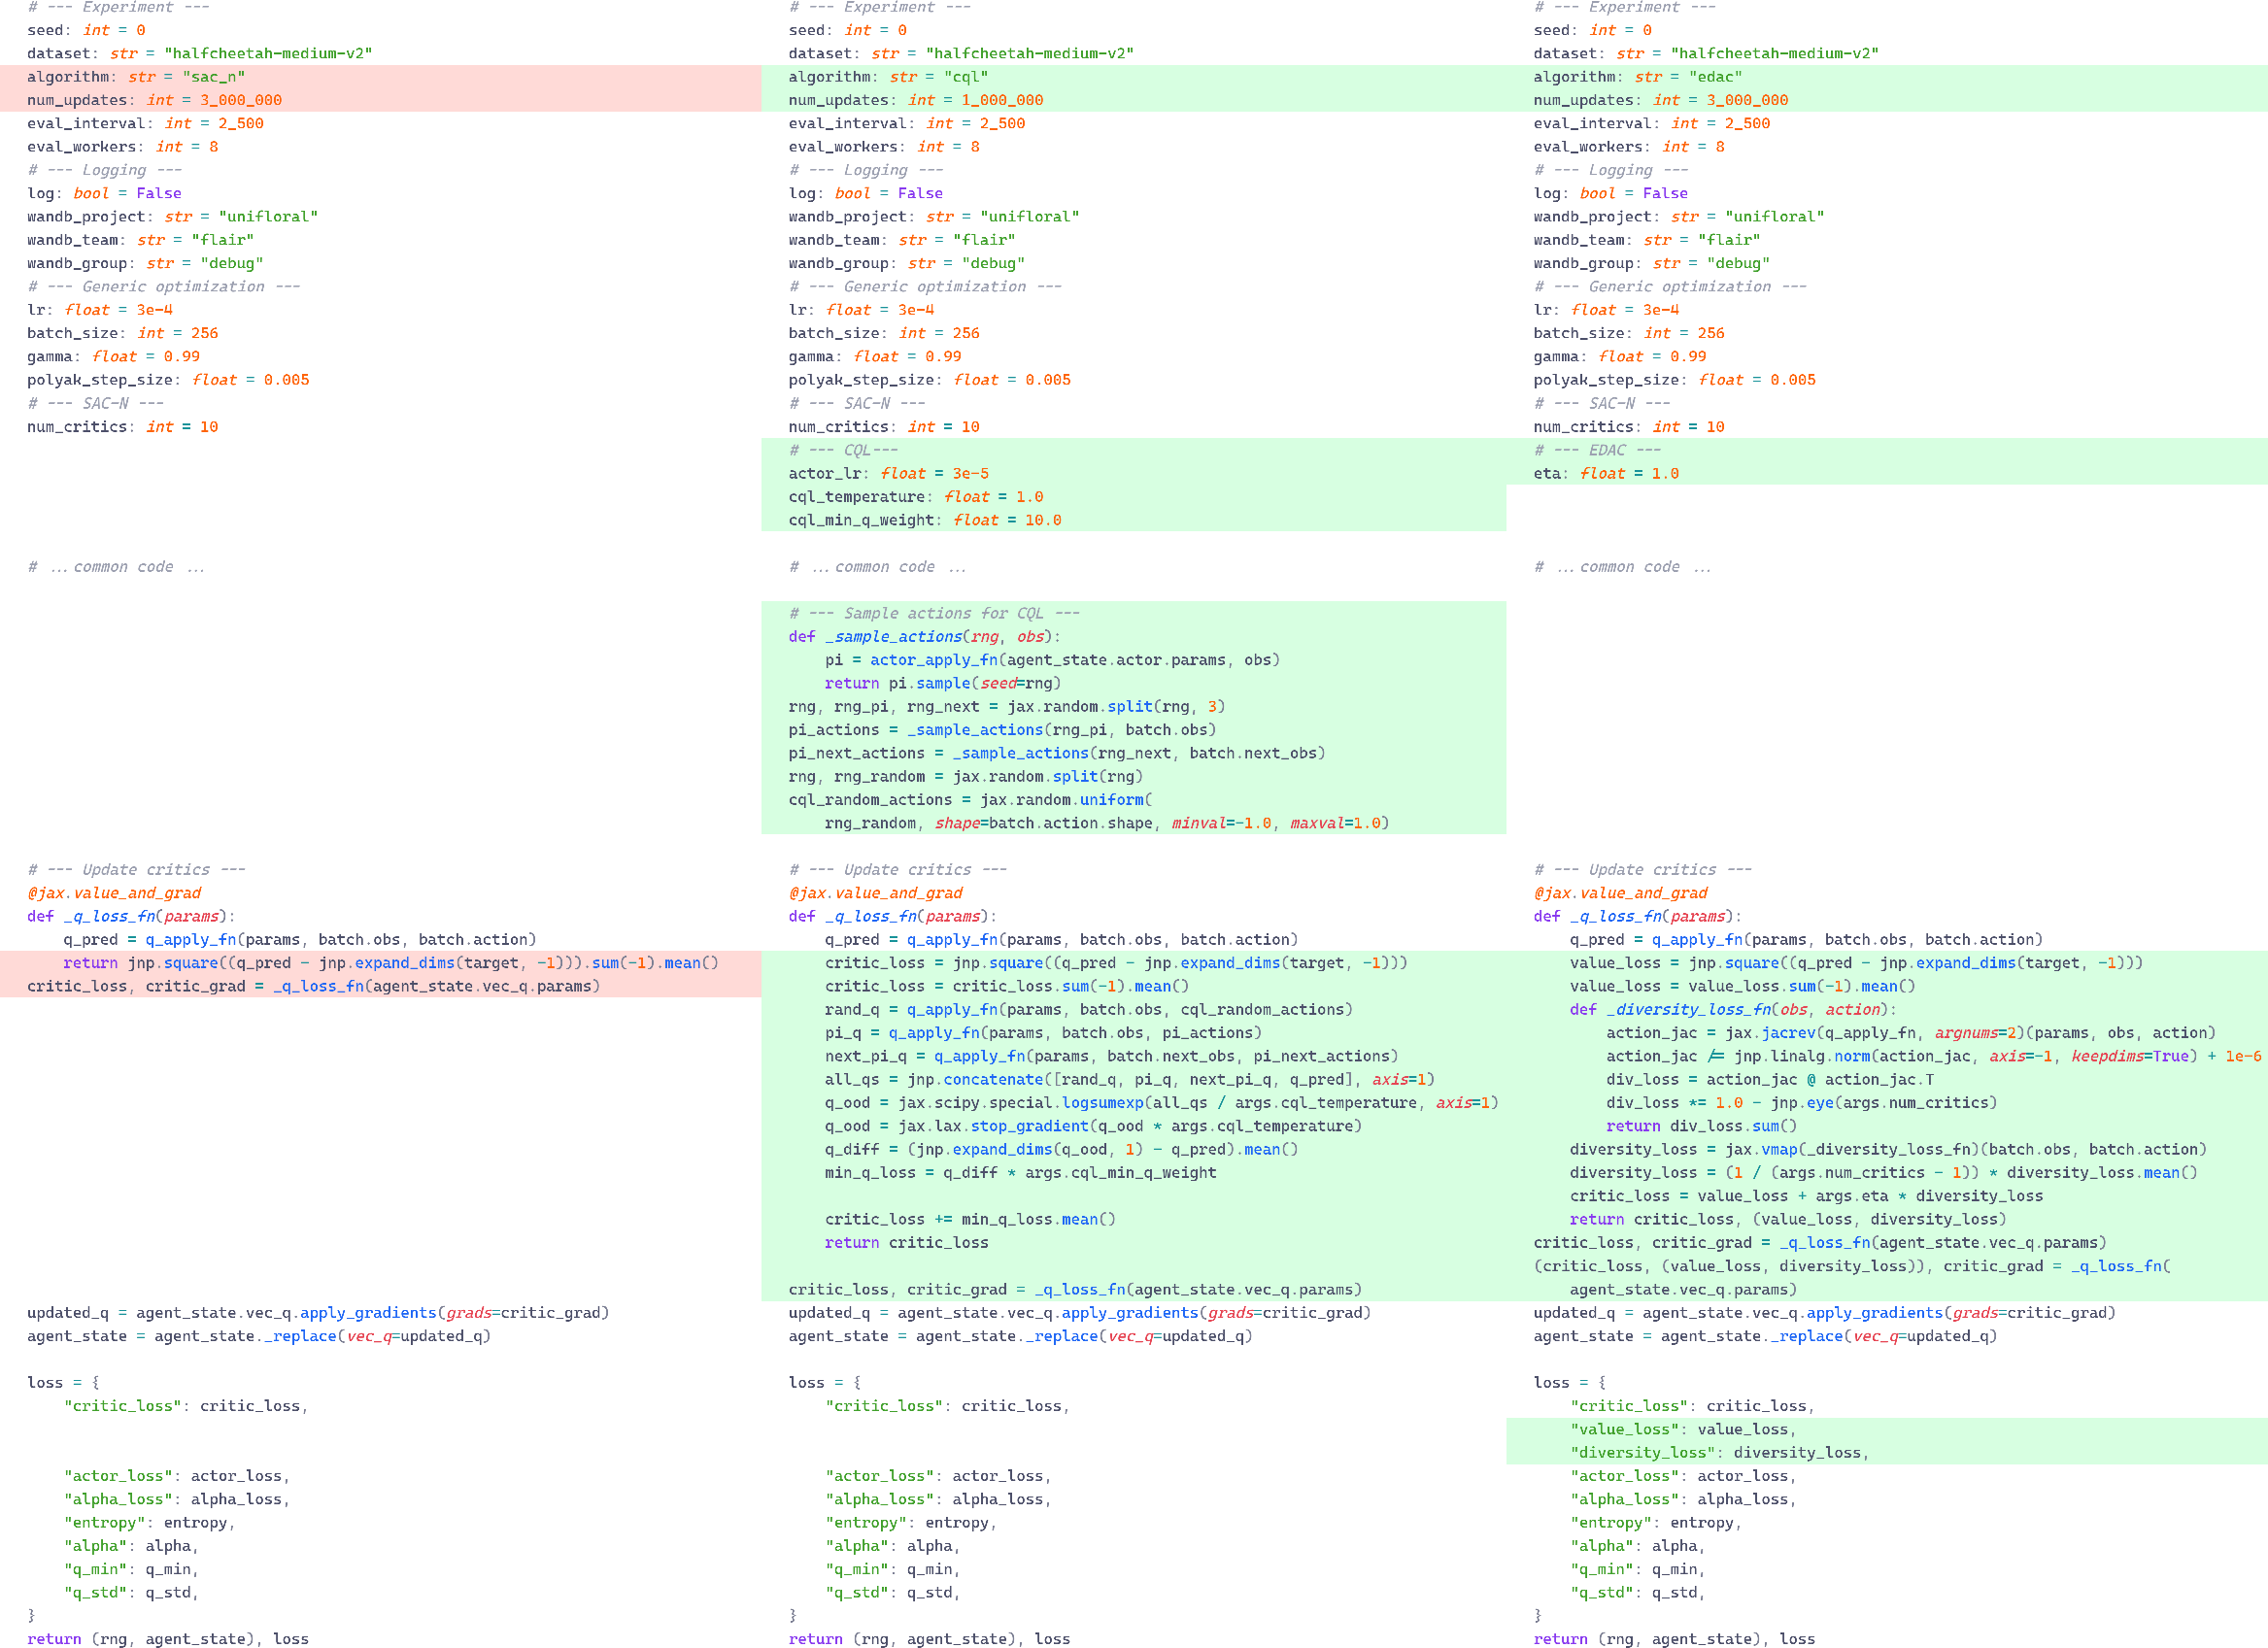
The researchers also rewrite many existing offline RL algorithms in a simpler and more consistent way. They use single-file implementations so that the differences between algorithms are easier to see.
They implement both:
- Model-free methods, which learn directly how to choose actions.
- Model-based methods, which first learn a model of how the environment works and then use that model to plan.
A model-based method is similar to learning a simulator. For example, an AI could learn that pressing a certain button usually makes a robot move forward, then use this learned prediction to plan future actions.
Building Unifloral
The authors combine important parts of many algorithms into one framework called Unifloral.
Unifloral has settings for:
- the design of the AI’s neural networks,
- how it estimates the value of actions,
- how it copies useful actions from the dataset,
- how much randomness the policy uses, and
- whether it learns a model of the environment.
This allows researchers to combine ideas without rewriting the entire program each time.
4. What did the researchers find?
Existing algorithms do not always perform consistently
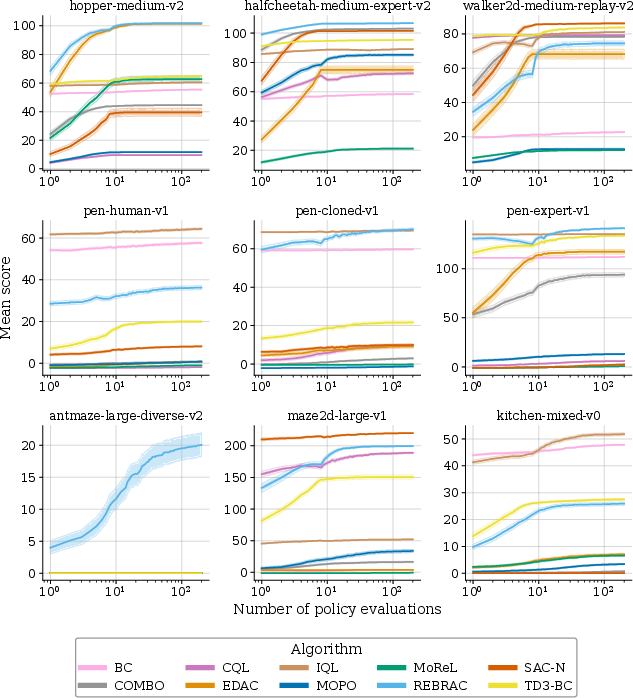
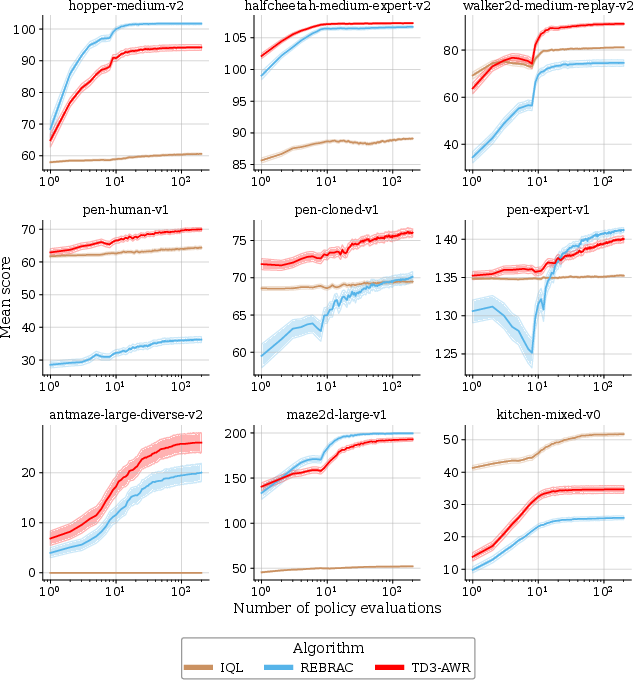
No single existing algorithm was the best on every dataset.
Two algorithms, ReBRAC and IQL, were often strong overall:
- ReBRAC performed best on some of the tested tasks.
- IQL performed best on others.
However, both also performed poorly on certain tasks. This means that claims such as “this is the best offline RL algorithm” may depend heavily on the task and testing procedure.
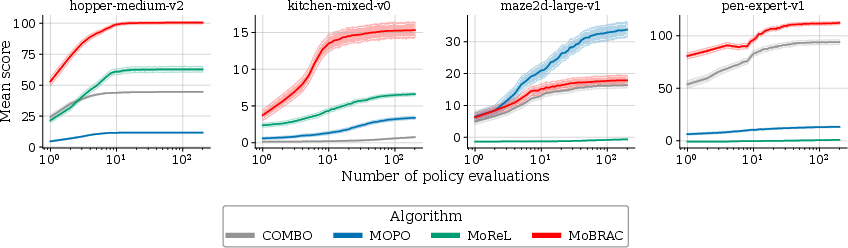
Some model-based methods worked poorly outside their original tasks
The model-based methods MOPO, MOReL, and COMBO performed especially poorly on many non-locomotion tasks.
This suggests that some algorithms may have been designed or tuned too closely for particular benchmarks, such as robot movement tasks. An algorithm that works well for teaching a robot to walk may not work well for navigating a maze or completing kitchen activities.
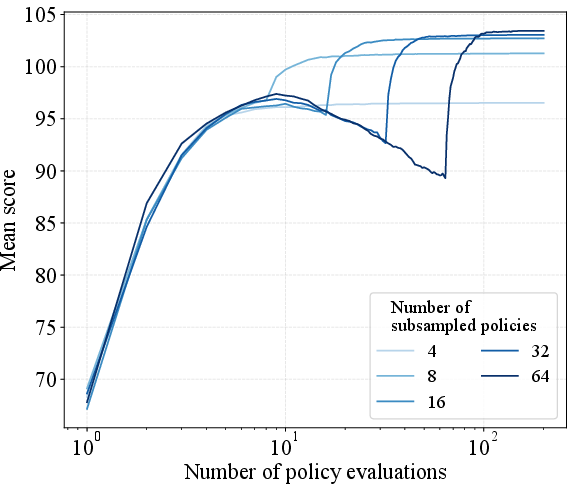
More testing does not always immediately lead to better choices
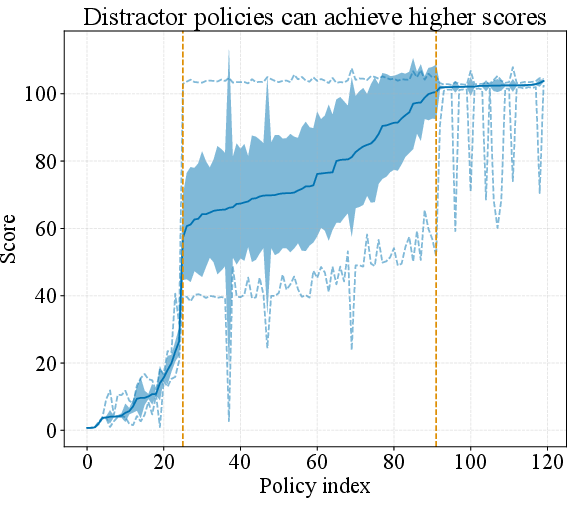
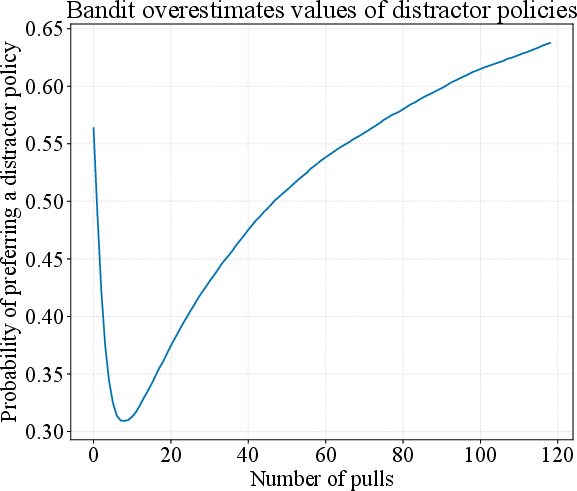
The authors discovered a problem called the distractor policy phenomenon.
A distractor policy is a policy that usually performs badly but occasionally gets an unusually high score. If it happens to perform well during a small number of test episodes, the evaluation system may mistakenly choose it.
This is similar to judging basketball players after only one shot. A weaker player might get lucky and make that shot, while a stronger player might miss. More tests usually help, but the results may not improve smoothly every time.
This finding is important because it shows that policy evaluation can be noisy and unpredictable. The number of online tests used should therefore be clearly reported.
The new TD3-AWR algorithm performed strongly
TD3-AWR combines ideas from:
- ReBRAC, which uses value estimates to improve actions, and
- IQL, which gives extra importance to actions that appear better than average.
The new algorithm performed better than ReBRAC on 6 of 9 datasets and better than IQL on 7 of 9 datasets.
This suggests that combining useful parts of different algorithms can lead to improvements.
The new MoBRAC algorithm improved model-based learning
MoBRAC combines:
- a learned model of the environment from MOPO, and
- the policy-training approach used by ReBRAC.
MoBRAC performed better than the other model-based methods on most of the tested datasets. It was the strongest model-based method on 6 of 9 datasets and tied for the best on the other 3.
The new implementations were much faster
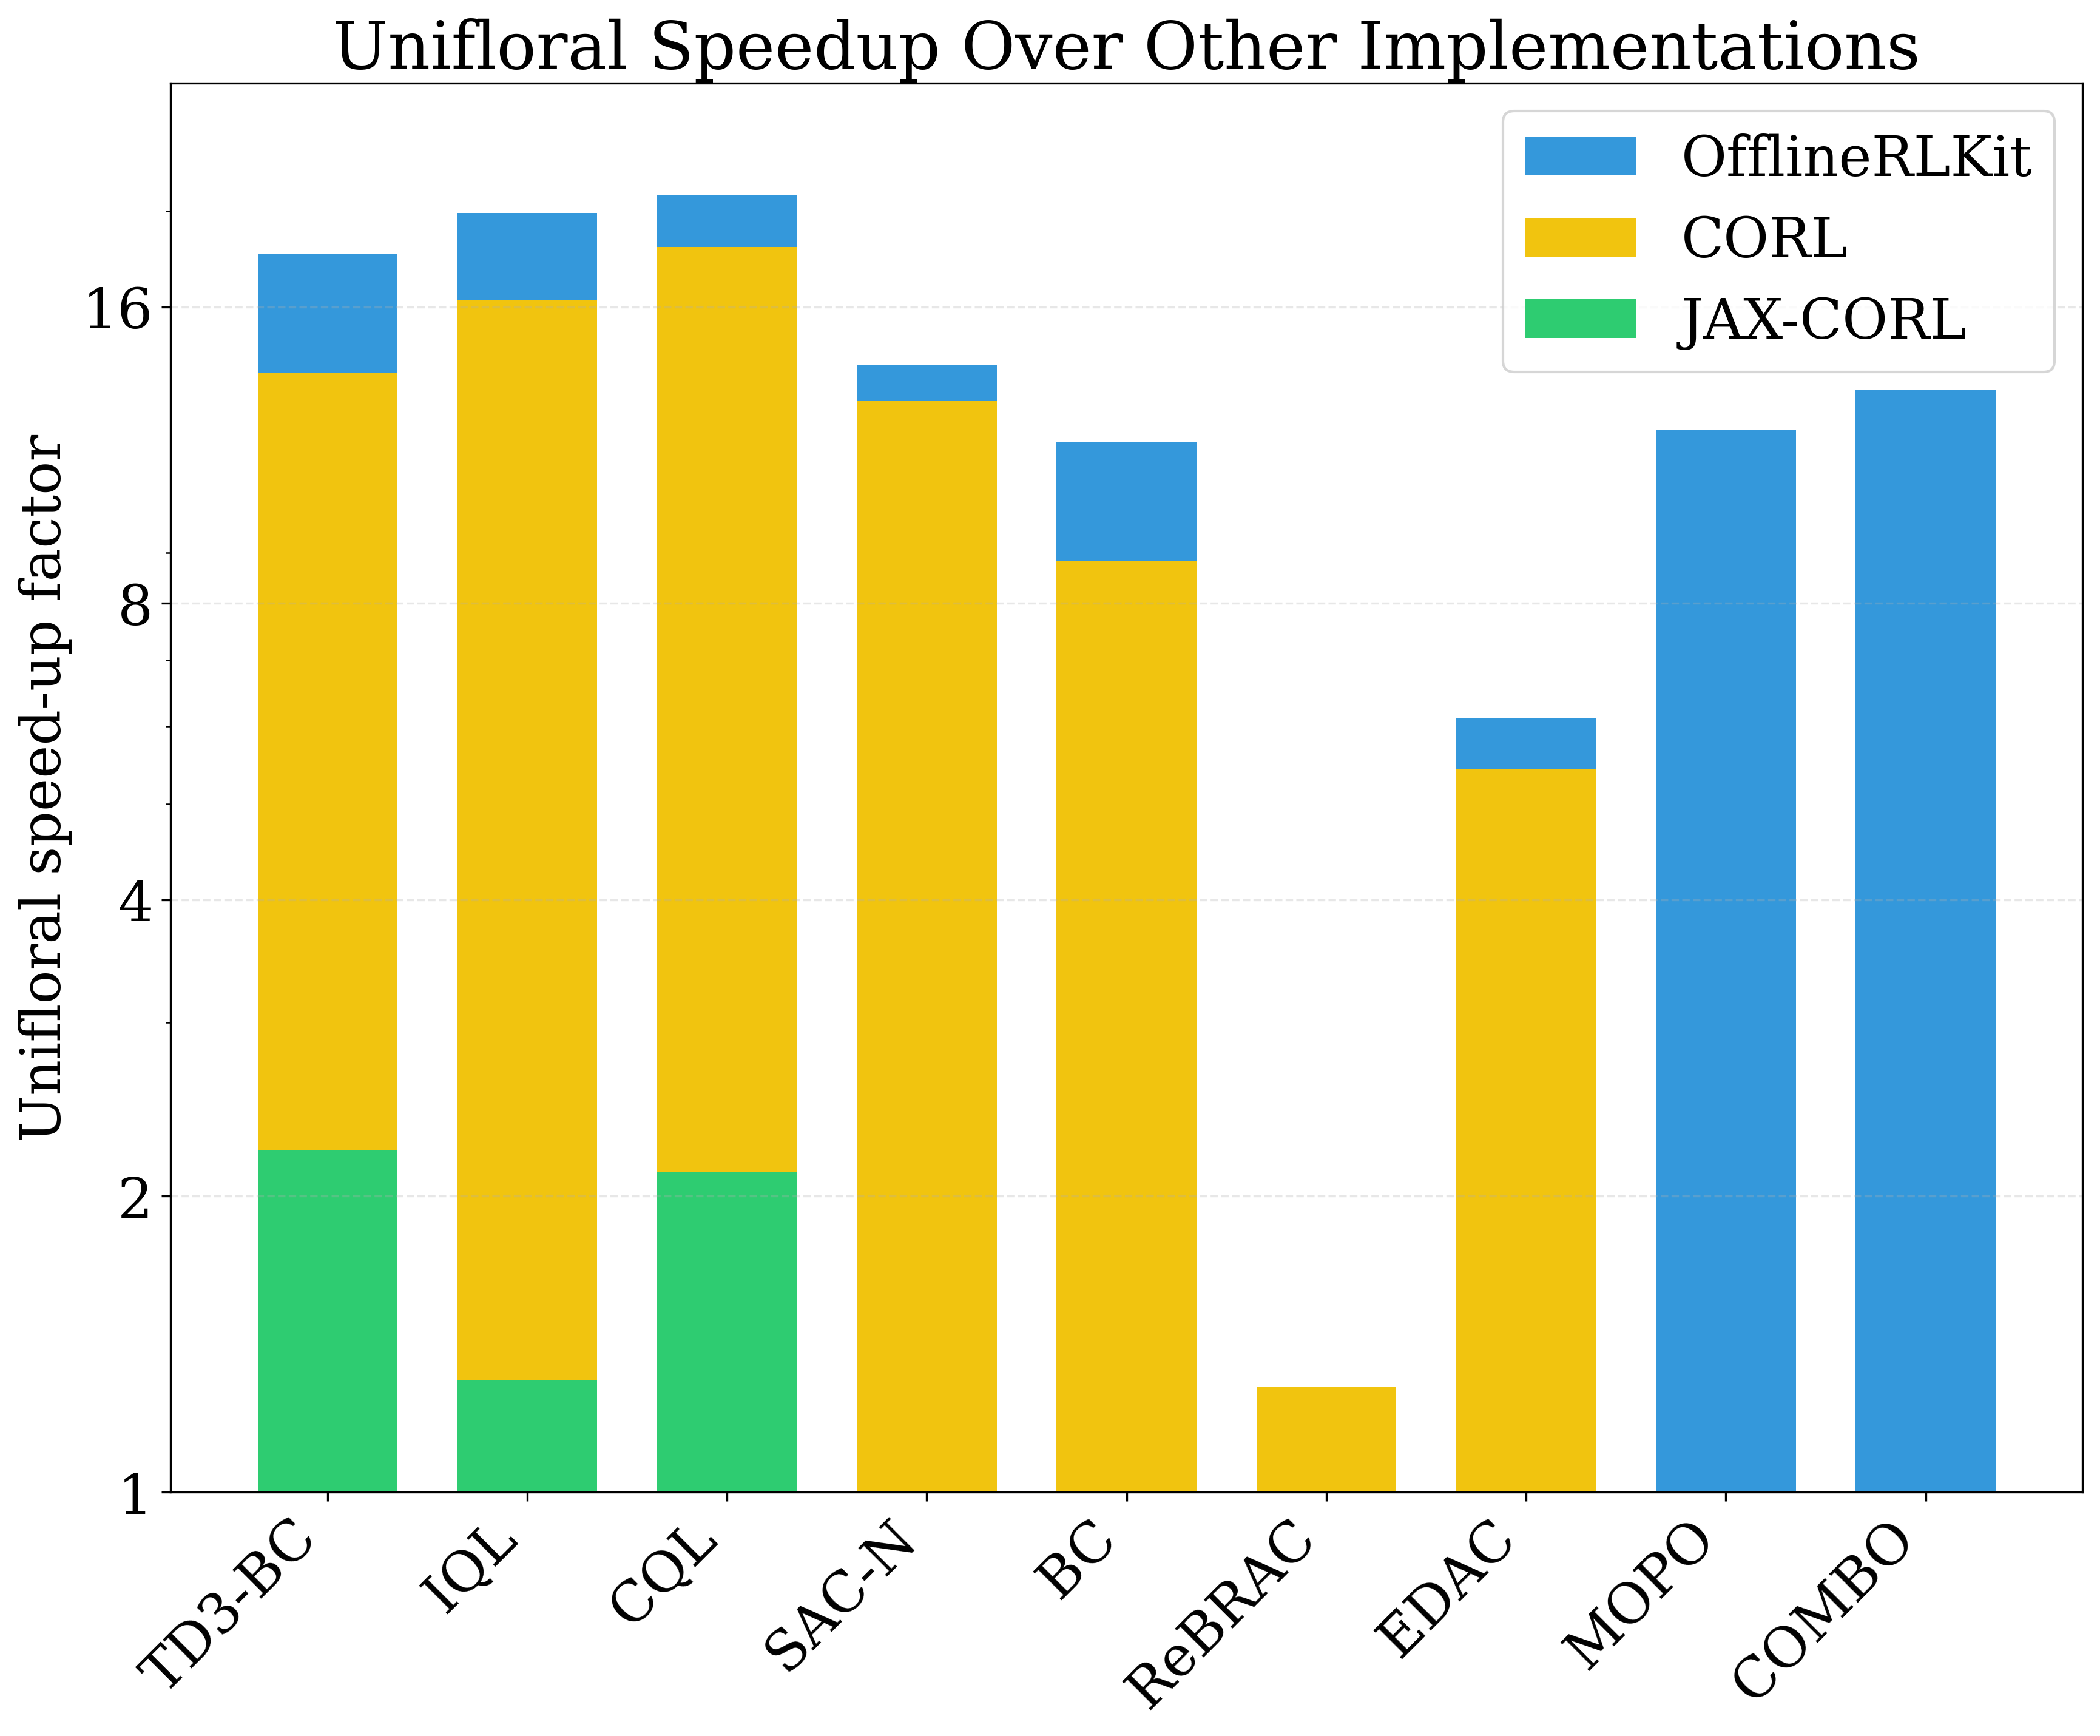
The researchers report that their simplified implementations were much faster than popular existing software libraries. Some algorithms trained dozens or even more than one hundred times faster.
Faster code matters because it allows researchers to:
- test more ideas,
- run more experiments,
- use less computing power, and
- more easily reproduce one another’s results.
5. Why is this research important?
This paper argues that offline RL needs more than new algorithms. It also needs fairer experiments, clearer rules, and simpler code.
The proposed evaluation system makes researchers state how much online testing they used. This is important because an algorithm that required thousands of real-world trials is not as practical as one that works after only a few trials.
The Unifloral framework may also change how researchers design algorithms. Instead of treating each algorithm as a completely separate invention, researchers can mix and test individual components. This is similar to testing different parts of a bicycle separately rather than replacing the entire bicycle every time.
The research could lead to:
- safer use of AI in robots, vehicles, and healthcare,
- more honest comparisons between algorithms,
- faster progress in offline RL,
- lower computing costs, and
- methods that work across a wider range of tasks.
Overall, the paper’s main message is that offline RL research should begin with a clean slate: clear definitions, controlled testing, transparent online costs, and simple implementations. The authors show that when these principles are followed, it becomes easier to understand what really works and to create stronger algorithms.
Knowledge Gaps
Knowledge gaps, limitations, and open questions
- The proposed taxonomy covers zero-shot offline RL, pre-deployment policy selection, post-deployment policy selection, and offline-to-online RL, but it does not establish which setting is most appropriate for specific real-world applications or how methods should be compared across settings.
- The evaluation protocol focuses exclusively on pre-deployment policy selection and therefore does not directly evaluate zero-shot deployment, post-deployment selection, iterative dataset aggregation, or offline-to-online fine-tuning.
- The protocol measures online tuning cost using the number of evaluation episodes, but does not account for other deployment costs such as safety constraints, failed episodes, latency, human supervision, data storage, or the unequal cost of different types of environment interaction.
- The use of a UCB bandit as the default tuning strategy leaves unresolved whether the reported conclusions depend on the choice of bandit algorithm; alternatives such as Thompson sampling, Bayesian optimization, successive halving, or risk-sensitive selection are not systematically compared.
- The study fixes the number of candidate policies at and trains policies per rollout, so the sensitivity of results to the number and diversity of candidate policies remains unknown.
- The protocol uses bootstrapped episodic scores collected from already trained policies, rather than conducting online tuning in the environment, leaving open whether the simulated bandit accurately captures nonstationarity, changing safety conditions, and operational constraints during real deployment.
- The assumption that a single episodic return is the feedback signal excludes settings with censored, delayed, partial, or safety-constrained feedback and does not examine how tuning should work when episodes have substantially different durations or costs.
- The evaluation reports the true average return of the selected policy after simulated tuning, which is unavailable to a real deployment system and may make the evaluation more favorable than practical policy selection.
- The paper does not provide theoretical guarantees for the proposed evaluation procedure, including the statistical reliability of the bootstrapped performance curves, confidence intervals, or comparisons between algorithms under finite online budgets.
- The “fixed hyperparameter range” definition of an offline RL method does not resolve how ranges should be selected without access to target-task performance; the study does not analyze the effect of range misspecification, overly broad ranges, or distribution shift between development and deployment tasks.
- The experimental conclusions are based primarily on nine D4RL environments, with substantial emphasis on MuJoCo, Adroit, kitchen, maze, and antmaze tasks; generalization to other domains such as robotics hardware, healthcare, recommendation, autonomous driving, or language-based control is not established.
- The paper does not evaluate partial observability, recurrent policies, non-Markovian observations, changing dynamics, stochastic rewards, or multi-agent environments, despite these being common in practical offline RL applications.
- The benchmark datasets and methods rely on fully observable states and, for model-based methods, access to hard-coded termination functions; the impact of removing this unrealistic termination-function access is not quantified.
- The model-based evaluation does not systematically examine how performance changes with transition-model misspecification, dataset coverage, stochasticity, horizon length, rollout length, ensemble size, or uncertainty-calibration quality.
- The poor performance of existing model-based methods on non-locomotion tasks is attributed partly to overfitting and limited prior evaluation, but the paper does not isolate whether the failures arise from model learning, uncertainty penalties, synthetic-rollout distribution shift, or policy optimization.
- Unifloral omits CQL from its unified design space because of its reported performance and complexity, leaving unresolved whether the framework can faithfully represent important algorithm families that require structurally different objectives.
- The unified hyperparameter space combines many components through weighted losses and selectable options, but the paper does not establish whether all included configurations are semantically valid, whether component interactions are identifiable, or whether the space contains degenerate configurations that artificially inflate search performance.
- The search procedure may give Unifloral-derived methods an advantage by allowing broader or more flexible hyperparameter ranges than individual baselines; the effect of equalizing search-space dimensionality and tuning budgets is not fully isolated.
- The reported improvements of TD3-AWR and MoBRAC are based on transferring hyperparameters from their source algorithms, but the contribution of the new component versus favorable inherited hyperparameter choices is not separated through matched ablations.
- TD3-AWR is evaluated against ReBRAC and IQL, but the paper does not test whether advantage-weighted regression improves other actor-critic algorithms or under which dataset properties the combination is beneficial.
- MoBRAC replaces the policy optimizer in a MOPO-style pipeline with ReBRAC, but the study does not determine whether its gains arise from the optimizer, the interaction between synthetic data and behavior regularization, or differences in tuning ranges.
- The paper does not provide comprehensive component-level ablations for Unifloral, TD3-AWR, or MoBRAC across all environments, making it difficult to identify which design choices are necessary, redundant, or harmful.
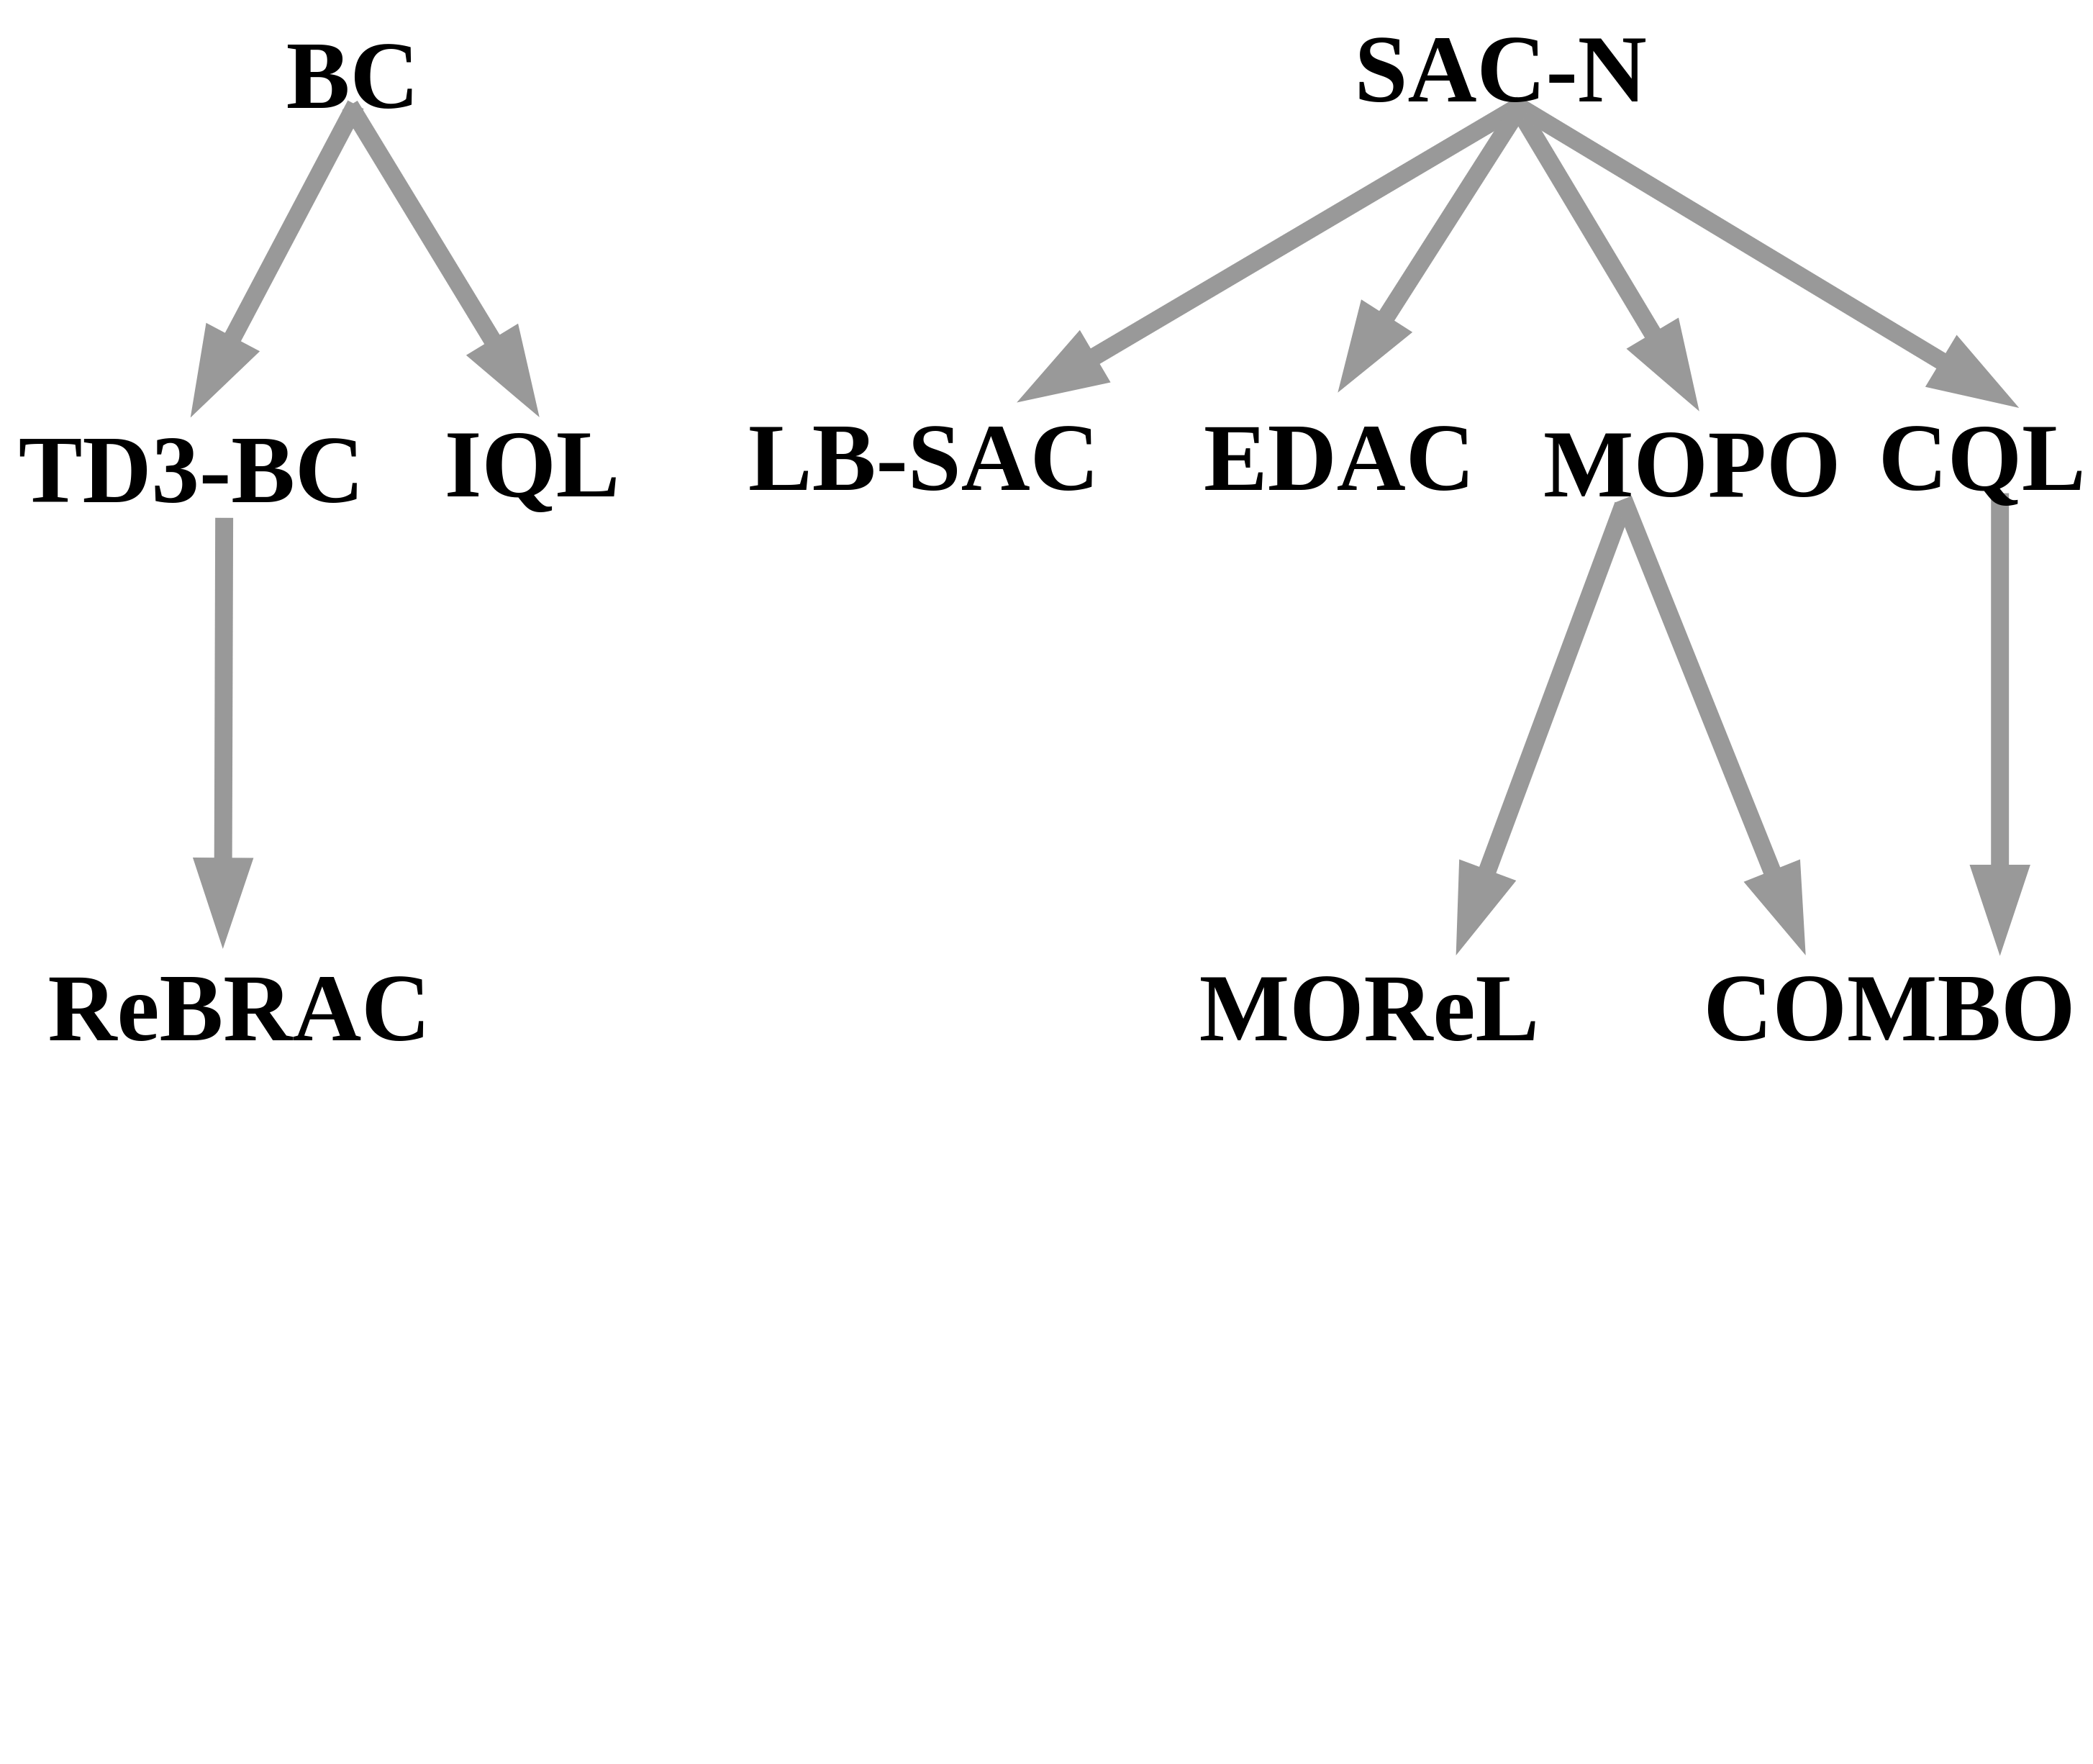
- The genealogy of algorithms is based primarily on compositional implementation structure and does not establish whether the proposed relationships correspond to theoretical equivalence, identical optimization objectives, or equivalent learned policies.
- The speed comparisons use different software libraries and hardware/compiler configurations, and the paper does not quantify the trade-off between training speed, memory consumption, compilation overhead, numerical precision, and final performance.
- Reimplementation correctness is asserted but the excerpt does not report detailed reproduction statistics, seed-by-seed discrepancies, sensitivity analyses, or independent third-party replication of the original algorithms.
- The experiments appear to rely on a limited number of random seeds and fixed implementation choices; the robustness of conclusions to initialization, network architecture, optimizer settings, normalization, and random dataset subsampling is not fully characterized.
- The study does not evaluate statistical significance under multiple comparisons across many algorithms, datasets, hyperparameter configurations, and online budgets, leaving uncertainty about the reliability of the reported rankings.
- The “distractor policy” phenomenon is identified descriptively, but its causes, prevalence across algorithms and datasets, relation to return variance or heavy-tailed outcomes, and optimal mitigation strategies remain unresolved.
- The evaluation protocol does not consider risk-sensitive objectives such as worst-case return, lower-tail performance, failure probability, or constraint violations, even though noisy episodic returns can make mean-return selection unsafe.
- The paper does not investigate offline policy-selection criteria that avoid online interaction, such as uncertainty estimates, off-policy evaluation, model-based evaluation, or calibrated pessimistic scores, beyond motivating the need for online tuning.
- The relationship between dataset coverage and the optimal amount of online hyperparameter tuning is not quantified; it remains unclear when zero-shot methods are sufficient and when online selection provides substantial value.
- The paper does not test whether performance curves remain stable under changes in the behavior-policy mixture, dataset size, trajectory quality, reward scaling, or artificially induced support gaps.
- The practical reproducibility of the proposed protocol is not fully established because the excerpt does not specify all random seeds, computational budgets, policy-training failures, discarded runs, and preprocessing choices needed to reproduce every result.
- The work does not address how offline RL evaluation should be standardized when the reward function is unknown, imperfectly specified, or learned from human feedback rather than directly available in the environment.
- No formal guidance is given for selecting the number of online episodes needed to distinguish policies with close expected returns, especially when return distributions are heteroscedastic or non-Gaussian.
- The paper leaves open whether a single unified implementation can remain maintainable and interpretable as additional algorithm families, discrete-action methods, diffusion policies, sequence models, and latent world models are incorporated.
Practical Applications
Immediate Applications
- Reproducible benchmarking for offline RL research — Academia and software
- Adopt the paper’s taxonomy to distinguish zero-shot offline RL, pre-deployment policy selection, post-deployment selection, and offline-to-online fine-tuning.
- Use the proposed evaluation protocol to report performance as a function of a fixed online interaction budget rather than presenting results after unspecified or unlimited tuning.
- Practical workflow: train policies from fixed hyperparameter ranges, evaluate them using noisy episodic returns, and use a UCB bandit to simulate deployment-time policy selection.
- Potential tools: benchmark dashboards, standardized experiment runners, dataset cards, and evaluation APIs based on the released Unifloral code.
- Dependencies: access to representative datasets and environments; agreement on fixed hyperparameter ranges, episode budgets, random seeds, and reporting standards.
- Fair comparison of offline RL algorithms — Academia, industrial R&D, and AI evaluation
- Replace comparisons based on results copied from prior publications with controlled reimplementations using the paper’s single-file implementations.
- Evaluate algorithms on diverse tasks, including locomotion, manipulation, kitchen tasks, and navigation, rather than relying only on MuJoCo benchmarks.
- Report both final policy quality and the number of online episodes required to identify a suitable policy.
- Practical benefit: organizations can determine whether an algorithm’s apparent advantage comes from its core method or from extensive environment-specific tuning.
- Dependencies: faithful implementation, consistent termination handling, and sufficiently broad datasets.
- Rapid offline RL prototyping and ablation — Software and machine-learning engineering
- Use Unifloral’s unified hyperparameter space to test combinations of critic objectives, behavior-cloning regularization, advantage weighting, entropy terms, critic ensembles, and model-based components without rewriting the training pipeline.
- This enables controlled experiments in which one component is changed while the rest of the implementation remains fixed.
- Potential products: configuration-driven RL experimentation platforms, automated ablation tools, and experiment registries for tracking algorithmic components.
- Dependencies: the unified parameterization must adequately represent the target algorithm; configurations still require careful validation and domain-specific tuning.
- Reduced-cost offline RL experimentation — Academia, startups, and engineering teams
- Deploy the JAX-based implementations for faster training and larger-scale hyperparameter studies on limited hardware.
- The reported speedups can reduce iteration time and make it practical to test more datasets, seeds, and ablations within a fixed compute budget.
- Potential workflow: use fast Unifloral runs for broad screening, then validate only the strongest configurations with more expensive simulation or hardware tests.
- Dependencies: compatible JAX/GPU infrastructure, correct porting of algorithms, and recognition that reported speedups may vary by hardware and workload.
- Safer policy selection before deployment — Robotics and autonomous systems
- Train several candidate policies entirely from historical logs, then use a limited number of real-world evaluation episodes to select among them.
- The bandit-based procedure can support applications such as warehouse robots, robotic manipulation, autonomous navigation, and industrial control where each trial is costly or risky.
- The explicit treatment of noisy episodic returns helps prevent selecting a policy based on a single unusually successful or unsuccessful trial.
- Dependencies: safe evaluation environments, emergency overrides, reliable reward definitions, and sufficient similarity between the offline dataset and deployment conditions.
- Offline policy learning from operational logs — Healthcare, energy, finance, and industrial control
- Apply conservative offline RL or TD3-AWR to historical trajectories where online experimentation is difficult:
- treatment or intervention sequencing in healthcare;
- battery charging and HVAC control in energy systems;
- inventory, bidding, or resource allocation in operations;
- recommendation or personalization policies using logged interactions;
- industrial process control using sensor and actuator histories.
- Advantage-weighted behavior regularization can preferentially imitate historically successful actions while limiting extrapolation beyond the dataset.
- Dependencies: high-quality trajectory logs, valid state representations, reliable reward or outcome definitions, adequate coverage of relevant actions, and domain-specific safety constraints. In healthcare and finance, offline performance is not sufficient for clinical or financial deployment without additional validation.
- TD3-AWR as a practical baseline — Robotics, control, and recommendation systems
- Use TD3-AWR as a candidate default for continuous-action offline RL, particularly when the dataset contains a mixture of poor and high-quality behavior.
- Its combination of TD3-style value optimization and advantage-weighted behavior cloning is intended to exploit high-value logged actions while maintaining regularization against unsupported actions.
- Potential products: offline policy training modules for robotic controllers, recommender-system ranking policies, and industrial process optimizers.
- Dependencies: continuous or suitably parameterized action spaces, reliable advantage estimates, appropriate clipping and regularization, and validation on the target domain. The paper’s evidence is benchmark-based and does not establish universal superiority.
- Detection of unstable or “distractor” policies — MLOps and safety engineering
- Inspect the full distribution of episodic returns for candidate policies instead of relying only on average performance.
- Flag policies with unusually high maximum returns but poor or highly variable typical performance, since a bandit may temporarily prefer them during limited evaluation.
- Potential workflow: maintain per-policy return histograms, confidence intervals, worst-case metrics, and risk-sensitive selection rules in a deployment gate.
- Dependencies: enough evaluation episodes to estimate variance; the paper shows the issue in benchmark environments, so the exact frequency and severity in production systems remain to be established.
- Transparent reporting for policy deployment — Industry and policy
- Require technical reports to disclose:
- offline dataset provenance and coverage;
- hyperparameter ranges;
- online tuning episodes;
- policy-selection procedures;
- evaluation variance and failure cases;
- whether post-deployment adaptation occurred.
- This can be incorporated into internal model-risk governance, procurement requirements, and audit documentation for autonomous decision systems.
- Dependencies: organizational adoption and domain-specific standards for what constitutes an acceptable interaction budget or safety threshold.
- Teaching and training in reinforcement learning — Education
- Use the clean implementations and taxonomy as instructional material for courses and workshops.
- Students can reproduce baseline algorithms, change one configuration component, measure the effect of online tuning budgets, and observe the distractor-policy phenomenon.
- Dependencies: maintained documentation, functioning environments, accessible compute, and correction of implementation or formatting issues in the released code and paper artifacts.
Long-Term Applications
- Safety-certified offline-to-online learning — Robotics, autonomous vehicles, and healthcare
- Extend the evaluation framework into deployment systems that gradually fine-tune policies while enforcing safety constraints, uncertainty thresholds, and rollback mechanisms.
- A future workflow could begin with zero-shot offline deployment, permit a tightly bounded number of online trials, and update the policy only when confidence and safety criteria are satisfied.
- Dependencies: reliable uncertainty estimation, formal or empirical safety guarantees, distribution-shift detection, safe exploration mechanisms, and regulatory approval. The current paper evaluates limited policy selection rather than full safety-certified adaptation.
- Model-based offline RL for complex real-world domains — Robotics, manufacturing, energy, and logistics
- MoBRAC suggests combining uncertainty-penalized learned dynamics with behavior-regularized policy optimization.
- A mature implementation could generate synthetic trajectories from a learned world model while reducing the influence of model regions that are poorly supported by historical data.
- Potential applications include predictive maintenance, robotic planning, supply-chain control, battery management, and process optimization.
- Dependencies: accurate dynamics and reward models, calibrated ensemble uncertainty, adequate dataset coverage, realistic termination modeling, and protection against compounding model errors. The paper notes that existing model-based methods perform poorly on several non-locomotion tasks.
- Automated algorithm discovery through unified search spaces — Academia and industrial AI platforms
- Use Unifloral as a foundation for automated search over combinations of actor objectives, critic losses, ensemble structures, dynamics models, and regularization strengths.
- Future systems could use Bayesian optimization, evolutionary search, or meta-learning to identify domain-specific algorithms while evaluating each candidate under a declared online budget.
- Potential tools: neural architecture and objective search platforms for RL, configuration-generated research papers, and automated ablation reports.
- Dependencies: enormous search spaces, risk of overfitting to benchmark suites, computational cost, and the need to distinguish genuinely general algorithms from configurations specialized to a dataset.
- Standardized offline RL certification and procurement benchmarks — Policy, safety regulation, and enterprise governance
- Develop sector-specific certification protocols based on the paper’s taxonomy and budgeted evaluation methodology.
- For example, a robotics vendor might be required to report zero-shot performance, performance after five safe evaluation episodes, worst-case return, and the number of policy-selection trials used.
- Similar standards could support public-sector procurement of adaptive traffic, energy, or healthcare systems.
- Dependencies: agreement on benchmark datasets, safety and fairness criteria, audit access, reproducibility requirements, and methods for testing policies under distribution shift.
- Risk-sensitive and fairness-aware policy selection — Finance, healthcare, public services, and recommender systems
- Extend the bandit evaluation procedure beyond expected return to optimize metrics such as worst-case performance, tail risk, calibration, subgroup equity, or constraint violations.
- This would reduce the chance that a policy with a high average reward but unacceptable behavior for vulnerable users is selected.
- Dependencies: reliable subgroup labels, sufficiently large evaluation samples, legally valid fairness criteria, multi-objective decision rules, and a reward function that reflects real societal costs.
- Offline RL for partially observed and nonstationary environments — Daily-life automation and intelligent infrastructure
- Generalize the methods beyond the paper’s fully observable, finite-horizon MDP assumptions to settings with hidden states, changing users, sensor noise, and evolving environments.
- Possible applications include adaptive educational tutors, home-energy assistants, personal health coaching, and smart-building control trained from historical usage data.
- Dependencies: partially observable modeling, continual dataset updates, privacy-preserving data collection, robust state estimation, and mechanisms for detecting when the learned policy is no longer valid.
- Privacy-preserving learning from sensitive behavioral logs — Healthcare, education, and consumer technology
- Combine offline RL with federated learning, differential privacy, or secure computation so organizations can learn policies from distributed records without centralizing raw trajectories.
- The paper’s reproducible evaluation framework could be adapted to compare privacy-utility trade-offs and deployment budgets.
- Dependencies: privacy mechanisms may reduce dataset coverage and policy quality; secure infrastructure, consent, governance, and domain-specific data protection requirements are necessary.
- Real-world digital twins and planning systems — Manufacturing, energy, and urban systems
- Integrate uncertainty-aware dynamics ensembles with digital twins to test candidate policies largely in simulation before limited physical deployment.
- MoBRAC-like optimization could provide a bridge between historical operational data, learned simulators, and controlled real-world trials.
- Dependencies: fidelity of the digital twin, calibrated uncertainty, accurate reward modeling, reliable simulator-to-real transfer, and explicit handling of rare catastrophic events.
- Personalized daily-life decision support — Education, health management, and assistive technology
- In the longer term, offline RL could learn personalized intervention schedules from longitudinal records, such as when to provide educational hints, reminders, exercise recommendations, or accessibility assistance.
- Advantage-weighted learning could favor interventions associated with positive outcomes while avoiding unsupported recommendations.
- Dependencies: causal interpretation of logged outcomes, consent, privacy, human oversight, protection against harmful recommendations, and careful separation between correlation and treatment effect. The paper’s benchmark results alone do not demonstrate readiness for such applications.
Glossary
- Advantage-weighted regression (AWR): A policy-learning method that weights behavior-cloning updates according to the estimated advantage of each action. “some methods use advantage weighted regularization (AWR)”
- Autoregressive transition model: A model that predicts a sequence of future states or transitions based on preceding states and actions. “an autoregressive transition model ”
- Behaviour cloning (BC): Imitation learning that trains a policy to reproduce actions observed in a dataset. “Their evaluation is limited to behavioural cloning~\citep[BC]{pomerleau1988alvinn}”
- Best-arm performance: The performance of the action or policy arm estimated to be best by a multi-armed bandit. “recording the best-arm performance of a UCB tuning bandit operating over them.”
- Bootstrapped estimate: An estimate obtained by repeatedly resampling observations or subsets of data. “We repeat this process times to obtain a bootstrapped estimate of algorithm performance.”
- Critic ensemble: A collection of critic networks whose predictions are combined to improve value estimation or quantify uncertainty. “the critic ensemble ”
- Critic objective: The loss or optimization target used to train a value-estimating critic in reinforcement learning. “The core contribution of offline RL research is often a novel critic objective”
- Critic diversity loss: A regularization term that encourages different critic networks to produce diverse estimates. “Finally, we add the critic diversity loss term from EDAC”
- Dataset aggregation: The process of combining data collected from multiple deployments or interaction rounds. “Examples include dataset aggregation from multiple deployments”
- Diffusion model: A generative model that learns to produce data by reversing a gradual noise-injection process. “generative models, such as diffusion, to directly model the joint transition distribution”
- Distractor policy: A policy with poor average performance but unusually high maximum performance that can mislead noisy policy selection. “We refer to these anomalous policies as distractor policies.”
- Dual optimization framework: A formulation that represents related learning methods using a shared optimization structure involving paired or complementary variables. “cast multiple offline RL methods in the same dual optimization framework”
- Episodic return: The cumulative reward received during one complete episode. “each pull from the bandit sampling a single episodic return from that policy's return distribution.”
- Expectile regression: An asymmetric regression technique that fits a value estimate using different penalties for overestimation and underestimation. “where is a value function trained with expectile regression”
- Exploratory behaviour: The tendency of a behavior policy to seek varied states or actions rather than repeatedly exploiting known actions. “Since may exhibit different degrees of expertise and exploratory behaviour”
- Finite-horizon Markov Decision Process: A sequential decision-making model in which episodes have a fixed maximum number of timesteps. “We apply RL to a finite-horizon Markov Decision Process (MDP)”
- Generative model: A model that learns a probability distribution from data and can generate new samples from it. “Recent work~\citep{lu2023synthetic,jackson2024policyguided} has shown an increased interest in using generative models”
- Hard-coded termination function: A manually specified rule that determines when an episode ends, rather than a learned or inferred termination mechanism. “have used hard-coded termination functions from the target environment.”
- Hyperparameter tuning budget: The permitted amount of environment interaction used to select or optimize hyperparameter settings. “Our goal is to evaluate offline RL algorithms under a fixed budget of pre-deployment environment interactions”
- Imitation learning: Learning a policy by reproducing behavior demonstrated in an existing dataset or by an expert. “A strong baseline for batch imitation learning”
- Indefinite number of online evaluations: An unspecified or potentially unlimited number of tests performed through interaction with the environment. “determined by an indefinite number of online evaluations.”
- Joint transition distribution: The probability distribution over a complete transition containing states, actions, and rewards. “directly model the joint transition distribution ”
- Latent dynamics model: A model that represents environment dynamics in a hidden learned representation rather than directly in the original state space. “recurrent latent dynamics models where the state representations component is separate from the state transition approximation”
- Markov Decision Process (MDP): A mathematical model of sequential decision-making in which the current state contains all information needed to predict future transitions and rewards. “defined by the tuple ”
- Model-based reinforcement learning: Reinforcement learning that uses a learned model of the environment to generate experience or plan actions. “In model-based offline RL, we learn a model of the target environment”
- Model-free reinforcement learning: Reinforcement learning that learns a policy or value function without explicitly learning an environment dynamics model. “a model-free approach (TD3-AWR, \autoref{sec:td3-awr})”
- Multi-armed bandit: A sequential decision problem in which an agent repeatedly chooses among alternatives and learns their rewards. “running a multi-armed bandit over them.”
- Offline-to-online reinforcement learning: A setting in which a policy is first trained offline and then refined through subsequent online interaction. “Offline-to-Online RL”
- Overestimation bias: Systematic inflation of estimated values, often caused by maximizing over noisy value estimates. “Typically, this requires significant regularization to avoid overestimation bias.”
- Pessimism coefficient: A parameter controlling the degree to which uncertain or poorly supported predictions reduce an estimated reward or value. “with a pessimism coefficient ”
- Phylogenetic tree: A tree-like representation of relationships among algorithms based on shared ancestry or compositional changes. “defining a phylogenetic tree based on their compositional structure”
- Policy optimization: The process of adjusting a policy to maximize its expected return under an environment or learned model. “for policy optimization.”
- Policy-selection bandit: A bandit algorithm that chooses among separately trained policies using their observed evaluation outcomes. “use a policy-selection bandit after offline training”
- Polyak averaging: A target-network update method that slowly blends current parameters with previous target parameters. “Polyak averaging step size.”
- Pooled or static dataset: A fixed collection of previously collected transitions used without additional environment interaction during training. “learning effective policies from pre-collected, static datasets”
- Pessimistic value learning: Value estimation that deliberately accounts for uncertainty by favoring conservative predictions. “regularized policy learning and pessimistic value learning.”
- Q-network ensemble: Multiple action-value networks whose outputs are aggregated to estimate values more robustly. “over the -network ensemble”
- Recurrent latent dynamics model: A sequential model that predicts environment evolution in a learned hidden state representation. “recurrent latent dynamics models where the state representations component is separate”
- Regularization: A constraint or penalty added during training to reduce overfitting or undesirable estimates. “Typically, this requires significant regularization”
- Residual state prediction: Predicting the change in state rather than the next state directly. “trained to predict the state residual ”
- Return distribution: The probability distribution of cumulative rewards produced by a policy across episodes. “that policy's return distribution.”
- Sample-limited setting: An environment in which only a small number of observations or interaction outcomes are available. “This models the high-variance, sample-limited setting typical in real deployments”
- Synthetic rollout: A simulated sequence of transitions generated by a learned environment model. “with synthetic rollouts generated from a MOPO world model.”
- Target policy: The policy whose actions or parameters are used as the reference for learning or evaluation. “the distance between the target policy and dataset action”
- Transition dynamics: The probabilistic rules specifying how states change after actions are taken. “ is the transition dynamics”
- Uncertainty quantification: The estimation of uncertainty in a model’s predictions, often using variation across model instances. “we quantify prediction uncertainty in the ensemble”
- Upper confidence bound (UCB): A bandit action-selection strategy that balances exploitation of high estimated rewards with exploration of uncertain alternatives. “we provide a upper confidence bound (UCB) bandit”
- Value function: A function estimating the expected cumulative reward from a state or state-action pair. “where is a value function trained with expectile regression”
- World model: A learned model that represents environment dynamics and often rewards, potentially in a latent space. “the term world model has been recently more associated with recurrent latent dynamics models”

