NCP-ArchPreview: Learning to Think in Concepts
This presentation introduces NCP-ArchPreview, an 8.94-billion-parameter language model that breaks from pure next-token prediction by learning to predict structured concept representations spanning multiple tokens. Trained on 5.73 trillion tokens, it reaches baseline performance using only half as many tokens, demonstrates stronger downstream results on mathematics and reasoning tasks, and opens a new pathway for efficient adaptation and faster inference through its learned latent space.Script
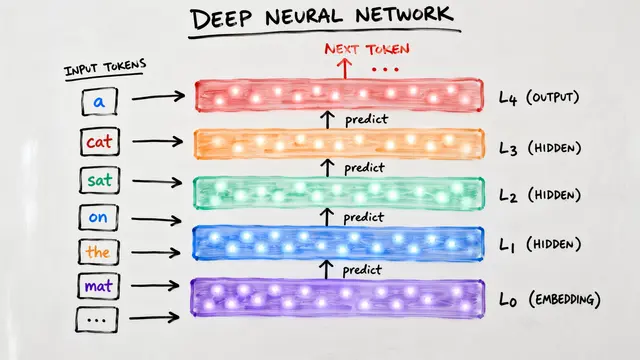
Language models have always predicted one token at a time, guided only by surface-level supervision. NCP-ArchPreview introduces a second prediction target: discrete concept representations that span multiple tokens, providing structure where standard models see only sequences.
The architecture splits token processing into a 16-layer encoder and a 16-layer decoder, with an 8-layer Concept Module operating on a sequence compressed by a factor of four. Predicted concepts are fed back into the token pathway, so both levels participate in generation.
The results are striking. NCP-ArchPreview reaches the OLMo 7B baseline's final loss after only 51.3 percent of the training tokens and finishes 0.091 lower, while improving downstream mathematics scores by nearly 6 points.
The learned concept space doubles as an adaptation interface. Freezing the backbone and updating only the concept codebooks achieves competitive task performance at twice the throughput of LoRA and one third the memory cost of full training.
Training exposed a numerical instability under Muon optimization when using layer-wise query-key normalization. Per-head normalization eliminates the attention logit explosions and gradient spikes, though the main experiments retain the layer-wise configuration to preserve direct comparison with the baseline.
NCP-ArchPreview demonstrates that language models can learn structured latent representations without abandoning token-level generation, opening questions about how much semantic structure remains hidden in today's models. Explore the full technical report and create your own video explainer at EmergentMind.com.