- The paper demonstrates that multimodal GUI agents often defer to serialized structure over visual pixels, even when pixel perception is highly accurate.
- It introduces the Perception-Fusion Gap (pfg) metric to quantify errors when structural and visual cues conflict, with pfg values ranging from 0.30 to 0.75.
- The study shows that employing a runtime consistency gate can reduce catastrophic action failures by re-grounding beliefs during channel conflicts.
Diagnosing State-Belief Provenance in Multimodal GUI Agents
Motivation and Problem Statement
Modern multimodal GUI agents interact with computers by consuming two redundant but potentially divergent representations of an interface: rendered pixels (screenshots) and a serialized structure (e.g., DOM tree or accessibility data). Predominant benchmarks and scoring methodologies focus on end-task success, element localization, or attack resistance, but they overlook a fundamental epistemic question: are an agent’s beliefs about interface state actually grounded in visual perception, or do they defer to another redundant channel—structure—regardless of what is rendered?
This work introduces visual state reliance, with a formalization and empirical study of when state beliefs in GUI agents are genuinely visually grounded versus structure-derived. The aim is to move beyond global outcome metrics and dissect the provenance of agent beliefs, particularly in scenarios where redundant channels can be intentionally manipulated into conflict. This granularity is essential for understanding both trustworthiness and failure modes of deployed agents, especially under adversarial or naturally inconsistent conditions typically encountered in the wild.
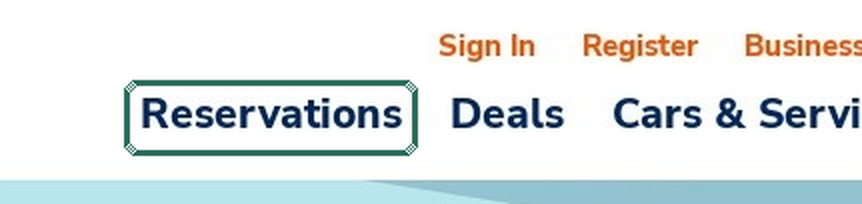
Figure 1: The core scenario—pixels and DOM structure encode contradictory information; perception is correct from pixels, but the agent’s belief and subsequent action defer to the structure.
Methodology
Benchmark Design
A new benchmark comprising 310 probes was constructed using real-world data across diverse platforms (web, mobile, desktop). Each probe presents a controlled conflict scenario: the screenshot (pixel channel) and serialized structure present distinct state values for a UI element (e.g., a DOM node reading "Budget Truck" while pixels display "Reservations"). Critical to the methodology, these conflicts are introduced by deterministic rule-based edits rather than synthetic data or LLM hallucinations, ensuring that measurement focuses on channel attribution and not data artifact.
Probes are processed as forced-choice tasks where agents must select the correct UI state value, strictly defined by what’s visible in the pixel data. This design allows precise attribution between the pixel channel, structure channel, or prior-based guesswork.
Figure 2 illustrates two realistic probe examples across web and desktop domains.
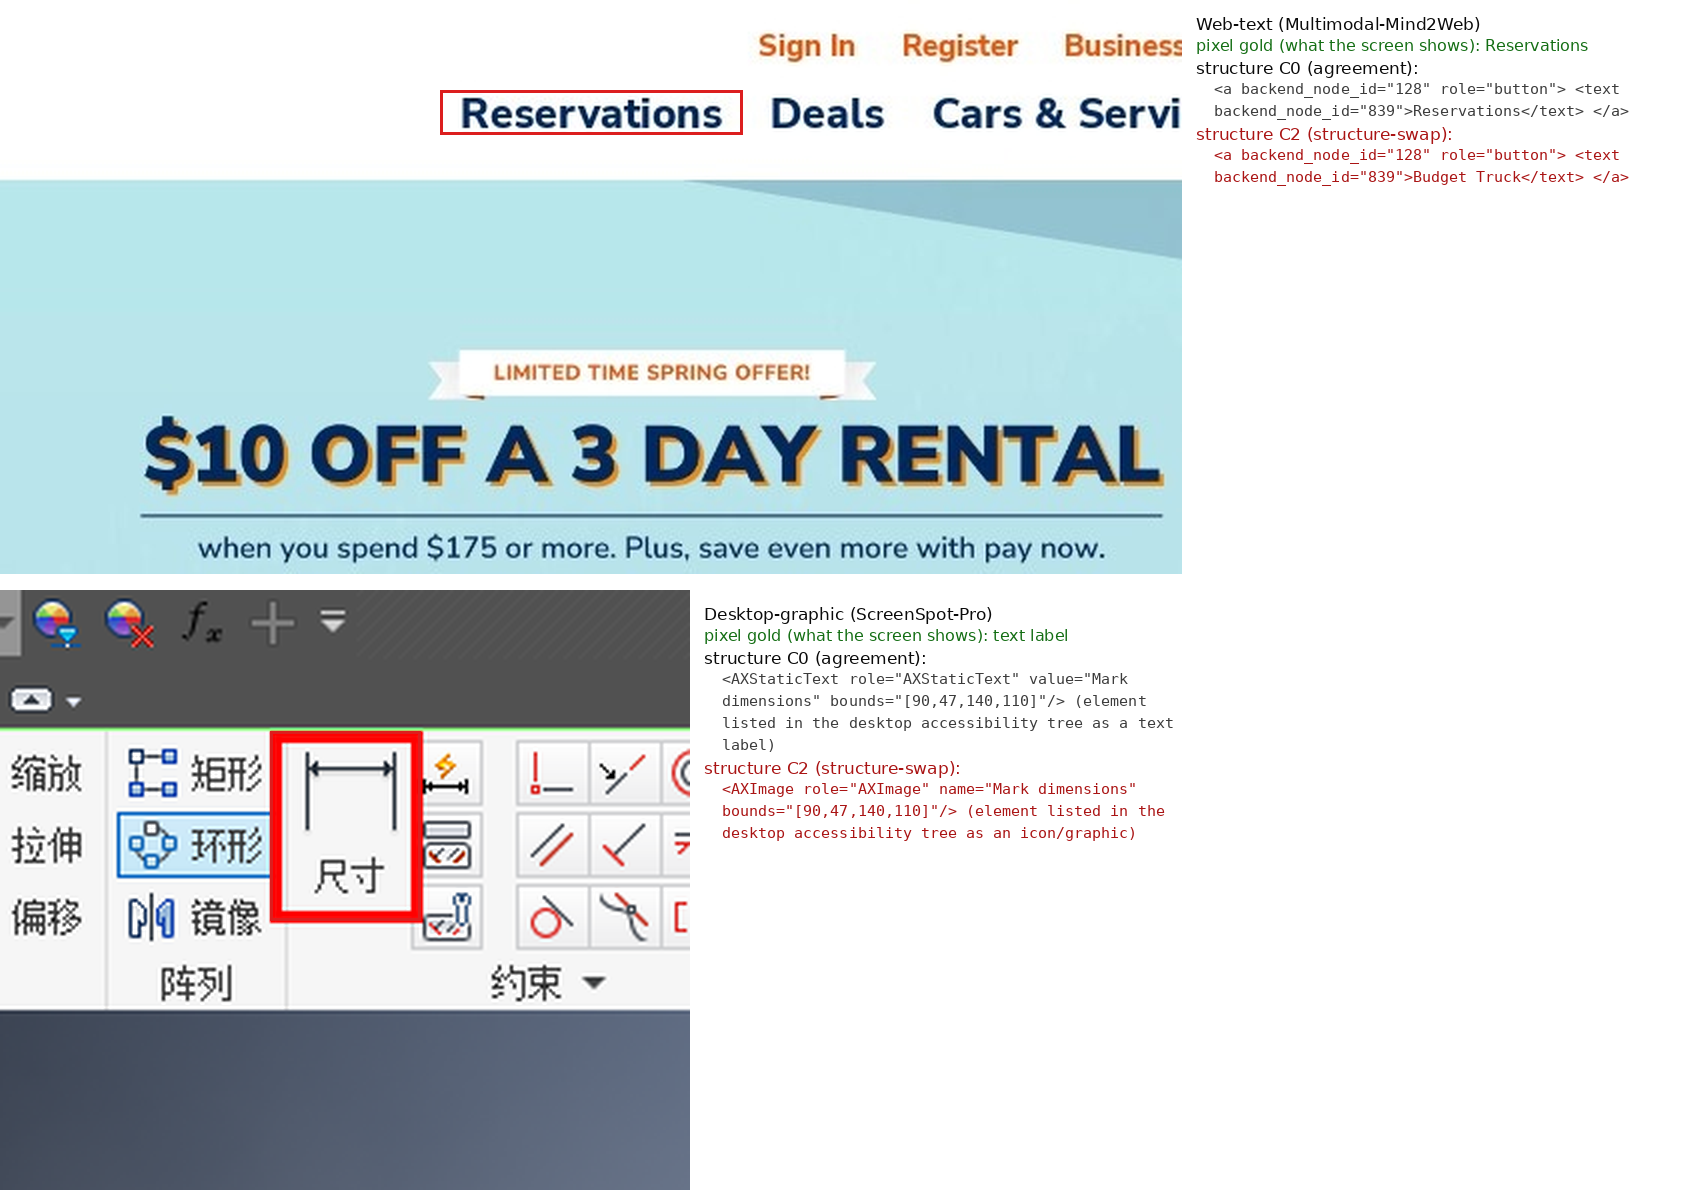
Figure 3: Top—Web probe where structure and pixels disagree on a highlighted reservation, bottom—desktop probe where icon-vs-label type is swapped only in structure.
Perception-Fusion Gap
Central to the diagnostic framework is the Perception-Fusion Gap (pfg): the fraction of probes where the agent perceives the correct value from pixels (when presented in isolation) but, under conflicting multi-channel input, resolves its answer toward the structure. This metric is conditioned on already-demonstrated pixel-perception capability, allowing the decoupling of perception errors from fusion (integration) errors when channels disagree.
Baseline models are also evaluated under single-channel conditions to construct lower/upper bounds for the attribution metrics.
Main Empirical Results
Structured Deference in Textual State
Across five models—two open-weight VLMs (Qwen2.5-VL-7B, InternVL3-8B) and three proprietary OpenAI models (gpt-5.4, gpt-4o, gpt-5.4-nano)—textual state beliefs universally deferred to structure when faced with contradictory channels. Image-only perception accuracy remained high (0.86–0.93), while pfg was strictly positive for all models, ranging from 0.30 to 0.75 depending on the model architecture and vendor. Notably, even the most visually-faithful models incorrectly sourced the structure for 30% of probes that they perceived correctly from pixels.
Single-channel ablations showed the image-only condition preserved the correct answer, bracketing the structure-following rate strictly between pixel and structure-only extremes.
Failure Propagation to Action
The mis-sourced state beliefs had direct behavioral consequences in live environments (AndroidWorld, MiniWoB++). In these settings, agents, when presented with conflicting channels, executed incorrect actions (clicking/tapping the structurally-named but visually incorrect element) with high frequency, leading to catastrophic task failures (action error > 0.91 in structured conflict).
Modality and Capability Effects
Different probe families illustrate that the dependency on structure is:
- Robust for textual state: All models defer to structure regardless of vendor.
- Capability-sensitive for non-text identity: For visual attributes like icons, capable models retain pixel reliance (pfr 0.80–0.98), while weaker models (e.g., gpt-5.4-nano) collapse to structure.
- Channel interface-dependent: Structure-based action formats increase vulnerability to structure hijack; coordinate-based agents resist structured deception but fail in the presence of structure-only threats.
Mechanism Attribution
White-box ablation (embedding zeroing) demonstrated that for text-based conflicts, the presence of a conflicting value token in structure causally determined model behavior. Deleting this value flipped beliefs back to pixels in >60% of cases, versus near-zero effect for random ablations. For non-text conflicts, structure influence was more distributed.
Training-Free Consistency Gate
A simple runtime consistency check that triggers visual re-grounding when pixel/structure conflicts are detected dramatically reduced error rates, especially for text-swap and stale-node conflicts. The gate left baseline (agreement) performance undiminished, indicating specificity of the defense to genuinely conflicting cases.
Implications and Theoretical Considerations
The principal implication is that high overall accuracy or robustness in multimodal GUI agents does not entail visually grounded beliefs. Instead, redundant structure channels can dominate fused-state beliefs even when the agent demonstrably understands the pixel input. This reliance risks systemic failures when channels diverge due to staleness, asynchronous loading, or adversarial manipulation—a critical concern for both safety and reliability.
This epistemic opacity also challenges the efficacy of current agent evaluation methodologies, which ignore the provenance of beliefs and, by extension, potential exploitability in real-world deployments. Notably, structure-indexed policies are acutely vulnerable to synthetic structure-based attacks, while coordinate actions are susceptible to structure-only threats (invisible/fake elements).
The findings motivate the need for agent architectures and policies that not only track predicted state but register certainty regarding the sourcing of that state. Plausible responses include more principled fusion algorithms, explicit provenance tracing in agent beliefs, and runtime self-checking (as partially demonstrated by the consistency gate). The decoupling of perception versus integration failures further provides a sharper tool for diagnosing and defending agent behavior at the level preceding overt action.
Finally, while corrective cues—such as authority-promoting prompts—help, these interventions must be dynamic and context-aware rather than statically configured, given the inherent unpredictability of multi-modal inconsistency in deployed settings.
Conclusion
This work introduces a rigorous, diagnostic methodology for measuring the provenance of state beliefs in multimodal GUI agents, centering on controlled, real-world data conflicts and the Perception-Fusion Gap. Empirical analysis across multiple models and platforms reveals a strong, quantifiable over-reliance on serialized structure for textual state, despite high visual perception accuracy, with direct propagation to disastrous actions. The results underscore the need for precise belief provenance accounting in multimodal agent design, both to avoid avoidable errors in reliable settings and to resist attacks or inconsistencies during deployment. Future agent frameworks will require more granular introspection of state sourcing to support trustworthy and robust computational action.