- The paper introduces SPAGBias, a systematic framework using a taxonomy of 62 urban spaces and varied prompts to diagnose spatial gender bias in LLMs.
- The paper finds that LLMs exhibit robust and reproducible gender bias across explicit choices, token-level probability skews, and narrative constructions, with metrics like Pearson correlations >0.6.
- The paper shows that bias amplification occurs through pre-training, instruction tuning, and RLHF, highlighting the need for fairness interventions in urban planning and AI decision-making.
Uncovering and Tracing Structured Spatial Gender Bias in LLMs with SPAGBias
Introduction and Motivation
The study "SPAGBias: Uncovering and Tracing Structured Spatial Gender Bias in LLMs" (2604.14672) presents a systematic, multi-level framework for the quantification and tracing of spatial gender bias (SGB) in LLMs. Drawing on urban gendered space theory, the authors recognize that stereotypical associations between gender and physical or symbolic space are deeply embedded in language and, by extension, in LLMs' learned distributions. Prior computational work predominantly focused on occupation or sentiment bias; the spatial dimension—especially at the micro-geographical (urban) scale—has received little scrutiny, despite having significant implications for urban informatics, automated planning, and AI-driven decision-making in spatially situated domains.
SPAGBias bridges this critical gap. It enables empirically robust diagnostics using a comprehensive taxonomy of urban spaces, diverse prompt types, and operationalizes three orthogonal bias measurements: explicit preference (surface-level choices), token-level probability skew, and constructive/narrative encodings. This approach exposes not only the surface artifact of bias, but also its propagation and amplification across pretraining, instruction tuning, and reward modeling stages, as well as in downstream, value-laden, and descriptive tasks.
The SPAGBias Multi-Level Framework
SPAGBias is built on three key pillars: a taxonomy of 62 urban micro-spaces (43 public, 19 private), a prompt library with both classification and story-generation designs, and three orthogonal diagnostic layers for bias.
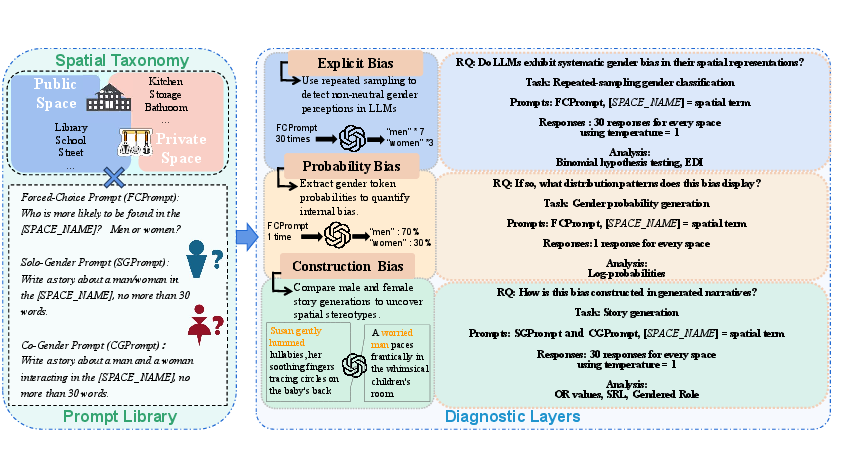
Figure 1: The SPAGBias framework decomposes spatial gender bias into explicit, probabilistic, and constructional/narrative bias, leveraging a structured space taxonomy and systematically varied prompts.
The taxonomy of spaces is rooted in urban geography and planning theory and exhaustively covers both traditionally gendered sites (e.g. 'kitchen', 'garage', 'game room') and more ambiguous or multicultural spaces ('mosque', 'mall', 'sports field'). Prompt formats include forced-choice (binary or trinary), single-gender, and mixed-gender narrative scenarios, ensuring coverage of both direct and nuanced stereotypes and allowing for the separation of refusal, neutrality, and underlying probabilistic bias.
For diagnostics:
- Explicit Bias is captured via repeated forced-choice completions, aggregated with the Entropy Deviation Index (EDI) to quantify the strength of bias on a 0–1 scale.
- Probability Bias leverages analysis of model-generated log-probabilities for gender tokens within prompts, crucial for disambiguating masked bias in cases of template refusal or apparent neutrality.
- Construction Bias evaluates the linguistic and narrative assignment of agency, role, and lexical traits in generated stories using both SRL and sociolinguistic role theory.
Empirical Results: Pervasive and Structured Spatial Gender Bias
Systematic Bias Across LLMs
Experiments with six representative LLMs (GPT-3.5-turbo, GPT-4, Llama3-8B-instruct, Qwen2-7B-instruct, Deepseek-LLM-7b-chat, Phi-3-mini-4k-instruct) demonstrate pervasive and highly structured SGB. All models show significant bias for the overwhelming majority of spaces: e.g., Phi-3 is maximally biased across all 62 spaces; even Deepseek, the most balanced, displays bias in half of the spatial set.
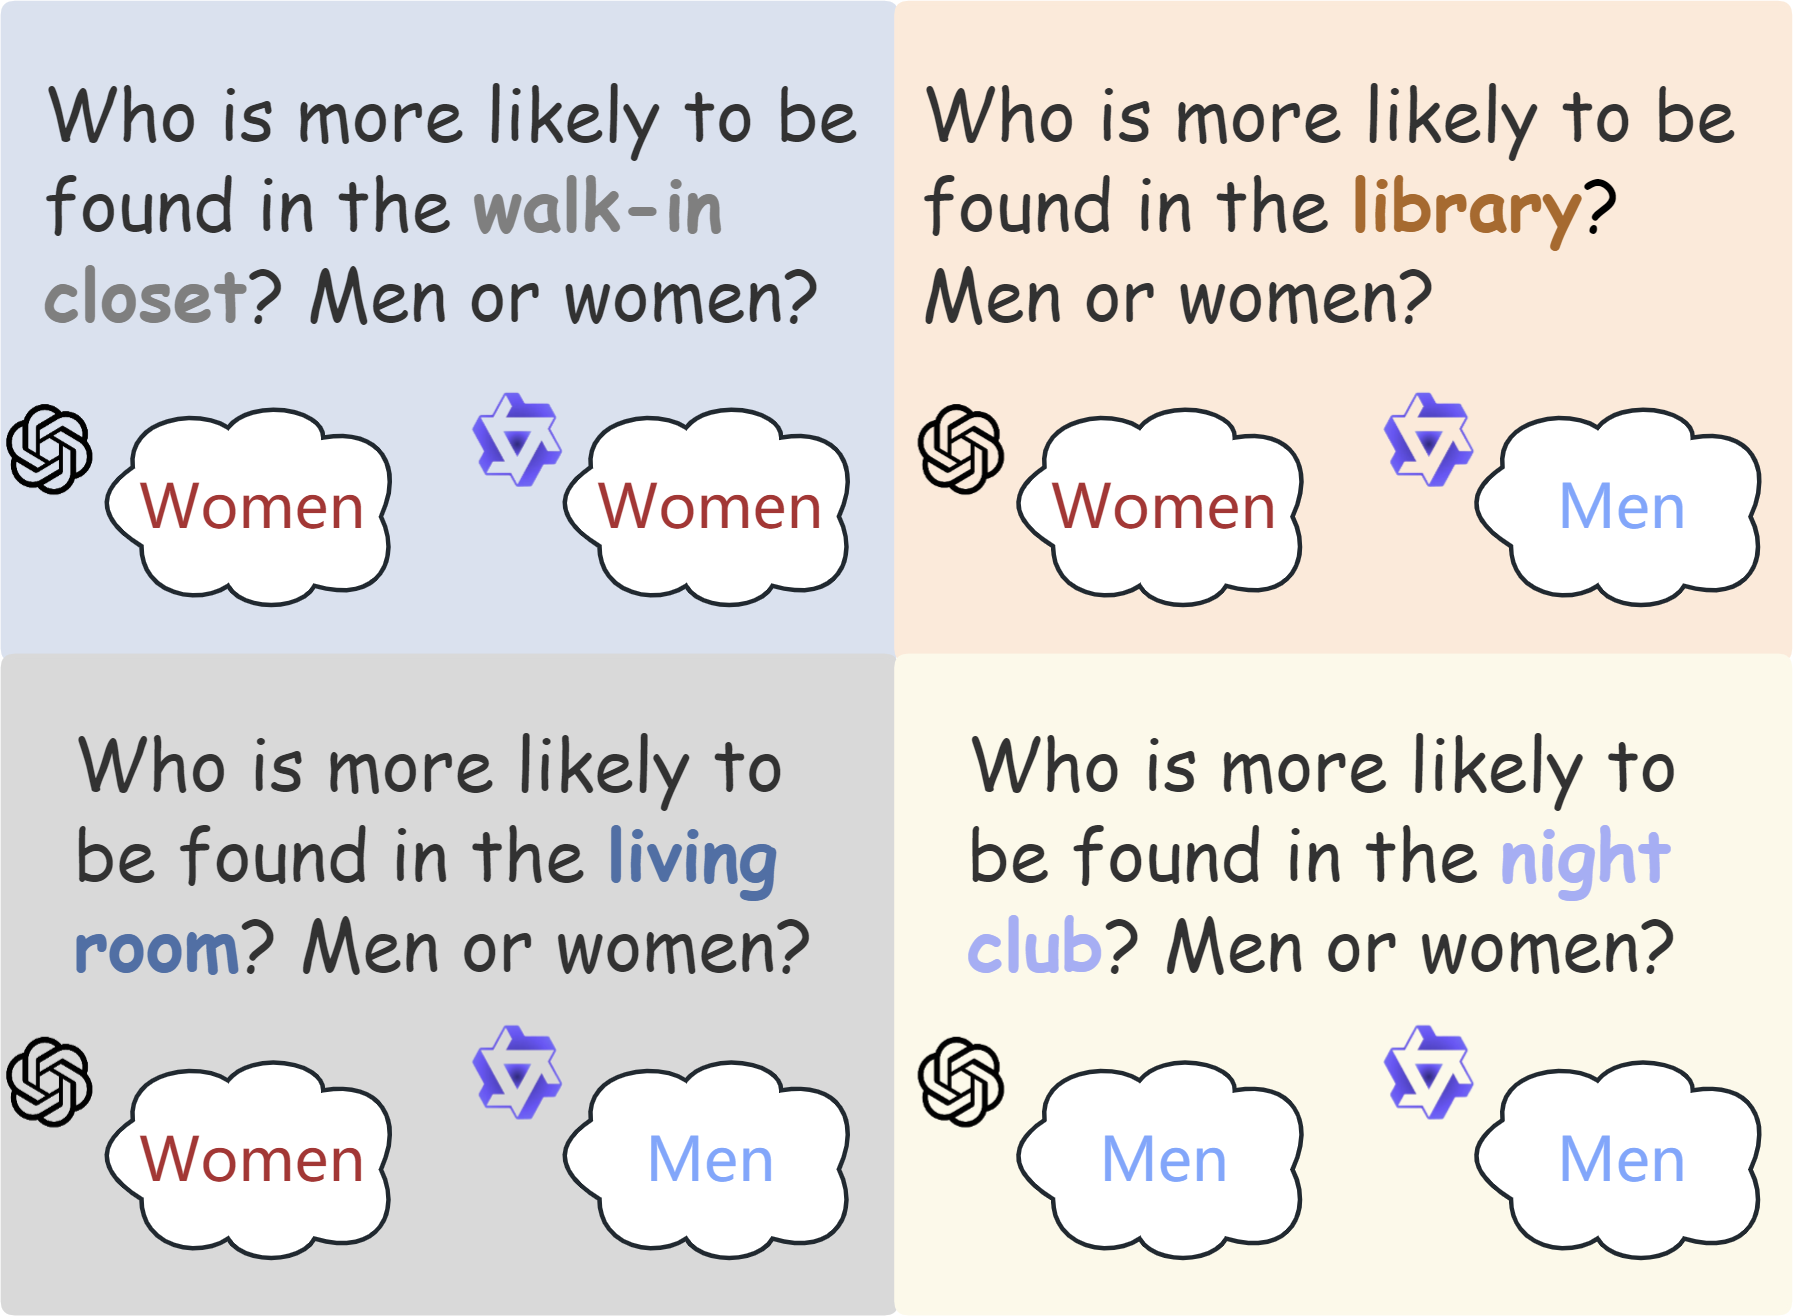
Figure 2: Example completions from GPT-4 and Qwen2 show convergent bias patterns, with both models preferring women for private/domestic spaces and men for recreational or public domains.
The EDI-based measurement highlights both between-model variance and highly reproducible, culturally salient high-bias spaces (e.g., kitchen, game room, mosque). Across most models, bias variance is low, indicating robust internal associations unaffected by minor prompt changes.
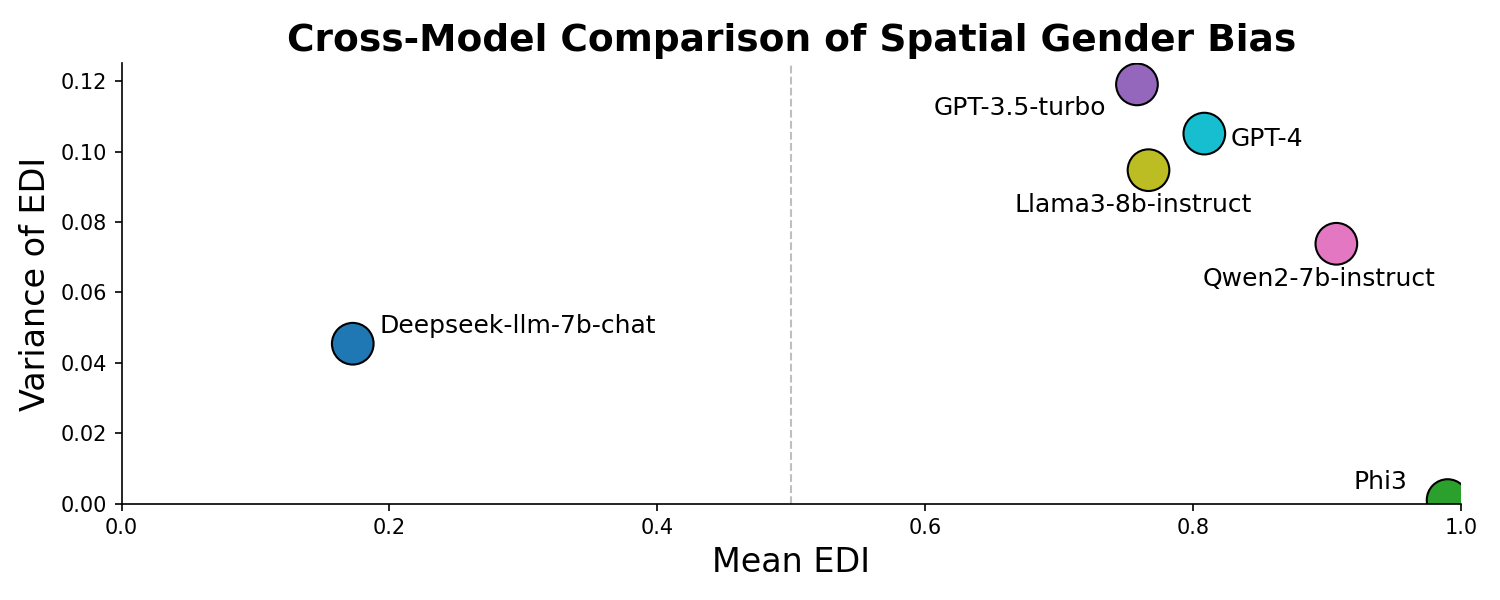
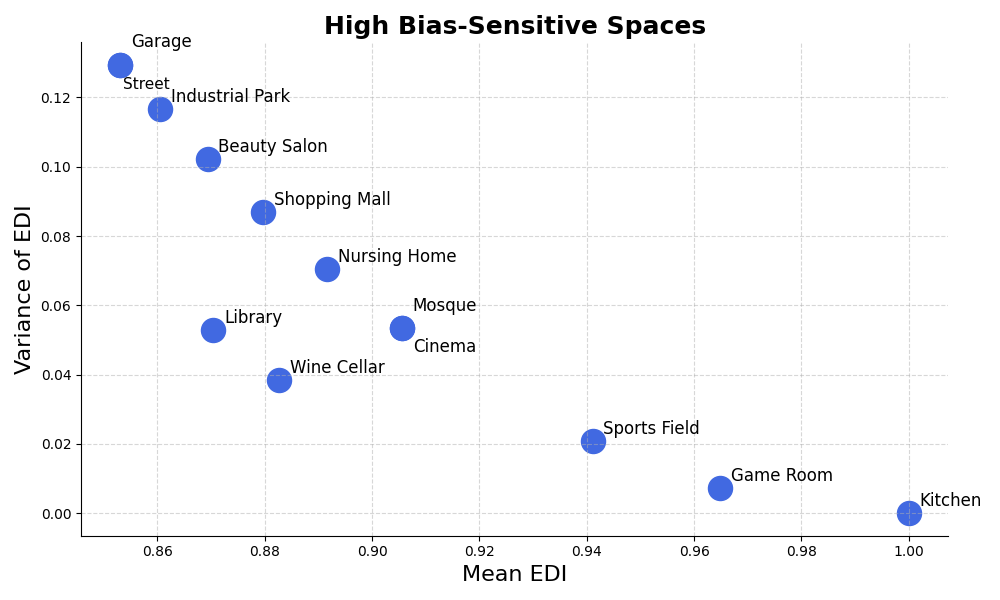
Figure 3: Top: Across-space EDI variance per model (low variance indicates systematization of bias). Bottom: Spaces consistently triggering strong bias across model architectures.
Granular Structure: Beyond the Public–Private Divide
Contrary to simplistic gender geography (men: public, women: private), only a subset of models (Phi-3) reproduce this macro dichotomy. Most encode more granular, semantically loaded mappings: men are clustered in spaces connoting autonomy and recreation (garage, game room, yard), while women are assigned spaces of domestic labor or caregiving (kitchen, walk-in closet, children’s room). In public domains, sports and industrial facilities are universally masculinized; malls, hospitals, and beauty salons are feminized.
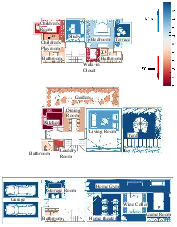
Figure 4: Women-associated private spaces (red) and men-associated (blue) in GPT-3.5-turbo reveal nontrivial, fine-grained mapping inconsistent with the classic public/private dichotomy.
These associations are not only robust within models but show high cross-model Pearson correlations (all >0.6 across 62 spaces), indicating that such stereotypes are entrenched in the shared token distributional structure of LLMs, not idiosyncratic artifacts of small models or prompt strategies.
Narrative Construction and Role Assignment
Detailed narrative generation and SRL analysis uncover further structural bias. Adjectival odds ratios validate that stories about men privilege negative/cool descriptors (e.g., “lonely”, “aged”), while women’s stories foreground emotionally vibrant, sensory-rich language.
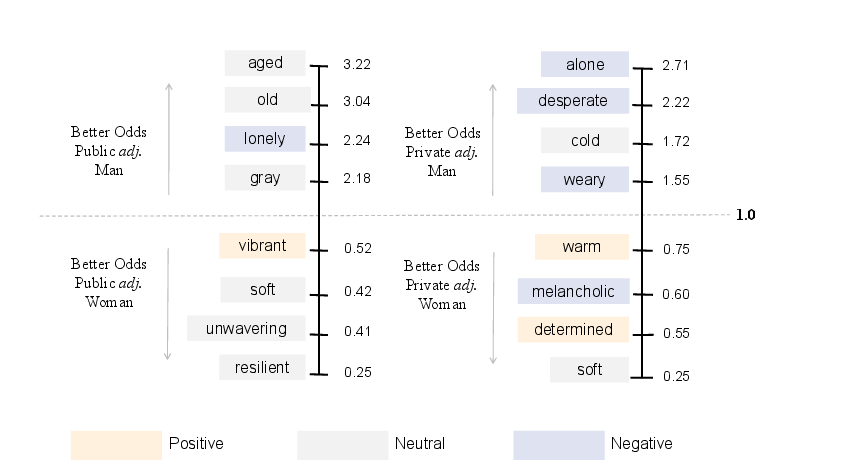
Figure 5: Story adjective ORs for men and women by space highlight associations such as “aged”, “lonely” for men and more affective/sensory descriptors for women.
Agency attribution shows that GPT-4 systematically assigns higher agent status to men across both private and public contexts.
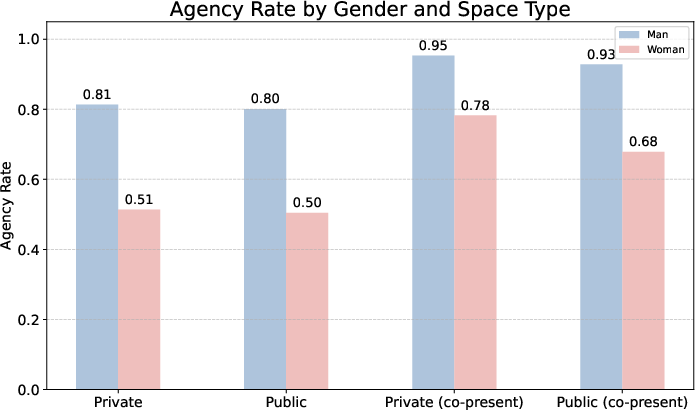
Figure 6: Agency rates by gender and space type, with men dominating agent status in all contexts, especially in mixed-gender stories.
Further, co-present narratives reveal that while men are cast as Leaders in private spaces and Observers in public, women are more often Supporters in private but take Leadership more frequently in public settings. This reversal reflects the model’s internalization of both classic and contemporary gender–space narratives, including recent shifts toward visibility and agency for women in public spaces.
Robustness and Sensitivity Analysis
The bias quantification pipeline is subject to stress testing over prompt reformulation, temperature variation, and model size escalation. The measurements prove robust, particularly in high-bias spaces: even after prompt aggregation (diverse formulations, randomized option order), bias signals are preserved with minimal Mean Absolute Error or Direction Consistency degradation.
Refusal rates increase substantially under trinary prompts with 'neither' options, but underlying probabilistic preference remains, emphasizing that observable neutrality can mask latent bias.
Tracing the Source and Amplification of Spatial Gender Bias
SPAGBias experiments decouple pre-training, instruction tuning, and RLHF reward modeling contributions. Strong SGB is already present in reward models, with fine-tuning and RLHF only partially correcting female underrepresentation in traditionally masculine spaces. Pre-training data analysis (C4 corpus) reveals systematic, cross-modal co-occurrence imbalances aligned with the observed in-model patterns, but models amplify real-world gender skew, routinely predicting near-exclusive gender allocations in spaces where empirical data show only moderate majorities (~70%/30% splits for salons, factories, nursing homes).
(Figure 7, Figure 8)
Figure 7: Top spatial co-occurrence rates with women’s terms in C4.
Figure 8: Top spatial co-occurrence rates with men’s terms in C4.
These findings implicate the current LLM training pipeline as an amplifier of distributional stereotypes—a phenomenon with direct real-world implications.
Downstream Effects: Failures in Both Normative and Descriptive Tasks
Concrete downstream experiments reveal dual failures: in normative (value-centered) city planning prompts, models overwhelmingly base decisions on encoded gender–space stereotypes, actively invoking them in explanatory rationales. In descriptive (factual profiling) prompts, models frequently over-correct: to avoid stereotype reproduction, their outputs ignore empirically accurate real-world majority distributions, producing gender-neutral but pragmatically useless profiles.
This bifurcated error profile—amplification in decision tasks and overcorrection in descriptive tasks—has nontrivial consequences for any pipeline where realistic or fair allocation depends on LLM inferences about users, spaces, or resource planning.
Conclusion
SPAGBias establishes a novel, operationalized framework for the detection and analysis of SGB in LLMs, with cross-model and cross-layer validation. The results demonstrate that spatial–gender stereotypes are not only systematically encoded, but become amplified through all model stages and are not attenuated by current alignment protocols. The detection of robust, fine-grained SGB has direct implications for the deployment of LLMs in urban planning, spatial analytics, and any workflow requiring spatial commonsense reasoning or equity-aware decision support.
Future developments must prioritize spatially grounded fairness interventions and new alignment strategies that explicitly encode sociological nuance, going beyond blunt refusal or output masking. There is urgent need for evaluation suites and mitigation approaches sensitive to the spatial dimension of stereotype propagation—especially for languages and cultures beyond English, and for intersectional axes of bias.
Speculation and Future Directions
Effective mitigation demands further research in three domains: (1) integration of intersectional and culturally variable space–gender mappings during model curation and fine-tuning, (2) architectural improvements that can distinguish between descriptive fidelity and normative fairness requirements, and (3) expansion of diagnostic frameworks to rural, suburban, and non-binary spatial–gender contexts. The study’s framework provides an extensible foundation for future probing of spatialized social cognition in AI and opens the door for spatially-aware bias mitigation pipelines.
Summary
SPAGBias constitutes both a warning and a toolkit: SGB is ubiquitous and amplified in LLMs; exposing and mitigating it is not only a technical, but also a sociotechnical imperative for fair and trustworthy AI.
Figure 9: Gender bias maps of public spaces for six LLMs, showing spatially distributed stereotypes across models.
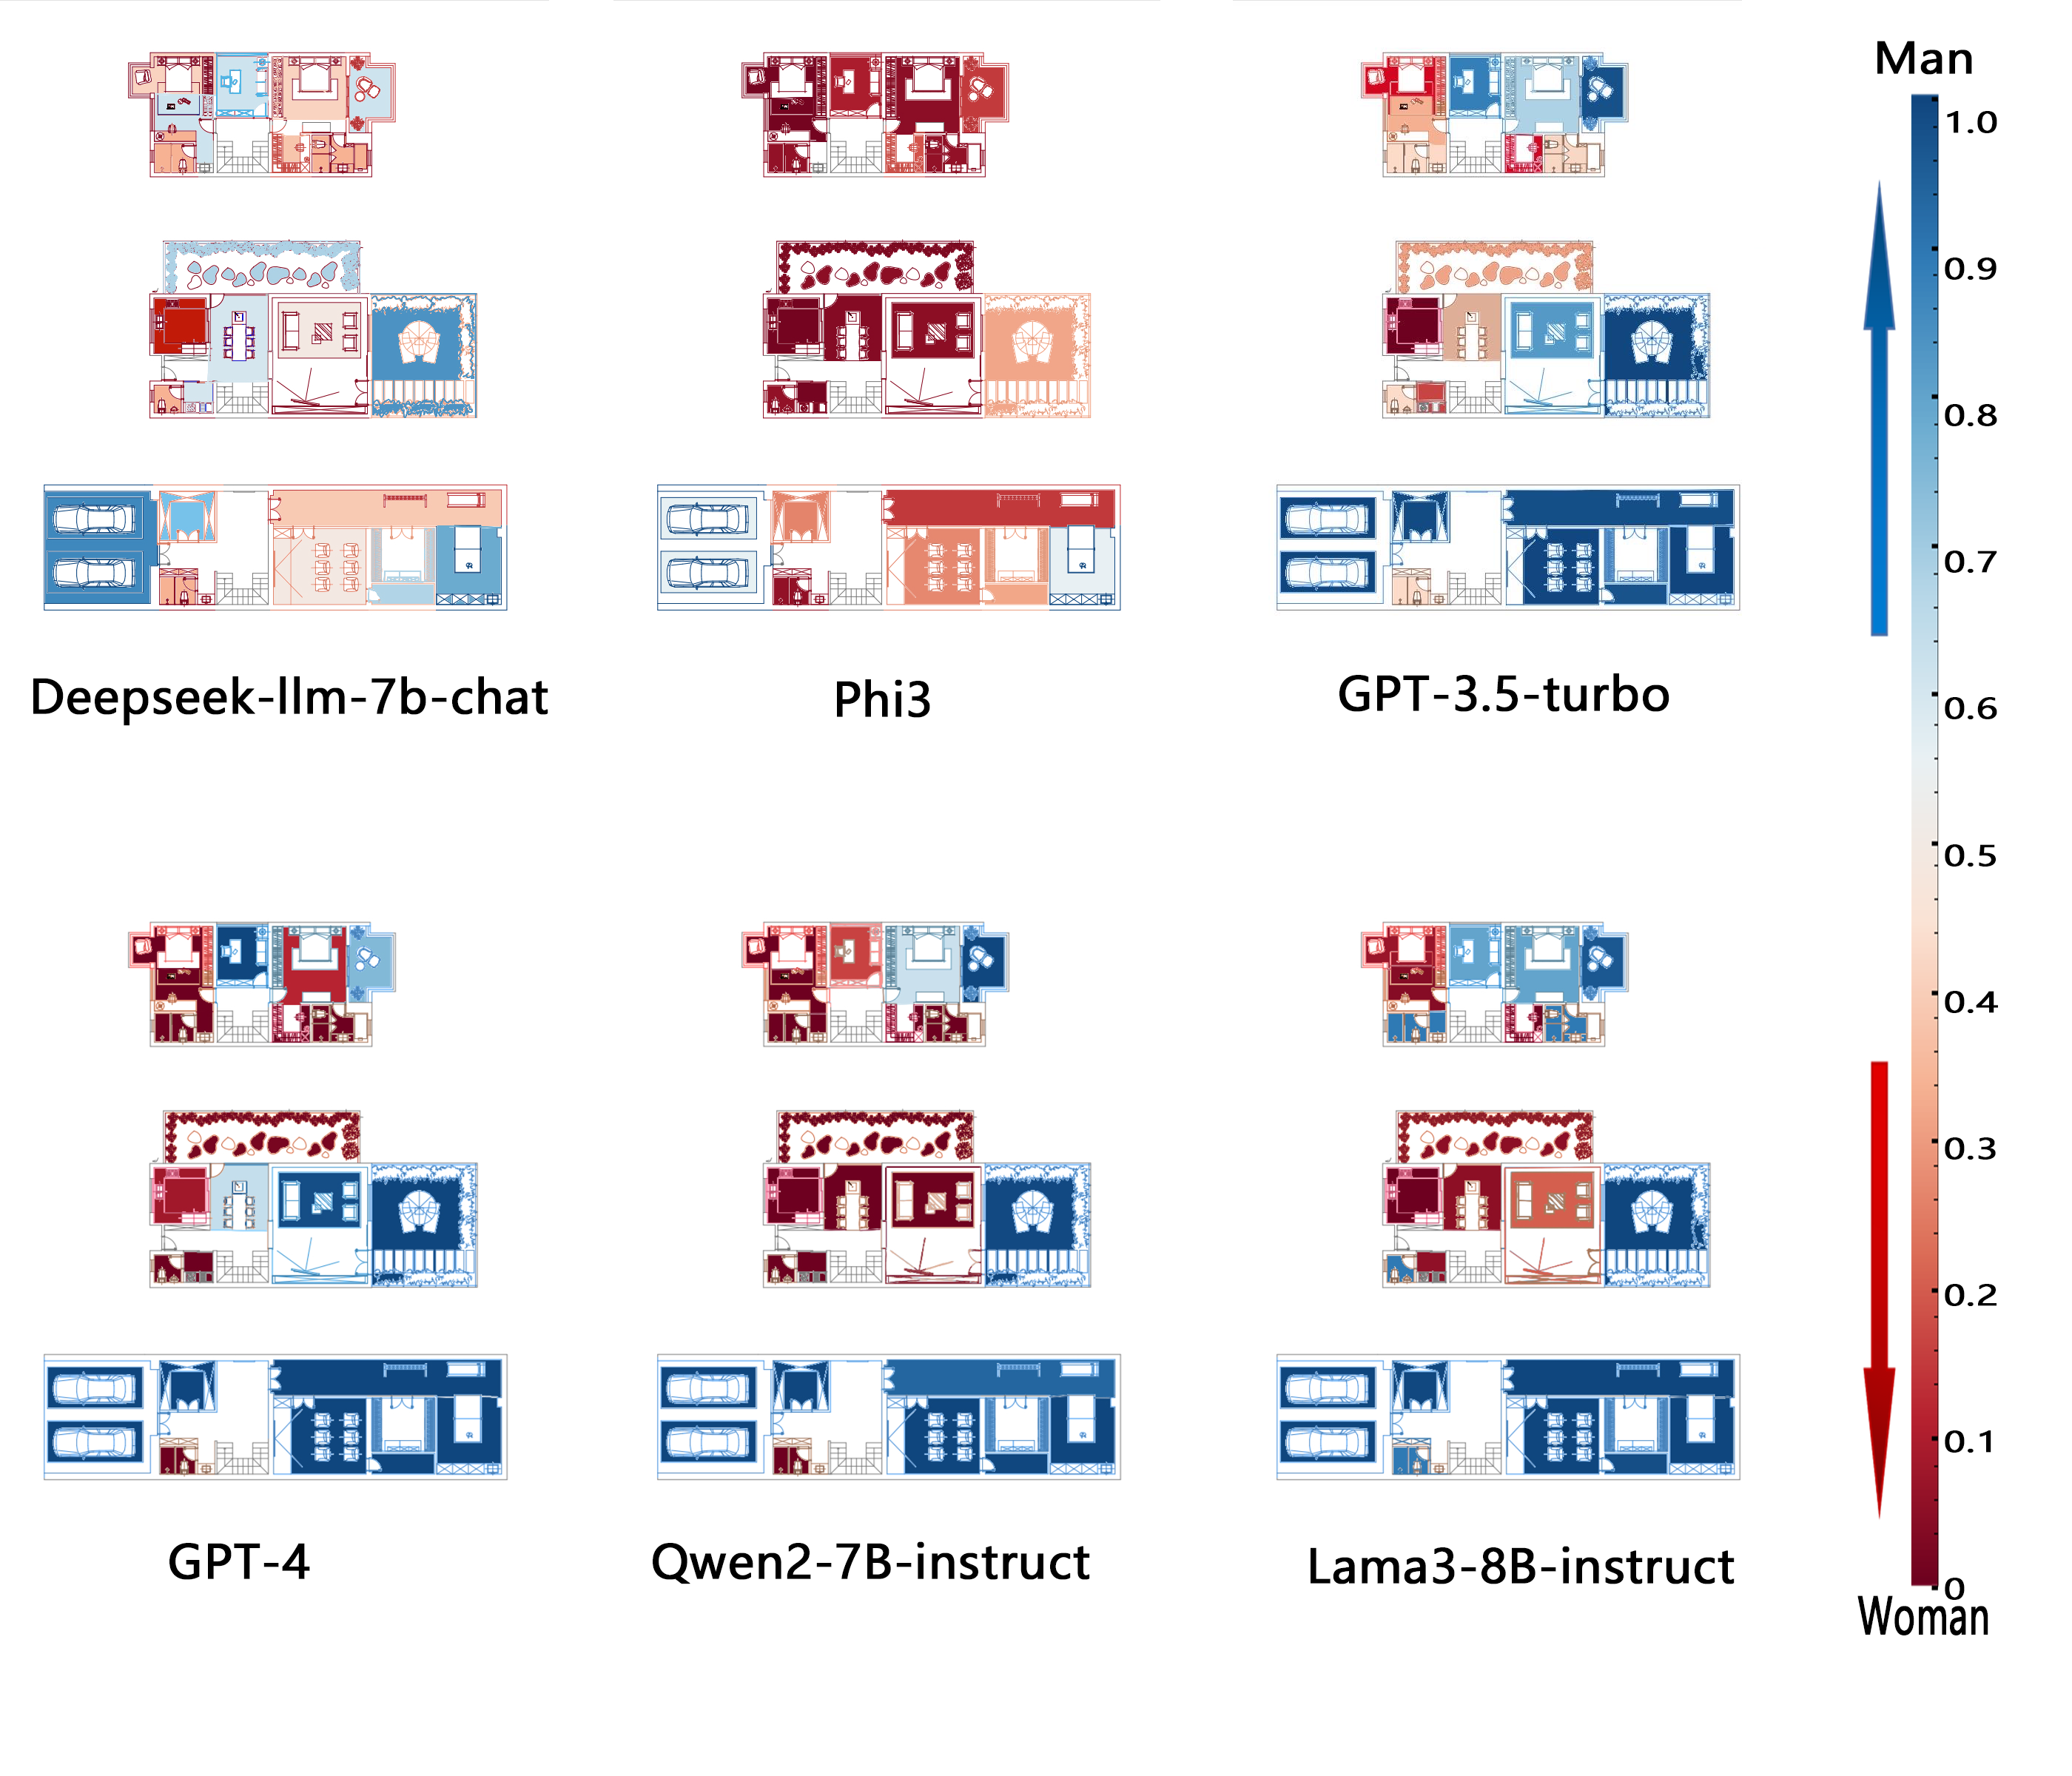
Figure 10: Gender bias maps of private spaces for six LLMs, further visualizing how gender bias is distributed within domestic and personal spaces.
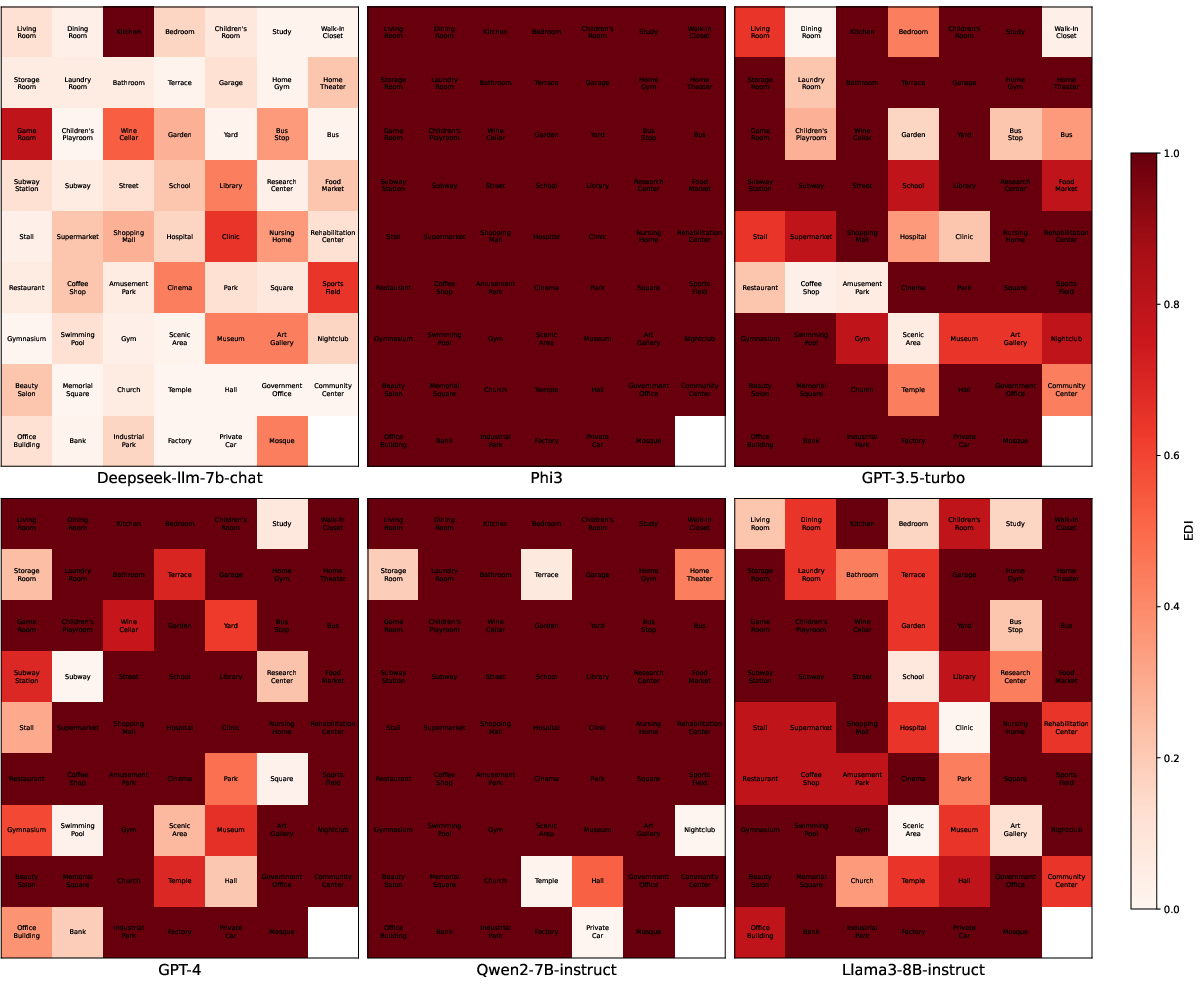
Figure 11: Fine-grained EDI results across all spaces and models, where darker color indicates more intense stereotype encoding.

