- The paper introduces a modular VLA framework that combines structured reasoning via a CoC dataset with trajectory planning in a three-stage training process.
- It employs the Cosmos-Reason backbone and diffusion-based decoder to achieve real-time performance, improving planning accuracy by 12% and reducing off-road events by 35%.
- The approach leverages reinforcement learning to align causal reasoning with decision-making, ensuring interpretable and robust outcomes in complex driving scenarios.
Alpamayo-R1: Bridging Reasoning and Action Prediction for Generalizable Autonomous Driving in the Long Tail
Introduction
"Alpamayo-R1" introduces a vision-language-action (VLA) model that integrates reasoning with trajectory planning to address the limitations of existing end-to-end autonomous driving models in safety-critical, long-tail scenarios. Despite advances in transformer-based architectures and large-scale datasets, these models struggle with reasoning and causal understanding. Alpamayo-R1 (AR1) aims to bridge this gap by using a structured chain-of-causation (CoC) dataset, a modular VLA framework, and a multi-stage training strategy.
Alpamayo-R1 Architecture
The AR1 architecture extends the Alpamayo-VA model with reasoning capabilities, utilizing the Cosmos-Reason VLM backbone and a diffusion-based trajectory decoder for real-time planning.
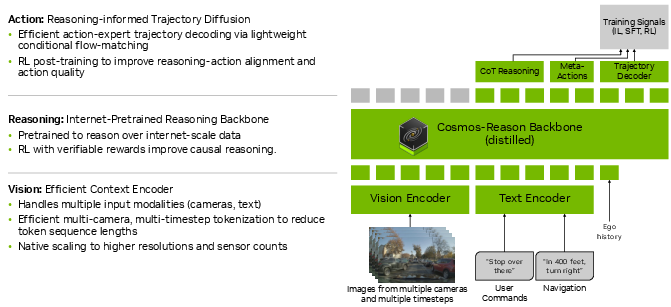
Figure 1: Overview of Alpamayo-R1 architecture. Multi-camera images and egomotion are processed by a vision encoder to produce visual tokens, which are fed into a VLM backbone (Cosmos-Reason) along with textual inputs.
The model inputs multi-camera, multi-timestep data along with optional textual inputs to produce reasoning traces and trajectory predictions. The architecture supports modular vision encoding and flexible action decoding through flow matching, ensuring real-time performance with a latency of 99ms.
Structured Chain of Causation Dataset
A key innovation in Alpamayo-R1 is the CoC dataset, which provides decision-grounded, causally linked reasoning traces aligned with driving behaviors. The labeling pipeline combines automated processes with human-in-the-loop methods to generate high-quality training data.
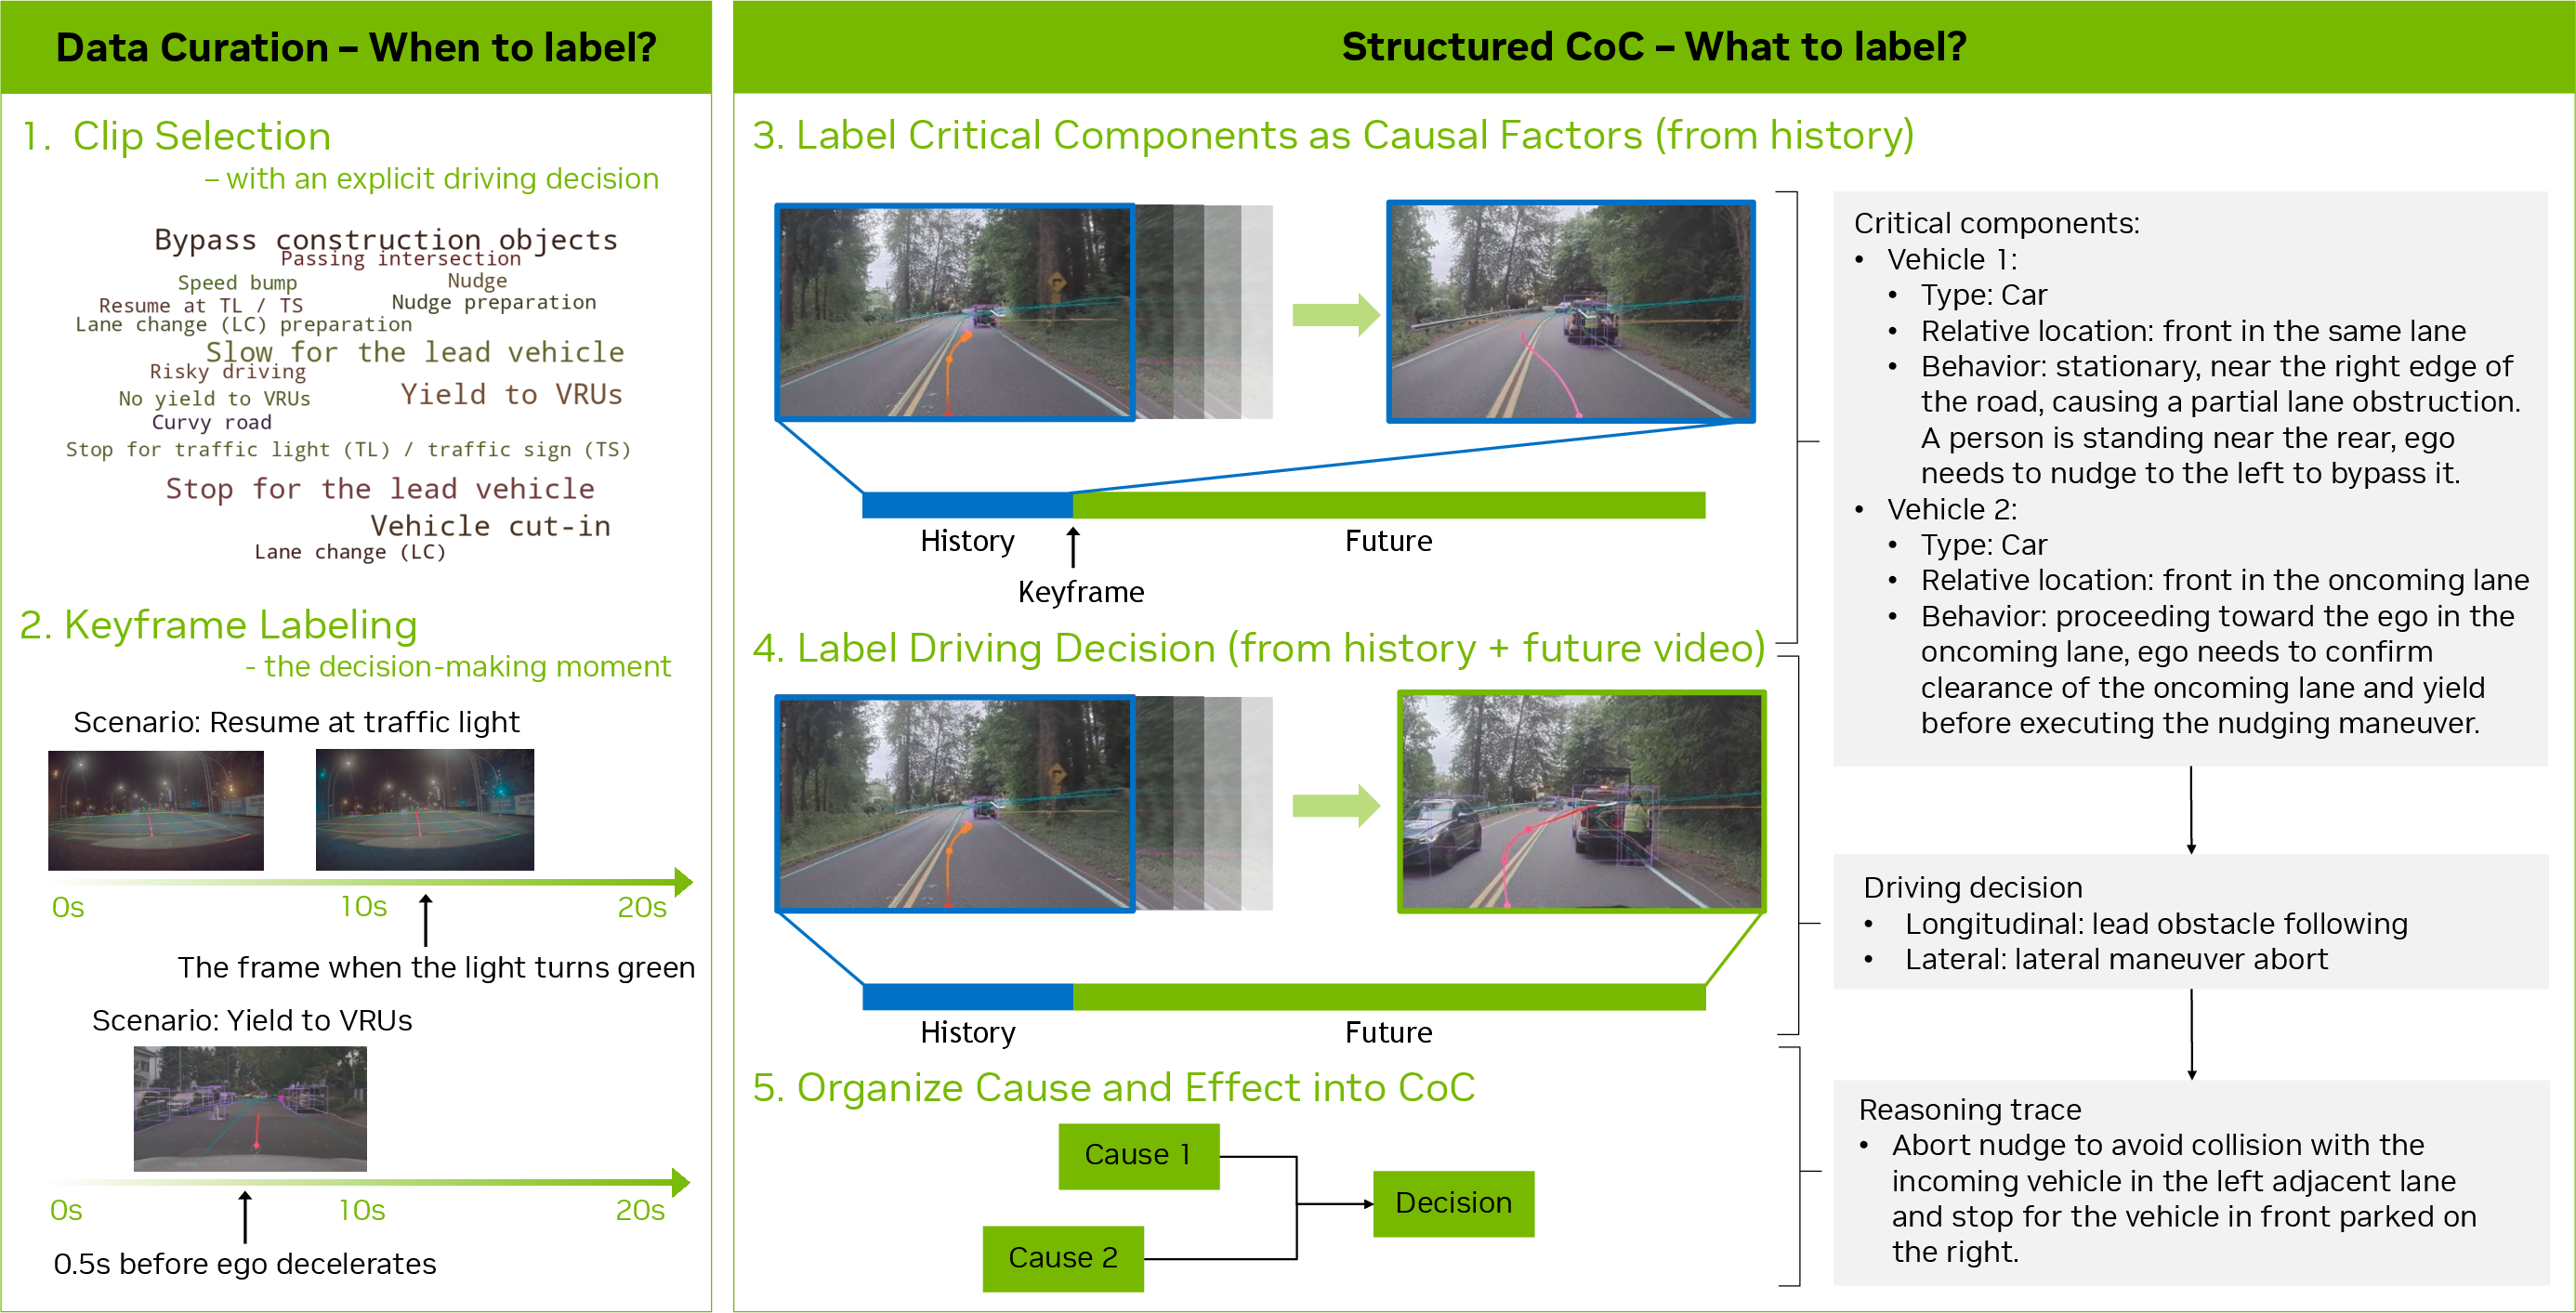
Figure 2: Overview of the proposed structured labeling pipeline, supporting scalable data generation for the CoC dataset.
The dataset enforces explicit causal structures, ensuring all reasoning traces are anchored to observable causal factors and linked to explicit driving decisions. It avoids vague or superficial reasoning commonly present in existing datasets, providing robust supervision for reasoning-based VLA tasks.
Training Strategy and Reinforcement Learning
The model undergoes a three-stage training process: initial action modality injection using discrete trajectory tokens, supervised fine-tuning on CoC data to elicit reasoning, and reinforcement learning (RL) for post-training alignment.
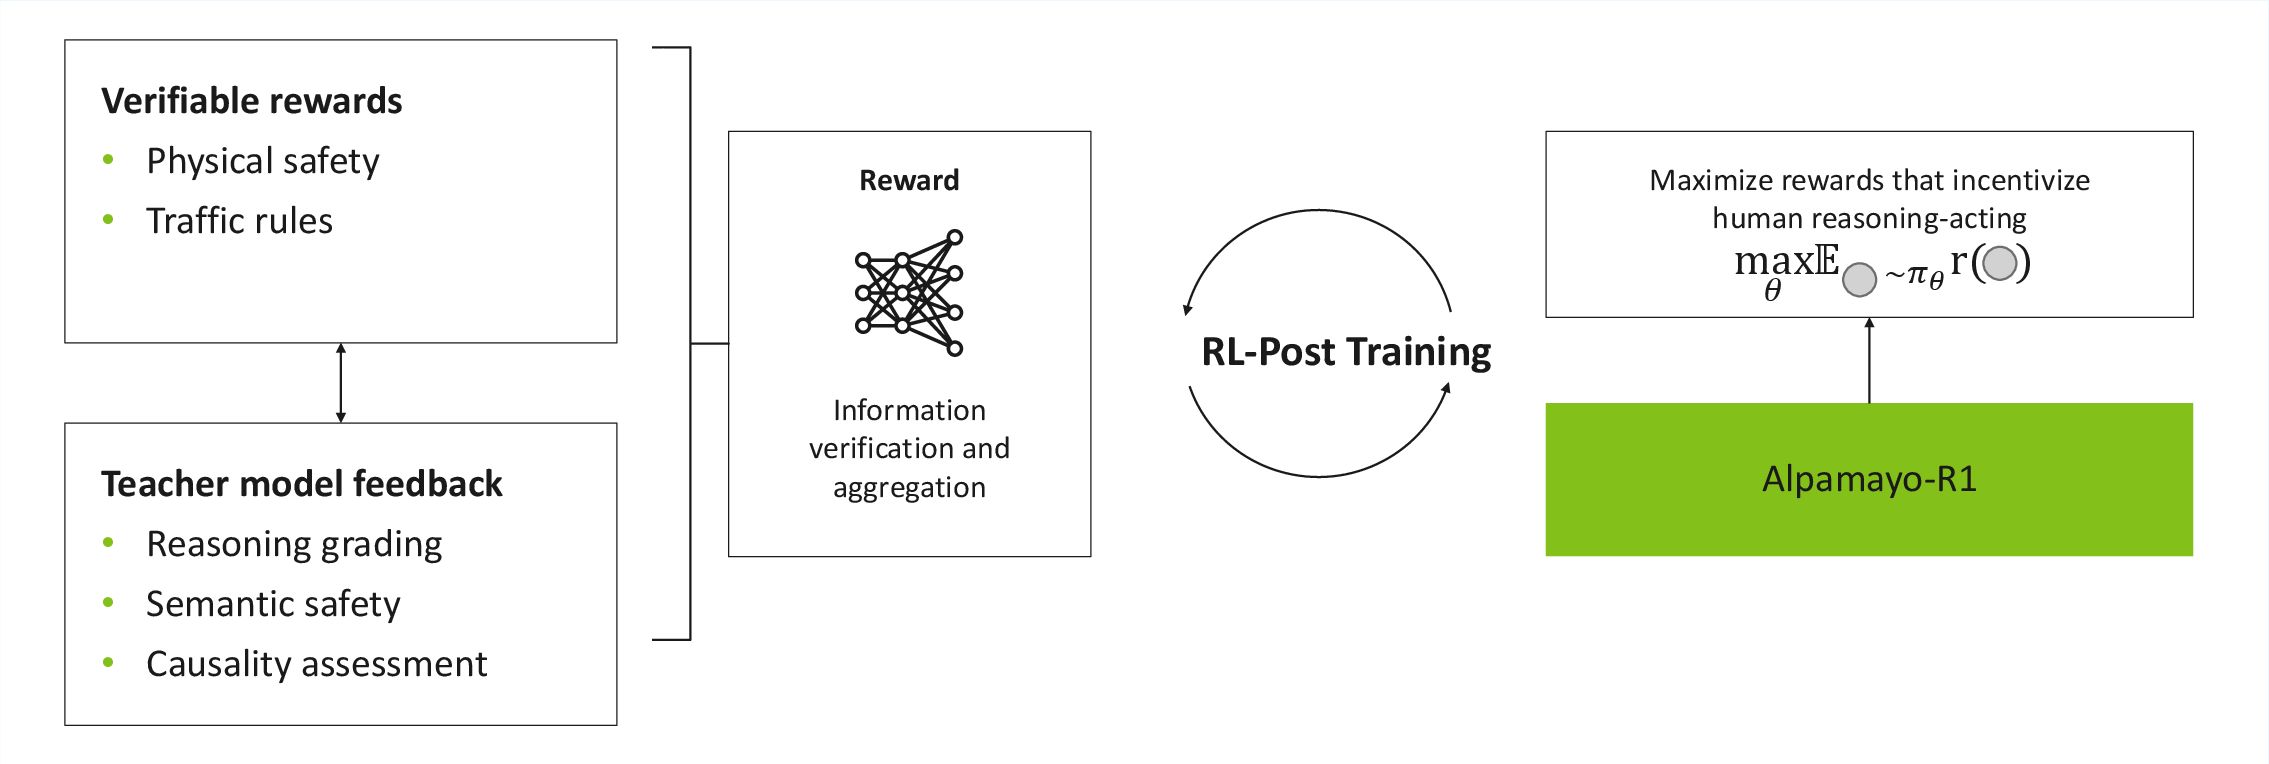
Figure 3: Overview of our RL-based post-training framework, optimizing reasoning quality and reasoning-action consistency.
RL optimizes reasoning quality, consistency with actions, and trajectory quality, using feedback from large reasoning models. This alignment ensures that the model's decisions are interpretable, contextually grounded, and aligned with generated actions.
Comprehensive evaluations demonstrate AR1's improvements over trajectory-only baselines, particularly in challenging scenarios requiring complex reasoning. The model achieves a 12% improvement in planning accuracy on challenging cases and a 35% reduction in off-road events in closed-loop simulations. AlpaSim simulations confirm safety and robustness improvements, validating the real-world applicability.
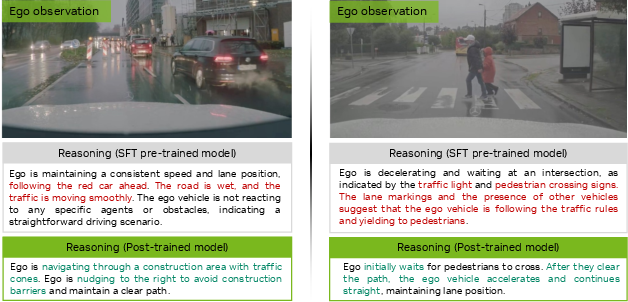
Figure 4: Post-training with the reasoning reward improves causal understanding in driving scenarios.
Conclusion and Future Work
Alpamayo-R1 demonstrates that integrating structured reasoning with decision-making bolsters autonomous driving systems, particularly in complex environments. Future developments will explore adaptive reasoning invocation and integration with learned world models for enhanced decision-making flexibility and robustness. The release of Alpamayo-R1 models and the CoC dataset will further advance research at the intersection of reasoning and autonomous driving.