Looped Diffusion Transformer: Depth Through Recurrence
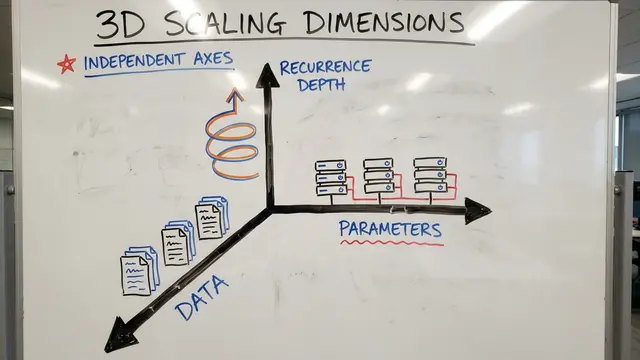
Looped Diffusion Transformer demonstrates that repeatedly applying shared Transformer blocks within each denoising step can outperform conventional scaling strategies in text-to-image generation. By refining hidden representations through multiple loops at fixed noise levels, a 260-million-parameter model surpasses models 6.5 times larger on compositional and spatial reasoning benchmarks while using substantially less inference compute. Deep supervision and self-modulating attention stabilize recurrent computation, enabling progressive visual correction and adaptive depth allocation based on prompt difficulty.Script
A 260-million-parameter model just beat a system 6.5 times larger at generating images from complex text prompts. The secret is depth through recurrence, not scale.
Looped-DiT partitions its 17 Transformer blocks into three stages. The middle five blocks are applied repeatedly, refining the hidden representation at each noise level within every denoising step.
Naive looping fails because repeated attention updates progressively erase spatial information. A ridge-regression probe reveals that coordinate decodability drops by 0.3 after eight loops, coinciding with performance collapse.
Deep supervision trains every intermediate loop state by decoding each into an image prediction and computing flow-matching loss. This stabilizes early representations and enables adaptive computation, where difficult prompts use more loops and simple ones exit early.
Exclusive Self Attention applies a state-dependent orthogonal projection that removes redundant updates from each attention head. This mechanism is parameter-free, preserves spatial information, and delivers a 1.6-point gain on compositional benchmarks where unmodulated attention would degrade the representation.
Looped-DiT achieves a 71.5 average score across six benchmarks, excelling on spatial relations, multi-object composition, and procedural constraints. Loop depth scales more efficiently than denoising steps or architectural width. Explore this work and generate your own video summaries at EmergentMind.com.