DeepSeek-V4.1-Flash: Pushing the Limits of KV Cache Compression
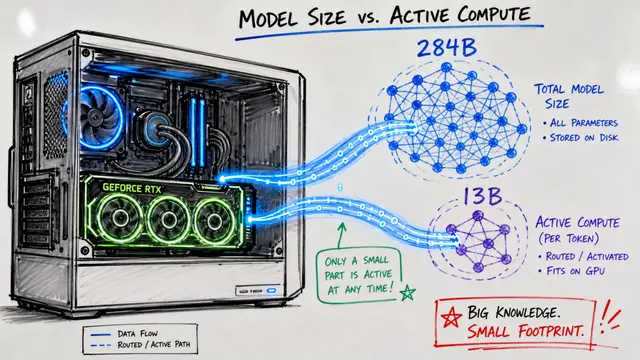
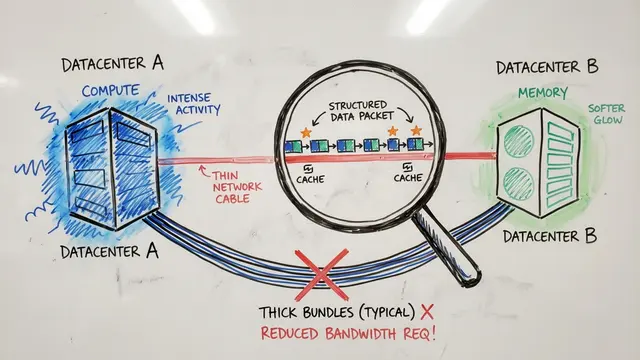
This lightning talk examines DeepSeek-V4.1-Flash, a 552B-parameter multimodal model that tackles the deployment bottleneck of long-context agents. Rather than treating attention arithmetic as the primary constraint, the authors redesigned the entire inference stack around KV-cache capacity, bandwidth, and prefill cost. Through coordinated changes to architecture, numerical precision, and deployment policy, they achieve a global cache footprint of just 890 bytes per token while supporting million-token contexts and maintaining competitive performance on coding and agentic benchmarks.Script
Long-context language models face a paradox. Attention arithmetic becomes cheaper with sparse methods, but the real bottleneck shifts to something most researchers overlook: the sheer memory footprint of storing key-value states for million-token conversations.
DeepSeek-V4.1-Flash splits its 40 layers into a causal encoder and decoder. The encoder processes the input normally, but decoder layers obtain their global key-value states by projecting from the final encoder representation, cutting prefill complexity nearly in half for long inputs.
Compressed Sparse Attention 2 goes further by sharing key-value cache across layers through three modes. Full mode computes everything fresh, Reindex mode reuses cache but recomputes sparse selections, and Reuse mode shares both cache and indices, eliminating redundant storage.
The cache entries themselves shrink to FP4 format, one scale per 16 channels, trained with quantization awareness during post-training. This drops the global runtime footprint to 890 bytes per token, roughly one quarter of its predecessor, with no measurable accuracy loss.
The model introduces controllable reasoning effort as a conditioning scalar. Increasing effort from 25 to 100 raises accuracy from 67% to 76% on reasoning benchmarks, at the cost of two and a half times more tokens. The tradeoff is real: longer trajectories don't guarantee better answers on every task.
DeepSeek-V4.1-Flash demonstrates that cache compression can coexist with competitive performance when architecture, precision, and deployment policy are codesigned. To explore this paper further or create videos from other research, visit EmergentMind.com.