- The paper introduces Programming by Rewards, a novel approach that synthesizes decision functions using black-box rewards combined with white-box decision structures.
- It employs a domain-specific language and continuous optimization techniques like gradient descent to efficiently tune parameters and reduce sample complexity.
- Empirical results in the PROSE codebase demonstrate that the method achieves competitive accuracy with fewer reward queries compared to traditional synthesis techniques.
Programming by Rewards and its Impact on Software Optimization
Introduction
The paper "Programming by Rewards" introduces a method called Programming by Rewards (PBR) that aims to synthesize programs using black-box rewards to optimize specific quantitative metrics such as performance, resource utilization, or correctness. This approach leverages a decision function encoded in a domain-specific language (DSL) containing loop-free if-then-else programs, and maximizes expected rewards through continuous optimization techniques.
Programming by Rewards (PBR) Framework
PBR differentiates itself from existing approaches by treating the decision-making code as a white-box to exploit its structure, while considering the reward function as a black-box component. This middle-ground approach allows for enhanced scalability in real-world implementations. The framework employs gradient descent and other continuous optimization techniques for the synthesis of decision functions, resulting in models that achieve greater accuracy and faster convergence compared to traditional RL techniques.
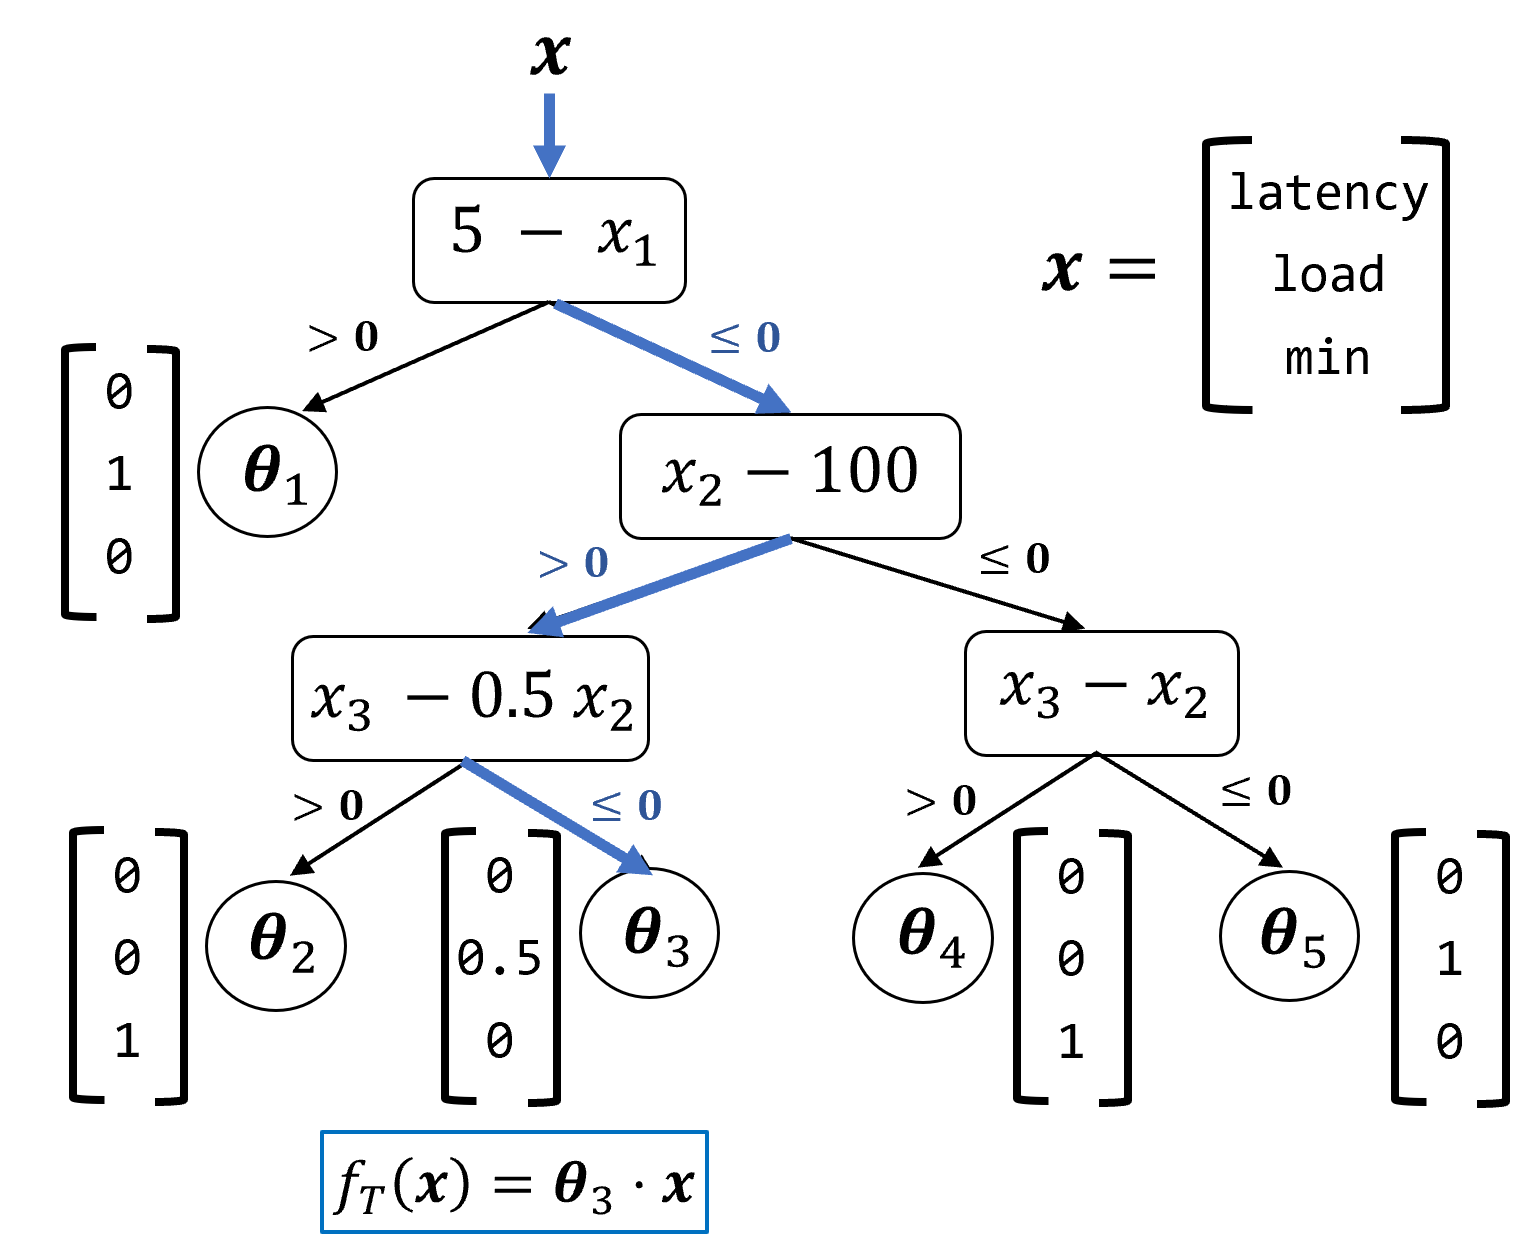
Figure 1: Example decision function in Imp (left) and its equivalent binary decision tree with linear models in leaf nodes (right).
Decision Functions and DSL
The decision functions addressed in this paper are motivated by real-world software scenarios like efficient search, ranking heuristics, and real-time services. They predominantly involve linear combinations of program variables and nested if-then-else conditions without loops. The authors define a DSL named Imp to articulate decision functions, modeling a typical pattern found in real-world programming practices.
Learning Decision Functions
The learning algorithms formulated for this study enable both offline and online learning settings. These algorithms aim to reduce sample complexity and time, balancing between computational resources and reward queries. For constant and linear functions, the algorithms provide theoretical guarantees under certain assumptions regarding reward function properties like concavity and Lipschitz continuity.
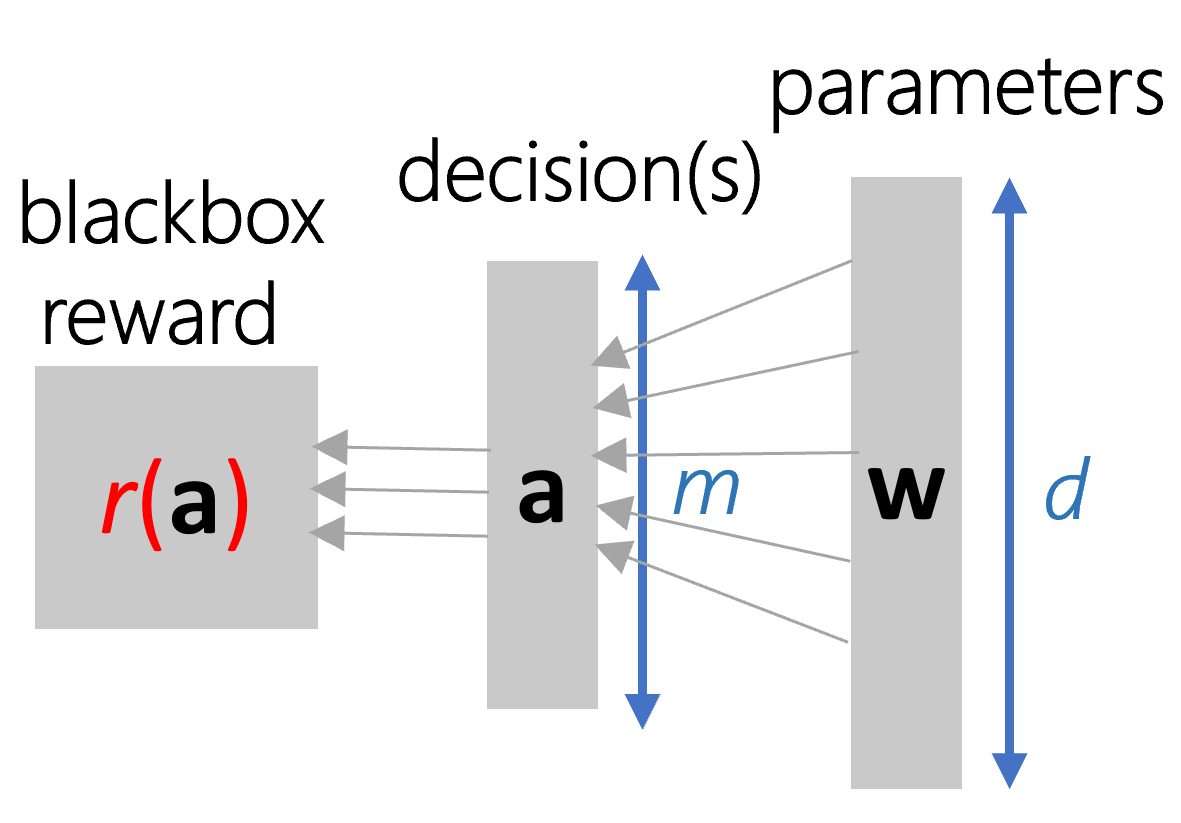
Figure 2: The black-box reward r modeled as r(), highlighting the relation where output =f(;)∈Rm, yet ∈Rd.
Empirical Evaluation and Implementation
The empirical studies validate the efficacy of PBR in synthesizing parameter-tuned decision functions, particularly within the PROSE codebase from Microsoft. The approach demonstrates improvements in real-world systems by achieving competitive accuracy levels with much fewer reward guesses compared to hand-tuned systems. Additionally, experiments comparing PBR to existing synthesis techniques and multi-arm bandit methods underscore PBR’s superior sample efficiency and computational performance.
Conclusion
The PBR framework presents a promising direction for integrating AI-driven optimization in programming, particularly by synthesizing interpretable and efficient decision-making functions that optimize complex reward functions. Future work involves refining the model guarantees and expanding the applicability across broader software environments.
In summary, this work represents a significant step forward in reducing the manual effort in parameter tuning while improving system performance by leveraging automated program synthesis techniques effectively integrated with AI-driven strategies.

