- The paper demonstrates GPT-5's clinical benchmarking by achieving 92.8% accuracy on the TXIT and 100% accuracy in select treatment planning tasks.
- It employs domain-specific evaluations and real-world oncologic vignettes to assess improvements in diagnosis, dosage, and treatment recommendation comprehensiveness.
- Results reveal marked gains over GPT-3.5 and GPT-4, yet persistent challenges such as hallucination necessitate ongoing expert oversight.
Benchmarking GPT-5 in Radiation Oncology: Measurable Gains, but Persistent Need for Expert Oversight
Introduction
The recent study titled "Benchmarking GPT-5 in Radiation Oncology: Measurable Gains, but Persistent Need for Expert Oversight" evaluates the efficiency and applicability of the GPT-5 LLM in the field of radiation oncology (2508.21777). GPT-5 is assessed using two benchmarks: the American College of Radiology Radiation Oncology In-Training Examination (TXIT) and a set of real-world oncologic vignettes. The study's objective is to quantify GPT-5's accuracy while identifying its potential limitations and ensuring data transparency for clinical application.
This study observed that GPT-5 achieves a significant increase in performance compared to its predecessors, GPT-3.5 and GPT-4, in the standardized TXIT test by encompassing both multiple-choice and visual interpretation items. The results demonstrated a mean accuracy of 92.8%, outperforming prior models that achieved 62.1% for GPT-3.5 and 78.8% for GPT-4.
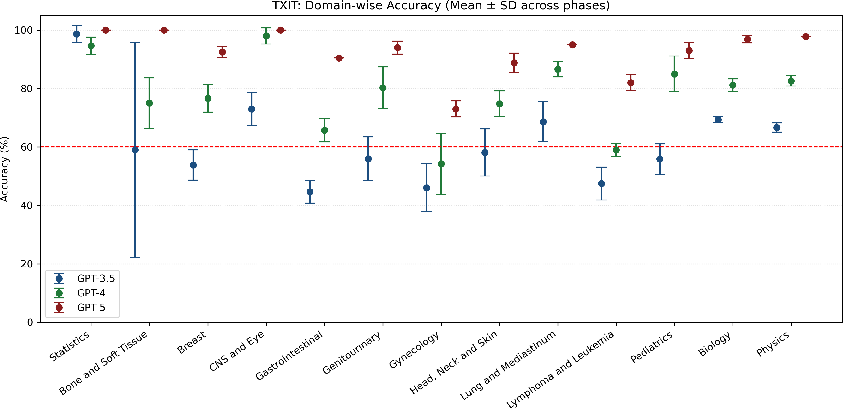
Figure 1: TXIT accuracy by model. Symbols show mean accuracy and error bars indicate the standard deviation (SD) across five runs for GPT-3.5, GPT-4, and GPT-5.
Domain-Specific Accuracy
In domain-specific evaluations, GPT-5 exhibited superior performance in several critical areas such as dose specification and diagnosis. Significant improvements were noted in categories involving Treatment Planning, Local Control, and Prognosis Assessment, achieving 100% accuracy in multiple areas. Conversely, challenges persist in complexity-demanding topics like Gynecology and fine-grained dosimetry tasks.
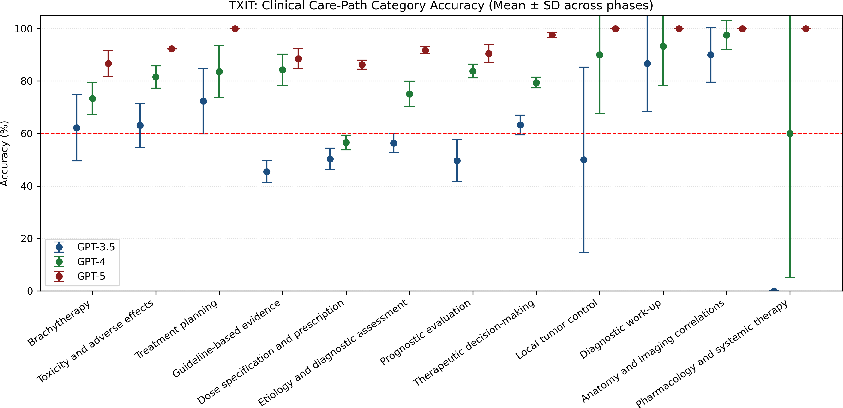
Figure 2: Domain-wise accuracy across models. Symbols show mean accuracy and error bars indicate the SD across five runs for GPT-3.5, GPT-4, and GPT-5.
Real-World Oncologic Vignette Evaluation
In a set of 60 authentic oncological case vignettes, GPT-5's suggestion capabilities were rigorously evaluated on correctness and comprehensiveness. A positive performance was observed, with a correctness mean of 3.24/4 and comprehensiveness increasing to 3.59/4. The study highlighted GPT-5's ability to draft complex treatment recommendations, though inter-rater variability indicated the necessity of further clinical judgement integration.
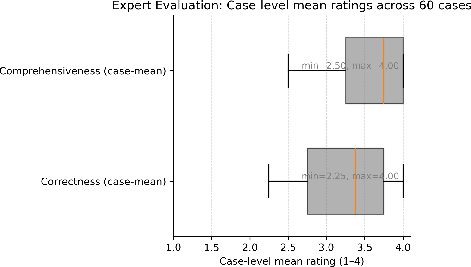
Figure 3: Distribution of case-level mean expert ratings for correctness and comprehensiveness across 60 cases. Each box represents the inter-quartile range (IQR) with whiskers indicating outliers, summarizing the distribution of ratings. Case-level mean correctness ranged from 2.25 to 4.00, while case-level mean comprehensiveness ranged from 2.50 to 4.00.
Hallucination and Variability
The phenomenon of hallucination, while scarce, represented a persistent issue. Hallucination rates varied across different tumor sites, primarily emerging in settings where accurate, explicit knowledge of trials was necessary.
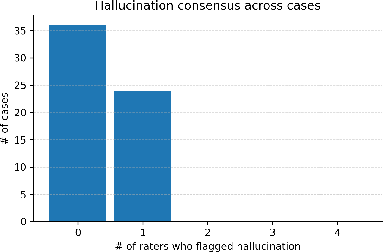
Figure 4: Hallucination consensus across cases. Bars show the number of cases with 0, 1, 2, 3, or 4 raters flagging hallucination. In this cohort, 36/60 cases had 0 flags and 24/60 had exactly 1 flag.
Conclusion
GPT-5 provides notable improvements over its precursors in the domain of radiation oncology, especially in terms of accuracy and reasoning in structured exams and real-world vignettes. Nonetheless, a key limitation highlighted is the need for expert oversight due to hallucination instances and inter-rater variability. This research underscores GPT-5's role as a model exceptionally suited for augmentative decision-support functionalities in oncological practice rather than autonomous decision-making tools. As the LLM continues to develop, future studies must focus on incorporating real-time guideline updates, dose references, and tighter integration within a multi-modal ecosystem for enhanced clinical applicability.