Papers
Topics
Authors
Recent
Search
2000 character limit reached

An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale

Published 22 Oct 2020 in cs.CV, cs.AI, and cs.LG | (2010.11929v2)

Abstract: While the Transformer architecture has become the de-facto standard for natural language processing tasks, its applications to computer vision remain limited. In vision, attention is either applied in conjunction with convolutional networks, or used to replace certain components of convolutional networks while keeping their overall structure in place. We show that this reliance on CNNs is not necessary and a pure transformer applied directly to sequences of image patches can perform very well on image classification tasks. When pre-trained on large amounts of data and transferred to multiple mid-sized or small image recognition benchmarks (ImageNet, CIFAR-100, VTAB, etc.), Vision Transformer (ViT) attains excellent results compared to state-of-the-art convolutional networks while requiring substantially fewer computational resources to train.

Citations (33,045)

Summary

  • The paper introduces the Vision Transformer (ViT) that replaces CNNs with a Transformer-based approach by processing 16x16 image patches.
  • It demonstrates state-of-the-art accuracy, achieving 88.55% on ImageNet and 94.55% on CIFAR-100 after extensive pre-training.
  • The study highlights how self-attention mechanisms in ViT enhance computational efficiency and scale image recognition tasks effectively.

Image is Worth 16x16 Words: Transformers for Image Recognition at Scale

Introduction

The paper "An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale" introduces the Vision Transformer (ViT), a novel approach to image recognition that leverages the Transformer architecture, traditionally successful in NLP, for computer vision tasks. This approach bypasses convolutional networks entirely, relying on self-attention mechanisms applied to patches of images to perform classification tasks.
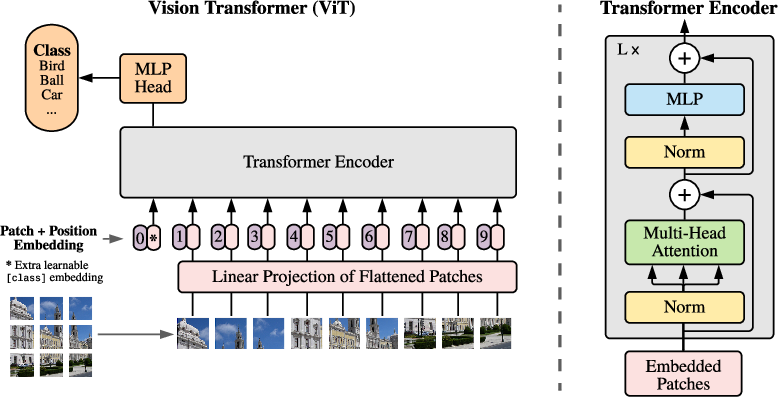
Figure 1

Figure 1: Model overview - splitting an image into fixed-size patches and processing them using a Transformer encoder.

Methodology

Model Architecture

ViT treats images as sequences of flattened patches fed into a Transformer model, resembling its application in NLP. The architecture consists of:

  1. Image Patching: Images are split into non-overlapping patches of size 16x16 pixels.
  2. Linear Embedding: Each patch is flattened and linearly embedded into a constant vector size DD.
  3. Sequence Formation: A learnable classification token is prepended, and positional embeddings are added to retain spatial information.
  4. Transformer Encoder: A standard Transformer encoder processes the sequence, leveraging multi-head self-attention and feedforward layers.

This architecture is depicted in Figure 1, providing a straightforward yet scalable model design.

Training and Fine-tuning

ViT models require extensive pre-training on large datasets such as ImageNet-21k or JFT-300M. The tasks are then fine-tuned to smaller datasets, showing impressive transfer capabilities. Fine-tuning often involves increasing the resolution, thereby increasing the input sequence length managed by 2D interpolation of position embeddings.

Experimental Results

Performance Analysis

ViT proves competitive, achieving strong results on multiple datasets. For instance, ViT achieves an 88.55% accuracy on ImageNet and 94.55% on CIFAR-100 when pre-trained on JFT-300M. These results affirm the potential of Transformers in vision when coupled with sufficient pre-training data.
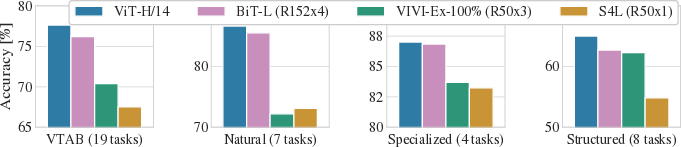
Figure 2

Figure 2: Breakdown of VTAB performance across Natural, Specialized, and Structured task groups.

The Transformer-based approach also scales favorably with increased data size, outperforming equivalent CNN-based models and demonstrating significant gains in computational efficiency Figure 2.

Attention Insights

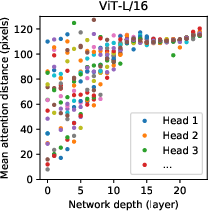
An important aspect investigated is how ViT utilizes attention. Analysis reveals that initial layers tend to focus on local patterns, with deeper layers attending to broader image contexts. This flexibility allows ViT to arguably leverage global image context more effectively than traditional CNNs.
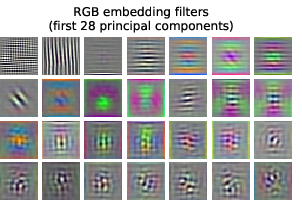
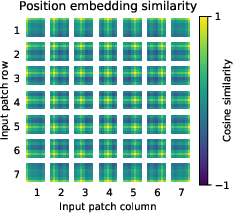
Figure 3

Figure 3

Figure 3

Figure 3: Initial linear embedding and attention distance analysis show the adaptability and extensive reach of ViT’s attention mechanisms.

Self-Supervision

Preliminary attempts at self-supervised learning with ViT showed promise but trailed behind supervised methods, suggesting further exploration is needed to fully harness self-supervised pre-training in vision domains.

Conclusion

ViT showcases the potential to apply Transformer architectures to computer vision tasks, achieving state-of-the-art performance with reduced training costs compared to CNNs. The research opens a pathway for further exploration into applying Transformers across varied vision tasks like object detection and segmentation, particularly with refined self-supervised learning strategies. Future developments should consider scaling up not just the models but optimally leveraging pre-training across diverse datasets for maximal gains.

Paper to Video (Beta)

No one has generated a video about this paper yet.

Whiteboard

No one has generated a whiteboard explanation for this paper yet.

Open Problems

We haven't generated a list of open problems mentioned in this paper yet.

Tweets

Sign up for free to view the 41 tweets with 208 likes about this paper.

YouTube

An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale (Paper Explained) 399K views
Sora - Full Analysis (with new details) 245K views
为啥所有AI都数不清手指?包括GPT5 75K views
Sora 真有那麼神?來看看 Sora 是怎麼訓練跟生成影片吧!|泛科學院 #openai #chatgpt #sora #ai #video 56K views
Visualization of embeddings with PCA during machine learning (fine-tuning) of a Vision Transformer 55K views
Vision Transformer - Keras Code Examples!! 44K views
An image is NxN words | Transformers in vision: ViT, DiT, MMDiT 37K views
The Mathematical Foundations of Intelligence [Professor Yi Ma] 37K views
LLM Chronicles #6.3 Multi-Modal LLMs for Image, Sound and Video 34K views
Adding vs. concatenating positional embeddings & Learned positional encodings 26K views
Vision Transformers - Explained! 20K views
How Do Vision Transformers Work? ViT Explained 14K views
【DeepLearning研修】Transformerの基礎と応用 -- 第1回 Transformerの基本 13K views
EZ撸paper: DeepSeek-R1 论文详解 part 3:GPT发展史 | scaling law | 训练范式 | emergent ability #deepseek 12K views
Multimodal Embeddings: Introduction & Use Cases (with Python) 10K views
AIs can now imagine video games in real-time 9.8K views
Transformers in Computer Vision 9.8K views
SORA Video To Video Is Literally Mind Blowing - 12 HD Demos - Changes Industry Forever For Real 9.5K views
The Entire History of Convolutional Neural Networks for Image Classification! 7.2K views
DINOv3: One backbone, multiple image/video tasks 6.9K views
"AGI will Simulate Real World" says Sora Creators 6.5K views
AI Engineering Paper #3: Vision Transformer (ViT) for Images 5.8K views
Vision Transformer (ViT) Paper Explained 5.8K views
An Image Is Worth 16x16 Words - Paper Explained 5.5K views
The Vision Transformer Model (ViT) 5.3K views
How LLMs Actually Understand Images. 5.3K views
Vision transformer in python | computer vision شرح عربي 4.5K views
Vision Transformer (ViT) 4.5K views
How ChatGPT Vision Works | Technical Breakdown 4.1K views
Hybrid Vision Transformer Model (ViT) 3.7K views
【画像認識の代表的なモデル#13】Vision Transformer(2020) 3.5K views
ResNet50 ViT - Vision Transformer with ResNet50 | computer vision شرح عربي 3.5K views
sudoremove 예능, 가볍게 보세요, AI 논문 월드컵, 만약 스카이넷이 생긴다면, 과거로 가서 없에야 할 논문은? 2.8K views
Mobile Vision Transformers part 1 | Depth-wise and Point-Wise Convolution عربي 2.6K views
Vision Transformer itu cuma......... 2.6K views
Visualizing Attentions in Vision Transformer (PyTorch Image Models-timm using PyTorch forward hook) 2.5K views
【DeepLearning研修】Transformerの基礎と応用 --第3回 Transformerの画像での応用 2.4K views
Fine Tuning Vision Transformer 2.1K views
Vision Transformer on SageMaker, part 1: dataset preparation 1.9K views
Vision Transformer (ViT) Explained | Theory + PyTorch Implementation from Scratch 1.9K views
Mobile Vision Transformers in python part 2 | MobileVit block شرح عربي 1.7K views
Vision Transformers: How and why they work? 1.5K views
【画像認識の代表的なモデル#12】EfficientNet(2019) 1.4K views
Обучаю нейросеть для ВИДЕО методом Sora. Университет Пекина разрабатывает Sora с открытым кодом 1.4K views
Reading ViT (Vision Transformer) PyTorch source code 1.3K views
Vision Transformer (ViT) 1.3K views
ViT: An Image is Worth 16x16 Words Explained 1.2K views
Top AI Research Papers for Beginners - in 2024 1.2K views
Vision Transformer 1.1K views
Self-Attention in Neural Networks / iGibson - December 14, 2020 1.1K views