- The paper demonstrates that LLM-as-a-Judge can achieve up to 79.11% Pearson correlation with human evaluators in code translation tasks.
- It compares various LLM methods across code translation, generation, and summarization, highlighting performance differences using empirical evaluation metrics.
- The study indicates that while LLMs show promise in specific SE tasks, they face challenges in nuanced evaluations like pairwise comparisons and summarization.
Can LLMs Replace Human Evaluators? An Empirical Study of LLM-as-a-Judge in Software Engineering
Introduction
This paper explores the viability of using LLMs as automated evaluators for Software Engineering (SE) tasks, coining the term "LLM-as-a-Judge". Traditional metrics like Pass@k and BLEU have limitations either due to their high resource requirements or their lexical focus rather than semantic understanding. The research investigates LLMs' alignment with human judgment through an empirical study, particularly focusing on code translation, generation, and summarization tasks.
Methodology
Task and Model Selection
The study selects seven LLM-as-a-Judge methods, utilizing both general-purpose and SE-specific fine-tuned models. The tasks examined include code translation from the CodeTransOcean, code generation from ComplexCodeEval, and code summarization from CodeXGLUE. Each task involves generating responses which are scored both manually and via automated methods.
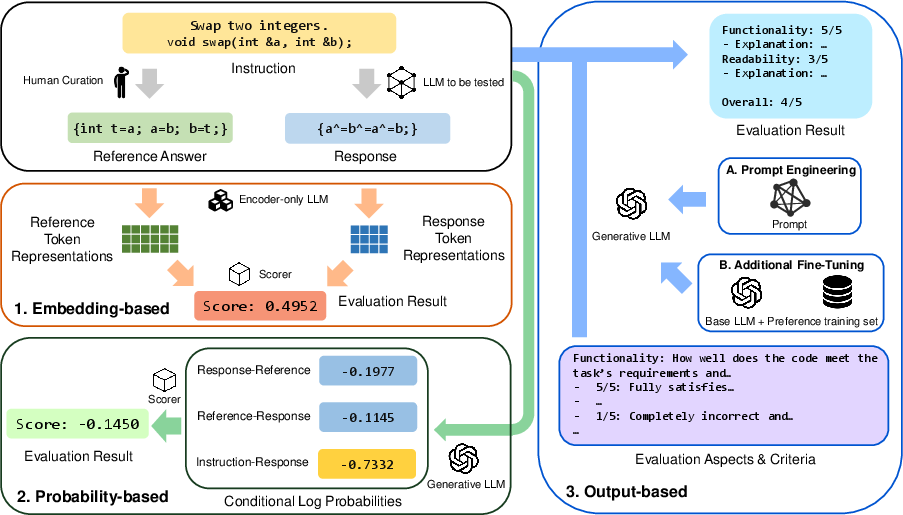
Figure 1: Overview of different LLM-as-a-judge methods.
Evaluation Metrics
For evaluation alignment, metrics such as Pearson correlation coefficients are used to compare LLM-generated scores with human evaluators. The study designs research questions focusing on alignment performance, score distribution characteristics, and the efficacy of pairwise comparison versus individual scoring.
Results
Alignment with Human Evaluators
The study finds that output-based LLM-as-a-Judge models using LLMs like GPT-4o outperform conventional methods, providing high Pearson correlations of up to 79.11% in code translation and somewhat less in code generation with 68.51%. Notably, no substantial superiority is observed in code summarization tasks where conventional methods slightly outperform LLM-based evaluations.
Score Distribution Characteristics
LLM-as-a-Judge methods using large models exhibit score distributions closely resembling human scoring patterns. They manage to cover a more balanced range of scores, unlike embedding-based methods which closely mirror lexical-based similarity metrics like BLEU.
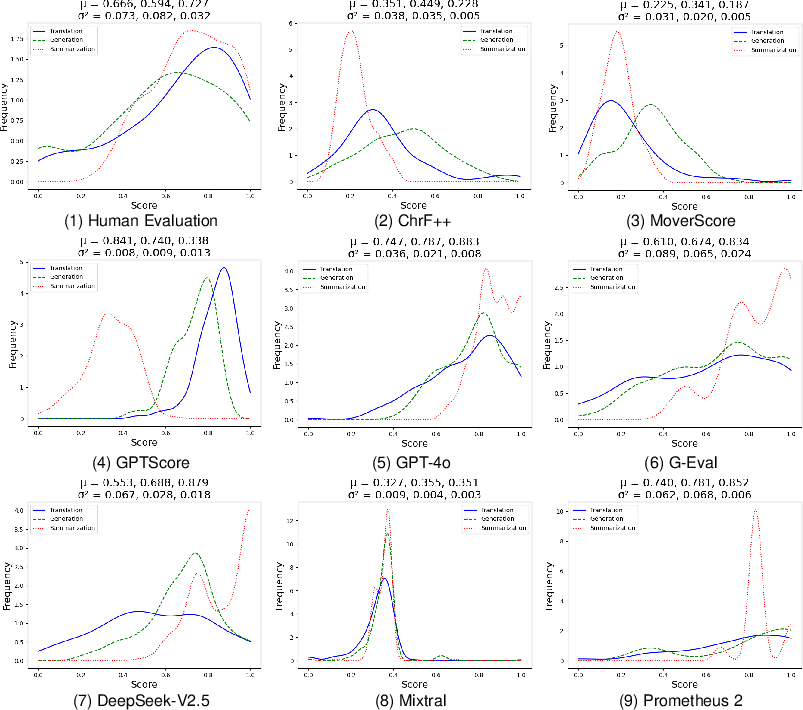
Figure 2: Score distributions of selected metrics. μ,σ2 refer to the means and variances of scores for code translation, code generation, and code summarization. All scores are rescaled into range [0,1].
Pairwise Comparison
Methods struggled with pairwise comparisons, often yielding inconsistent results. Despite achieving certain accuracy improvements in translation tasks, these methods displayed low agreement levels when the order of response pairs changed, highlighting current challenges in using LLMs for this specific evaluation strategy.
Discussion
The research indicates that current LLM-as-a-Judge methods can potentially replace human evaluators for certain SE tasks, such as code translation, where high alignment is observed. However, for code summarization, these methods are less effective. This highlights the need for task-specific calibration of LLM evaluators. Additionally, the exploration into different inference strategies such as Chain-of-Thought (CoT) prompting and batch evaluations show minimal gains, suggesting that simple text-output-based methods with advanced LLMs are currently optimal.
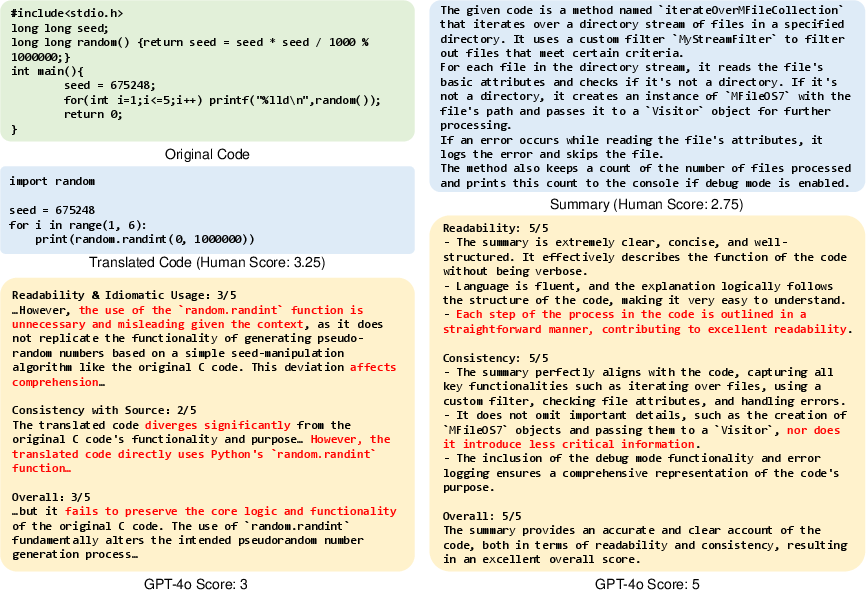
Figure 3: Case study. The successful case from code translation is on the left while the failing case from code summarization is on the right.
Conclusion
The study concludes that while LLM-as-a-Judge methods offer promising alternatives for evaluating SE tasks like code translation and generation, significant challenges remain, particularly in tasks that require more nuanced evaluation such as summarization. Future research should focus on developing LLMs fine-tuned for SE tasks, bridging gaps in NLP and SE evaluations, and improving evaluation-based inference strategies.

